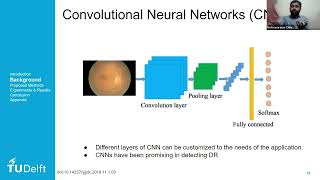
TinyML Talks Germany - Neural Network Framework Using Emerging Technologies for Screening Diabetic
Innovative framework using neural networks and emerging technologies for efficient screening of Diabetic Retinopathy, achieving high accuracy and significant improvements in energy consumption and latency.
TinyML for All: Full-stack Optimization for Diverse Edge AI Platforms
Full-stack optimization for edge AI platforms, addressing challenges in model compression, neural architecture rebalancing, and design primitives to deploy real-world AI on tiny microcontroller units despite limited resources.
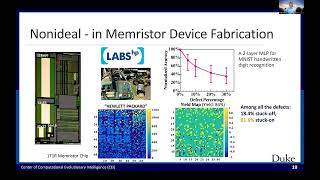
TinyML Talks - Software-Hardware Co-design for Tiny AI Systems
Explore efficient AI models, hardware-friendly compression, and topology-aware design for resource-constrained systems. Learn cross-optimization techniques and distributed learning for scalable AI solutions.
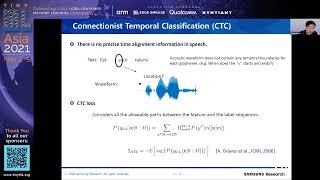
On-Device Neural End-to-End Speech Recognition and Synthesis Algorithms - A Review
Comprehensive review of on-device neural speech recognition and synthesis algorithms, exploring end-to-end models, optimization techniques, and their potential for on-device implementation.
Extremely Low-Bit Quantization for Transformers - tinyML Asia 2021
Explore extremely low-bit quantization techniques for Transformers, focusing on mixed precision strategies to optimize deployment on resource-limited devices without compromising accuracy.
Putting AI on a Diet: TinyML and Efficient Deep Learning
Efficient deep learning techniques for deploying AI on resource-constrained devices, including model compression, neural architecture search, and new design primitives for various applications.
Networks Within Networks - Novel CNN Design Space Exploration for Resource-Limited Devices
Explore novel CNN design for resource-limited devices using "network within network" paradigm. Learn automated method for compressing neural networks while preserving accuracy and meeting size constraints.
Speech Recognition on Low Power Devices
Explore multilingual speech recognition on low-power devices, covering model optimization techniques, neural network compression, and practical demonstrations for efficient implementation.
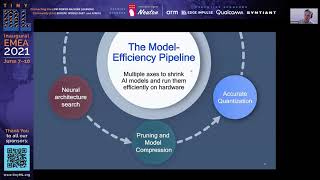
The Model Efficiency Pipeline: Enabling Deep Learning Inference at the Edge
Explore optimizing deep learning for edge devices through model efficiency techniques, including neural architecture search, pruning, quantization, and conditional processing.
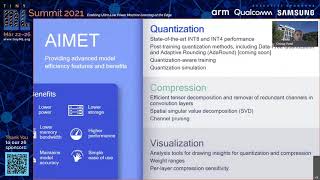
Advanced Network Quantization and Compression Using AIMET - tinyML Summit 2021
Explore advanced network quantization and compression techniques using AIMET to optimize AI models for efficient deployment on end devices, addressing memory, compute, and energy constraints.
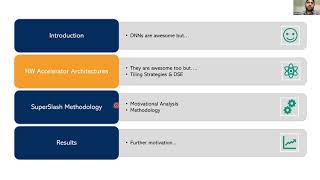
TinyML Talks Pakistan - SuperSlash - Unifying Design Space Exploration and Model Compression
Unifying design space exploration and model compression for efficient deep learning accelerators on resource-constrained devices, optimizing off-chip memory access and model size.
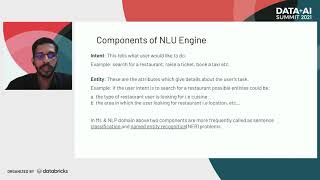
Conversational AI with Transformer Models - Building Blocks and Optimization Techniques
Explore building conversational AI agents using transformer models, covering advantages over RNN/LSTM, knowledge distillation, and model compression techniques for efficient production deployment.
No Data? No Problem: Zero-Data Model Training with Foundational Models
Explore zero-data model training using foundational models to create task-specific models without new data. Learn techniques for leveraging open-source tools in your projects.
Optimizing Knowledge Distillation Training With Volcano
Explore knowledge distillation optimization using Volcano for efficient model compression, leveraging online GPU clusters and idle resources to enhance training throughput and flexibility.
거대 인공지능 모델 시대에 스타트업의 차별화 방향 - AI 모델 경량화 기술을 중심으로
Discover how startups can differentiate through AI model optimization and edge computing, focusing on lightweight neural networks for wearable devices while maintaining high performance.
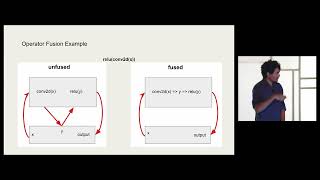
Efficient Inference of Extremely Large Transformer Models
Explore techniques for optimizing large transformer models, including compression, efficient attention, and parallelism for faster, smaller, and cost-effective inference.
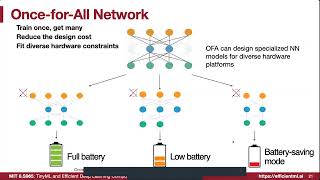
TinyML and Efficient Deep Learning Computing - Course Summary
Explore efficient machine learning techniques for deploying neural networks on resource-constrained devices, covering model compression, pruning, quantization, and more.
TinyML and Efficient Deep Learning Computing - Lecture 24: Course Summary
Explore efficient machine learning techniques for deploying neural networks on resource-constrained devices. Gain hands-on experience with mobile AI and quantum machine learning.
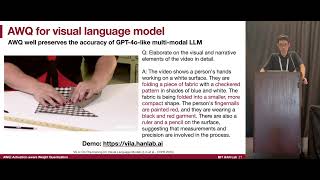
AWQ: Activation-aware Weight Quantization for LLM Compression and Acceleration
Explore activation-aware weight quantization for compressing and accelerating large language models. Learn about AWQ's innovative approach to LLM optimization.
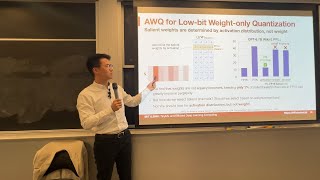
AWQ for LLM Quantization - Efficient Inference Framework for Large Language Models
Explore Activation-aware Weight Quantization (AWQ) for efficient large language model deployment, reducing memory requirements while preserving performance across domains and modalities.
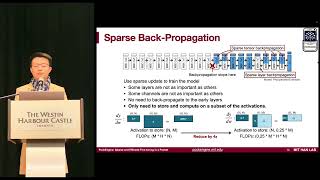
PockEngine: Sparse and Efficient Fine-tuning in a Pocket
Explore sparse and efficient fine-tuning techniques for AI models with PockEngine, enhancing performance while reducing computational demands.