Beyond Experimental - Spark on Kubernetes
Insights on leveraging open-source tech for Apache Spark on Kubernetes, addressing challenges in large-scale production environments and evolving ML data infrastructure in the cloud.
Extending Argo Projects: Customizing Argo CD and Argo Rollouts
Learn to customize Argo CD and Argo Rollouts for specific company needs while maintaining flexibility. Explore extension mechanisms and gain architectural insights for effective deployment workflows.
The Life of an Argo Workflows Salesperson - Implementing Shared Workflows in Kubernetes
Discover strategies for implementing Argo Workflows across diverse engineering teams, overcoming adoption challenges, and customizing the platform for performance without sacrificing flexibility.
Streamlining Big Data Workflows with Memoization and Work Avoidance
Optimize big data and ML workflows using memoization and work avoidance techniques in Argo Workflows. Learn best practices to reduce runtime and compute costs for data processing and machine learning jobs.
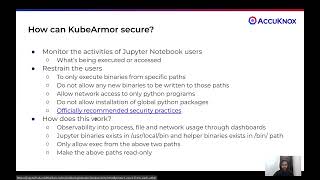
Securing Jupyter Notebooks with KubeArmor
Learn to enhance security for Jupyter Notebooks using KubeArmor, exploring advanced protection techniques for cloud-native environments and data science workflows.
Dynamic Large Scale Spark on Kubernetes: Empowering the Community with Argo Workflows and Argo Events
Discover best practices for building scalable Spark clusters on Kubernetes using Argo Workflows and Argo Events, enabling efficient resource utilization and seamless scalability for powerful data processing.
Controlling Access to External APIs with Cilium
Step-by-step guide on configuring Cilium to limit GitHub repo access for cluster workloads, covering TLS termination, certificate management, and L7 network policies for enhanced security in multi-tenant environments.
Scheduling Jupyter Notebooks Using Airflow on Kubernetes
Learn to schedule Jupyter notebooks using Airflow on Kubernetes, enabling scalable data pipelines and machine learning workflows with enhanced security and resource management.
Rook: Introduction and Deep Dive with Ceph Storage - Lecture 1
Explore Rook, a cloud-native storage operator for Kubernetes, and its integration with Ceph for stable block, file system, and object storage in production environments.
Let's Play with Charmed Spark - Apache Spark on Kubernetes
Explore Apache Spark on Kubernetes using Charmed Spark. Learn to deploy, configure, and run Spark workloads, integrate with Kafka, and monitor jobs through hands-on demonstrations.
Faster, Safer, Serverless - Empowering Apache Spark Standalone Cluster on Kubernetes
Explore a K8s-native Serverless Spark Service that enhances speed and simplicity, featuring a new K8s operator for cluster creation and job submission, with rapid responsiveness and ML training integration.
Product Market Misfit: Adventures in User Empathy
Explore user empathy in product development through a case study of Istio's Ambient mode, learning strategies for gathering honest feedback and understanding user perspectives.
From Bash Scripts to Kubeflow and GitOps - Operationalizing ML at Scale
Explore the journey of operationalizing data science workloads at scale using Kubeflow and GitOps, from initial challenges to a standardized approach for ML experiments, API creation, and batch predictions delivery.
The Good, the Bad, and the Missing Parts of Kubeflow
Explore Kubeflow's strengths, weaknesses, and future developments as an MLOps platform based on user feedback and upcoming release plans.
Super Reliable Cloud Native Data Processing Using Apache Spark and Cloud Shuffle Manager
Enhance Apache Spark's reliability on Kubernetes with Cloud Shuffle Manager, enabling fault tolerance and cost savings through Spot Instances while maintaining performance for large-scale data processing.
The Data Pipelines Behind Forest Carbon Credits - Why Pachama Uses Flyte to Orchestrate Workflows
Explore how Pachama uses Flyte to manage complex data and ML pipelines for transparent forest carbon credit computation, including workload management, configuration, and lessons learned.
Rook - Introduction and Deep Dive with Ceph Storage
Explore Rook, a cloud-native storage operator for Kubernetes, and its integration with Ceph. Learn about block, file system, and object storage solutions for production environments.
Empowering Developers with Easy, Scalable Stream Processing on Kubernetes
Explore scalable stream processing on Kubernetes with Numaflow, an open-source framework enabling easy, cost-efficient data analytics for various engineering roles, powering large-scale operations at Intuit.
Document Your Career Path with Kubernetes SIG Docs
Learn how contributing to Kubernetes documentation can shape your career in open source. Discover impactful ways to contribute, hear from industry experts, and explore opportunities for growth in the cloud native ecosystem.
Production-Ready AI Platform on Kubernetes
Explore best practices for building scalable AI/ML platforms using cloud-native technologies like Kubernetes, Kubeflow, and KServe. Learn to tackle challenges in MLOps and large model inference systems.
Transforming Data Science at PepsiCo - The Kubeflow Revolution
Explore PepsiCo's data science transformation using Kubeflow, addressing challenges in model reproducibility and enhancing efficiency, collaboration, and scalability in machine learning workflows.