Rook: Introduction and Deep Dive with Ceph Storage - Kubernetes Cloud-Native Storage
Explore Rook, a cloud-native storage operator for Kubernetes, and its integration with Ceph for robust block, file system, and object storage in production environments.
Spark on Kubernetes: Building an Elastic Service - Apple's Approach
Explore Apache Spark on Kubernetes, focusing on autoscaling challenges and solutions for efficient large-scale data processing in multi-tenant environments with advanced features.
Building Digital Twins for DFDS With Crossplane and Kubernetes
Explore how DFDS uses Kubernetes-based Digital Twins, Crossplane, and Backstage to manage logistics operations and accelerate software development in a decentralized, distributed environment.
Tower of Babel - Making Apache Spark, Kubeflow, and Kubernetes Play Nice
Explore how Apache Spark, Kubeflow, and Kubernetes can work together to process big data matrices, denoise medical images, and create reproducible ML pipelines for COVID research and healthcare applications.
Autoscaling Elasticsearch for Logs on Kubernetes
Explore best practices for autoscaling Elasticsearch on Kubernetes, focusing on efficient load balancing and introducing a new open-source operator for optimal performance.
Jet Energy Corrections with GNN Regression using Kubeflow at CERN
Explore how Kubeflow enables graph neural network-based jet energy corrections at CERN's Large Hadron Collider, improving particle physics research through scalable machine learning workflows.
From Student to SRE - Navigating CNCF Projects and Kubernetes
Discover how a student transformed into a Site Reliability Engineer, mastering CNCF projects like Kubernetes and Linkerd through internship, community engagement, and continuous learning.
Build a Cloud Native Logging Pipeline on the Edge with Fluentbit Operator
Explore FluentBit Operator for efficient cloud-native logging on edge devices. Learn its architecture, design, and implementation on K3s for processing logs in edge and IoT scenarios.
The Future of Reproducible Research - Powered by Kubeflow
Explore the future of reproducible research using Kubeflow, an open-source platform that streamlines data science workflows and enhances scientific collaboration through easily shareable and replicable pipelines.
DevOps in Data Science - What Works and What Doesn't
Explore challenges and solutions in implementing DevOps for data science projects, focusing on balancing ML engineers' needs with data scientists' desire for simplicity using Kubeflow and other tools.
Unlimited Data Science Libraries in One Container Image - Dynamic Environment Modules for Kubernetes
Explore how to leverage environment modules in Kubernetes for data science, enabling dynamic access to thousands of libraries and packages while solving container management challenges.
Sharing Knowledge: Writing Good Docs for Quick Approval
Learn best practices for creating inclusive, accessible, high-quality documentation in pull requests. Discover how to structure content, write clearly, and avoid common pitfalls for quick approval.
Building a Data Science Platform with Argo Workflows
Discover how Bloomberg and Pipekit leverage Argo Workflows and Kubernetes to create scalable data science platforms, enabling data teams to automate pipelines and self-serve their data engineering needs across multiple clusters.
Machine Learning at Scale Using KubeFlow on AWS
Explore scalable machine learning architecture using Kubeflow on AWS, featuring hands-on demos of distributed storage and Kubernetes-based ML toolkit implementation.
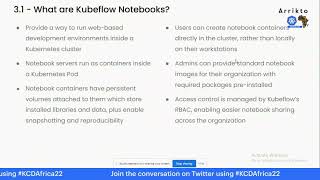
Transforming Jupyter Notebooks to Reproducible Machine Learning Pipelines with Kale
Learn to convert Jupyter notebooks into scalable Kubeflow pipelines using Kale, enabling seamless deployment of ML workflows on Kubernetes for improved reproducibility and efficiency.
The Course of True Community Management Never Did Run Smooth - A One-Act Play
Exploring community management in open source through storytelling, comparing KubeCon practices with other communities, and highlighting inclusivity, kindness, and accessibility in ecosystem evolution.
Fluent Bit - Logging for Kubernetes
Explore Fluent Bit v1.5's new features for Kubernetes logging, including performance enhancements and integrations with major cloud services. Learn from industry experts about this CNCF sub-project's latest advancements.
Kubernetes Cost Allocation Done Right
Explore Kubernetes cost allocation strategies, including visibility across workloads, showback/chargeback programs, and empowering users with actionable cost information.
How to Survive High Demanding Services - Managing AI with Kubernetes and Istio
Explore strategies for managing high-demand AI services, including design for seamless changes, real-time monitoring, and auto-recovery using Kubernetes and Istio service mesh.
Human-Friendly, Production-Ready Data Science Stack With Metaflow and Kubernetes
Explore a modern ML infrastructure stack using Metaflow and Kubernetes to boost data science productivity. Learn from Netflix's experience in building end-to-end machine learning workflows.
Rook: Introduction and Deep Dive with Ceph Storage
Explore Rook, a cloud-native storage operator for Kubernetes, and its integration with Ceph for stable block, file system, and object storage in production environments.