Groq Tutorial - Part 5
Explore Groq's innovative AI hardware and software solutions for accelerating machine learning workloads and enhancing computational efficiency.
Efficient AI: From Supercomputers to Smartphones
Explore techniques for efficient AI training and inference, from data ingestion to model compression, enabling powerful models on supercomputers and smartphones.
Big Math Libraries in Interactive Theorem Provers
Explore five key aspects of Big Math in Interactive Theorem Provers: inference, computation, concretization, narration, and organization. Learn about library sizes, searching, integration, and maintenance.

Informer: Training and Inference
Explore time series prediction using Informer, a transformer-based model. Learn to train and make predictions through hands-on coding, enhancing your skills in advanced forecasting techniques.

The Best Tiny Language Models - Performance, Fine-tuning, and Function-calling
Explore the benefits, performance, and fine-tuning of small language models. Learn about function-calling with quantized models and discover the best tiny LLMs for various applications.
Fine-tuning Language Models for Structured Responses with QLoRa - Lecture
Master fine-tuning language models for structured responses using QLoRa. Learn quantization, data setup, training, inference, and advanced techniques to enhance model performance and efficiency.
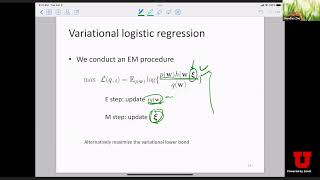
Probabilistic Machine Learning - Lecture 19
Dive into advanced data science concepts through comprehensive lecture coverage of key theoretical and practical aspects in this graduate-level academic session.
Probabilistic Machine Learning - Lecture 27
Dive into advanced data science concepts through comprehensive lecture coverage of key theoretical and practical aspects in modern data analysis and machine learning.
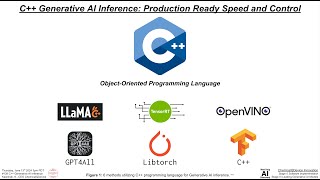
C++ Generative AI Inference - Production Ready Speed and Control
Optimize C++ for generative AI inference, enhancing speed and control. Explore techniques to boost performance and gain precise command over AI model execution in production environments.
Equilibrium is Inference - Lessons from Liquid-Liquid Phase Separation Models
Delve into the relationship between equilibrium systems and information processing, exploring neural computation models and their applications in molecular systems and phase separation dynamics.
Building an Auto-scaling AI Inference Service - From Setup to Deployment
Master the fundamentals of building and scaling AI inference services, from GPU utilization to auto-scaling implementation, Docker configuration, and API endpoint setup for optimal performance.

What Can Storage Do for AI? - Optimizing NVMe Storage for Large Language Models
Explore how NVMe flash storage enables AI model deployment at scale, from data center training to edge device inference, with focus on optimization techniques and performance improvements.