Really Long Context LLMs - 200k Input Tokens
Explore Yi 34B 200k model capabilities, compare long context models, and learn about passkey retrieval and inferencing on Runpod. Access resources for implementing extended context LLMs.
Deploying Serverless Inference Endpoints - Setup and Cost Comparison
Deploy serverless inference endpoints efficiently. Learn setup, use cases, and cost comparisons for API-based machine learning model deployment.
Learning with Volterra Series - Convolutional Networks without Activation Functions
Explore Volterra Series in machine learning, reducing sample and model complexity while maintaining high performance in inference problems.
NeuPSL: Training and Inference - Part 2
Explore NeuPSL's training and inference processes, combining probabilistic soft logic with deep learning for end-to-end training and logical constraint enforcement in neurosymbolic AI.
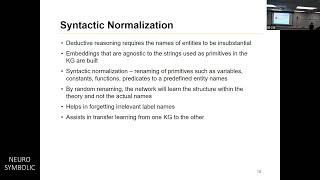
Deductive Reasoning for Cross-Knowledge Graph Entailment - Part 1
Explore deductive reasoning for cross-knowledge graph entailment, covering inference types, embedding methods, memory networks, and model architecture for AI and machine learning applications.
Inference in Propositional Logic: From Basics to Lattice Theory Applications
Explore propositional logic inference, including lattice theory and fixpoint operators for entailment queries. Gain insights into logic programming and knowledge reasoning fundamentals.
Developing Local AI Copilots with LangChain, NVIDIA NIM, and FAISS - LLM App Development
Learn to build a local AI copilot using LangChain, NVIDIA NIM, and FAISS. Covers document processing, vector storage, inference with Llama 3, and LangChain orchestration for responsive LLM applications.
Effortless Scalability: Orchestrating Large Language Model Inference with Kubernetes
Explore automated deployment of large language models on Kubernetes, leveraging CRDs for seamless management and optimizing GPU utilization through preset configurations and auto-provisioning.

Creating Your Own Flux AI Model with LoRA Fine-Tuning
Learn to create and fine-tune a custom Flux AI model using LoRA, including dataset preparation, cost-effective training on Replicate, and generating AI images with your personalized model.

How Does Netflix Recommend Movies? Matrix Factorization
Explore matrix factorization in recommender systems, focusing on Netflix's movie recommendation algorithm. Learn about dependencies, error functions, and predicting user ratings.
Advanced Productivity for Data Science with Vertex AI
Explore Vertex AI's features to enhance data science productivity, including Workbench, AI Studio, and Colab Enterprise.
Extending PyTorch for Custom Compiler Targets - Accelerator Hardware Integration
Discover how to annotate PyTorch code with custom metadata for optimizing model inference on specialized hardware accelerators, focusing on LPU deployment and performance enhancement.
The Power of Knowledge Graphs and AI - A New Era for Developers and Data Scientists
Explore Knowledge Graphs and AI: Learn technical aspects, real-world applications, and future trends. Discover how to leverage these technologies for data harmonization and inference.
Train Your First NLP Transformer Model with Amazon SageMaker
Learn to train and deploy NLP Transformer models using Amazon SageMaker and Hugging Face. Gain hands-on experience with cutting-edge deep learning techniques for natural language processing.
Accelerate AI Inference Workloads with Google Cloud TPUs and GPUs
Optimize AI inference using Google Cloud's TPUs and GPUs. Compare accelerators for various workloads, deploy efficiently, and implement cost-effective strategies for high-performance model deployment.
Bringing Machine Learning to Streaming Data - Dataflow ML Innovations
Deploy and manage ML pipelines for streaming data, including inference, image classification, and custom model handling. Learn from Spotify's experience in large-scale ML podcast preview generation.
Real-Time Machine Learning: Features and Inference - MLOps Podcast #135
Explore real-time ML features and inference with LinkedIn experts. Gain insights on implementation, challenges, and best practices for moving from batch to interactive near real-time machine learning.

Building LLM Applications for Production
Explore key challenges in deploying LLMs to production, covering essential considerations for real-world application development and implementation.
MLOps: Inference ONNX Model in Azure ML Managed Endpoint AKS
Deploy ONNX models to Azure ML Managed Endpoints (AKS) for efficient inference. Learn step-by-step process using Python SDK v2 to optimize machine learning operations.
CPU Inference with ViT ONNX Model in Azure ML Managed Endpoint - AKS
Deploy a Vision Transformer model for CPU inference on Azure Kubernetes Service using ONNX format and Azure ML SDK v2. Learn to create managed endpoints in Azure ML Studio.
MLOPS: Inference ViVIT ONNX Model in Azure ML Managed Endpoint (AKS)
Aprenda a implementar un modelo ViViT en ONNX para inferencia en CPU utilizando Azure Kubernetes Services y onnxruntime con Python SDK v2.