Hardware, Software, Performance and Costs for Llama-2 70b and Mixtral 8x7b LLM Inference with Low Concurrency
Explore hardware, software, performance, and costs for running Llama-2 70b and Mixtral 8x7b LLM inference. Compare on-premises and cloud options, with insights on speed, cost, and setup for small organizations.
Hugging Face Accelerate: Making Device-Agnostic ML Training and Inference Easy at Scale
Learn to simplify ML model training and inference across devices using Hugging Face Accelerate. Explore its low-level interface, hardware compatibility, and scalable deployment features.
Serving LLMs with MLflow - Phi-3-mini-4k-instruct Model
Aprende a crear, guardar y cargar modelos LLM con MLflow, utilizando Phi-3-mini-4k-instruct para inferencia local en tu computadora.
MLOps with MLflow: Fine-Tuning LLMs - Tracking Experiments and Logging Models
Fine-tune LLMs, track experiments, and log models using MLflow for efficient MLOps practices in data science and machine learning projects.
MLOps: C# Image Recognition with ResNet50v2 Model
Implement image recognition using ResNet50v2 in C# with ONNX and SixLabors.ImageSharp for efficient MLOps workflows.
Converting BERT to ONNX and Inference with BERTTokenizer for C# - Machine Learning and Data Science
Convert Bert model to ONNX format and create a C# app using BERTTokenizer for inference with ONNX transformer models.
LLMOps: Comparison of OpenVino, ONNX, TensorRT, and PyTorch Inference
Explore model conversion to ONNX, OpenVino, and Tensor-RT formats for optimized CPU and GPU inference, comparing performance against native PyTorch.
LLMOPs - Inference in CPU with Phi3 4k Instruct ONNX 4-bit Model Using C#
Explore CPU-based inference using 4-bit quantized Phi 3 4K Instruct in ONNX format with C#. Learn practical implementation for efficient machine learning deployment.
Effortless Scalability: Orchestrating Large Language Model Inference with Kubernetes
Automate deployment of large language models on Kubernetes. Leverage CRDs, streamline with HTTP servers, eliminate manual tuning, auto-provision GPU nodes, and empower users with containerized model deployment.
Aiding Static Analysis - Discovering Vulnerabilities in Binary Targets through Knowledge Graph
Explore advanced techniques for vulnerability detection in binary targets using knowledge graphs, static analysis, and specialized tools like Binary Ninja and Kraken.
Running Programs in Reverse for Deeper A.I.
Explore inverse simulation for AI advancement, covering mental simulation, animation, and a novel approach using ReverseFlow to compile programs into their inverses, enhancing vision and planning capabilities.
Abductive Inferences and Expectations - Lecture 1.2
Explore abductive inferences and expectations in artificial intelligence, focusing on knowledge representation and reasoning techniques.
How SSDs Enhance Vector Data Scaling in GenAI RAG Systems
Explore how SSD technology optimizes RAG architectures and vector databases for large-scale LLM deployments, improving inference accuracy and performance in Generative AI systems.
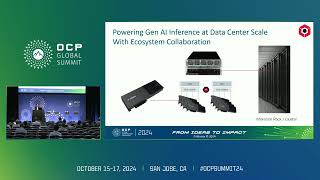
Leveraging ODSA's BoW Die-to-Die Link Technology for Generative AI Inference Transformation
Discover how d-Matrix's Corsair accelerator revolutionizes Generative AI inference through innovative chiplet architecture, digital-in-memory computing, and ODSA BoW die-to-die interconnect technology.
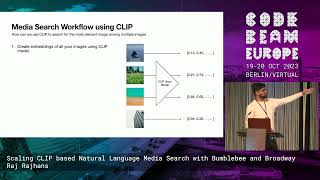
Scaling CLIP-Based Natural Language Media Search with Bumblebee and Broadway
Harness Elixir's power for machine learning with Bumblebee and Broadway. Learn to implement scalable natural language media search using CLIP, showcasing Elixir's capabilities in ML applications.
Local LLM Fine-tuning on Mac (M1 16GB) Using QLoRA and MLX
Fine-tune a local LLM on M1 Mac using MLX and QLoRA. Adapt Mistral 7b to respond like you to YouTube comments, with step-by-step guidance and code examples.
Entailment and Proof in Artificial Intelligence - Lecture 2.5
Explore entailment and proof concepts in artificial intelligence, focusing on knowledge representation and reasoning techniques.
Considerations and Optimizations for Deploying Open Source LLMs at Your Company
Explore best practices for secure, reliable, and scalable open-source LLM deployments in enterprise settings.
MLOps: Logging and Loading Microsoft Phi3 Mini 128k in GGUF with MLflow
Learn to log and load quantized LLama.cpp models in MLflow, create Python classes, and perform inference using Microsoft Phi3 mini 128k in GGUF format.
Microsoft AI: Visual Studio Code AI Toolkit Introduction for Data Science and Machine Learning
Explore Visual Studio Code AI Toolkit with hands-on examples in Python and C#, focusing on CPU inference using the Phi 3 4K Instruct model in ONNX format.
LLMs: Understanding Temperature and Context Length of GPT Models
Explore temperature and context length in GPT models to enhance LLM research. Learn how these parameters impact results and gain insights for more effective AI interactions.