Hugging Face and Ray AIR Integration for Scalable Machine Learning
Explore Hugging Face and Ray AIR integration for scalable model training and data loading. Learn to create end-to-end workflows from data ingest to inference and serving.
Enabling End-to-End LLMOps on Michelangelo with Ray
Explore Uber's extension of Michelangelo for end-to-end LLMOps, leveraging Ray for scalable development with hundreds of A100 GPUs and integrating open-source techniques for efficient custom LLM creation.

Quantum Computing with the NVIDIA Platform
Explore quantum computing advancements using NVIDIA's platform, featuring insights from industry experts on cutting-edge developments and practical applications.
FastIce.jl: A Massively Parallel Ice Flow Model Running on GPUs
Explore FastIce.jl, a Julia-based ice flow model for GPUs. Learn about its modular architecture, performance on supercomputers, and applications in efficient large-scale ice sheet modeling.
Scalable and Flexible Distributed Reinforcement Learning Systems
Explore scalable distributed reinforcement learning systems, focusing on flexible training loops, statement management, and GPU allocation. Gain insights into building efficient RLHF systems for large-scale applications.
The Role of Machine Learning in Facilitating Fusion Energy Research
Explore machine learning applications in fusion energy research, including turbulence simulation speed-ups and predicting rare events. Gain insights into ML's potential to accelerate progress towards clean, abundant fusion energy.
Automating Distributed Heterogeneous Computing for Domain Experts
Explore new approaches for enabling domain experts to program future HPC systems efficiently, focusing on compiler and runtime techniques for distributed heterogeneous computing.
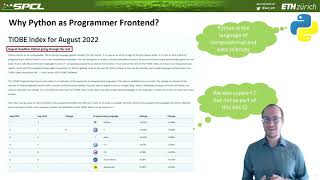
Portable High-Performance Python on CPUs, GPUs, and FPGAs
Optimize Python for high performance on CPUs, GPUs, and FPGAs. Learn HPC-oriented extensions, automatic optimizations, and portable performance techniques across architectures.
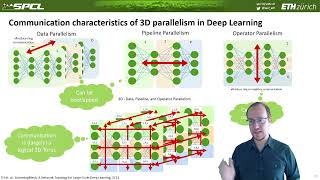
Post-Moore Spatial Computing: From Chips to Clusters
Explore spatial computing strategies for post-Moore's Law era, addressing challenges in scaling compute power from chips to clusters for AI and high-performance computing.
Heterogeneous Serverless Computing for High-Performance Computing and AI Workloads
Explore heterogeneous serverless computing for efficient HPC, HPDA, and AI workloads. Learn about innovative accelerator uses and flexible deployment models from edge to exascale.
Productive Performance Engineering for Weather and Climate Modeling with Python
Optimize weather and climate models using Python-embedded DSL and data-centric techniques. Improve productivity and performance through abstraction, semi-automated workflows, and transfer tuning for efficient scaling on supercomputers.
Efficient AI: From Supercomputers to Smartphones
Explore techniques for efficient AI training and inference, from data ingestion to model compression, enabling powerful models on supercomputers and smartphones.
HPC and AI/ML: A Synergistic Relationship
Explore synergies between HPC and AI/ML, focusing on scalable algorithms, efficient resource use, and data-driven models for performance optimization in large-scale computing environments.
Deinsum: Practically I/O Optimal Multi-Linear Algebra for Distributed Systems
Optimize distributed multilinear algebra computations with Deinsum framework. Automate data movement-optimal tiling and scheduling for enhanced performance in high-dimensional tensor operations.
The Role of MPI in Modern AI - Rusty Lusk's Legacy
Explore MPI's crucial role in modern AI and its impact on parallel computing, honoring Rusty Lusk's contributions to the field.
From Two Strong Oxen to Billions of Fleas - The Evolution of Massively Parallel Distributed Supercomputers
Explore massively parallel distributed supercomputers, focusing on distributed-memory parallelism and RDMA through MPI. Gain insights into current designs and future challenges in high-performance computing.
HammingMesh: A Network Topology for Large-Scale Deep Learning
Explore a novel network topology for large-scale deep learning systems, enhancing data movement efficiency and job scheduling flexibility for future AI training infrastructure.
AI-Driven Performance Metaprogramming - Embedding Spaces for Program Analysis and Optimization
Explore AI-driven performance metaprogramming using embedding spaces for programs. Learn to assess, analyze, and improve program performance through advanced AI methods.
ARCHER2 Training Service: A Three-Year Retrospective and Future Outlook
Explore ARCHER2's comprehensive HPC training program, covering diverse disciplines and user needs. Learn about course design, delivery methods, and tailored training pathways.
Magic Castle - Terraforming the Cloud to Teach High-Performance Computing
Replicate HPC infrastructure experience using cloud resources with Magic Castle. Deploy complete clusters with schedulers, data-transfer nodes, and pre-compiled software in minutes.
HPC Carpentry: Bridging the Gap in High-Performance Computing Education
Learn essential skills for using high-performance computing resources effectively, bridging the gap for novice users and researchers in domains with newly available HPC access.