ARM64 SVE Concepts and Integration into DPDK
Explore Arm64's Scalable Vector Extension (SVE) concepts and learn how to integrate this powerful SIMD feature into DPDK libraries for enhanced performance and hardware adaptability.
Zippier ZMap - Internet-Wide Scanning at 10 Gbps
Optimizations to ZMap network scanner achieving 10-fold increase in scan rate, enabling comprehensive TCP port scanning across IPv4 address space in 4.5 minutes. Discusses implications and potential applications.
Cost-Effective GPU Solutions for AI Workloads with OpenStack - Optimization Strategies
Discover how to optimize AI workload costs using affordable GPUs and desktop workstations for cloud instances, with practical insights from ArcFusion AI and NIPA Cloud's successful implementation.
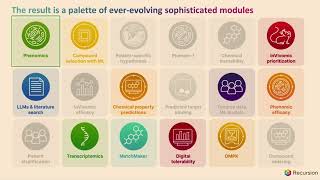
Industrializing Machine Learning Workflows in Drug Discovery
Discover how machine learning workflows accelerate drug discovery through automated predictive modeling, data management, and cloud computing for evaluating compound properties and safety.
Processing 100+ GB of Data in Seconds Using Polars GPU Engine
Master high-speed data processing with Polars GPU engine, leveraging NVIDIA GPUs to handle massive datasets up to 10x faster while using familiar Polars syntax and commands.
Stable Diffusion 3.5 Medium - A Review of the New Text-to-Image AI Model
Explore Stable Diffusion 3.5 Medium's capabilities, comparing its performance against SDXL and other models while learning about its advantages for users with lower-end GPUs.
Mesh Shaders on NVIDIA Hardware - Implementation and Future Development in NVK
Dive into the technical implementation of mesh shaders on NVIDIA hardware and explore upcoming NVK developments for enhanced shader support.
Perfect PC for AI, Object Detection and LLMs - Complete Guide
Learn how to build the optimal PC setup for AI development, focusing on computer vision, object detection, and large language model implementation.
Getting GPUDirect to Work with Broadcom NICs
Discover how to integrate Broadcom NICs with NVIDIA GPUs for enhanced packet processing using GPUDirect RDMA, exploring necessary DPDK ecosystem modifications and implementation steps.
Combining Rust and DPDK: Security, Stability, and Performance Optimization
Explore how Rust APIs can enhance DPDK functionality through improved security, user experience, and performance optimization while processing network packets efficiently.

1.2 Tb/s Packet Processing of Radio Telescope Data on GPU
Discover how to process massive radio telescope data streams at 1.2 Tb/s using NVIDIA Grace Hopper GPUs, optimizing packet handling and reducing energy consumption through innovative system architecture.
Enabling Cloud Workloads with the WEKA Data Platform
Discover how the WEKA Data Platform transforms data silos into dynamic pipelines, optimizing GPU performance and streamlining AI, ML, and HPC workloads in modern cloud environments.
Optimizing Storage Solutions for AI and ML Workloads in Google Cloud
Discover advanced storage solutions optimized for AI/ML workloads, featuring Anywhere Cache, HyperDisk ML, and Cloud Storage FUSE innovations that enhance data accessibility and training efficiency.
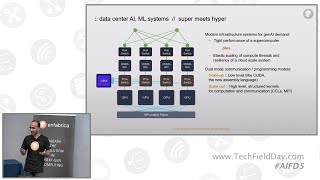
Accelerated Computing for AI Systems - A Network Architecture Perspective
Discover groundbreaking networking technology for AI computing with Enfabrica's ACFS system, offering 8Tb/s bandwidth and innovative solutions for modern data center challenges in distributed AI workloads.
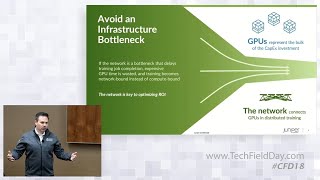
Automating AI Cluster Design with Juniper Apstra
Discover how to automate AI cluster designs using Terraform with Apstra, including GPU compute fabrics, storage fabrics, and NVIDIA-optimized rack configurations for efficient model training.
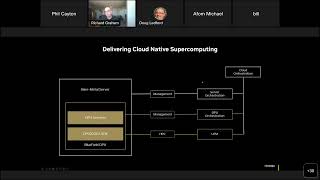
Accelerating Scientific Computing Workloads with InfiniBand DPUs
Discover how InfiniBand DPUs and In-Network Computing accelerate complex scientific workloads, boost performance, and enable faster research insights through advanced networking capabilities.
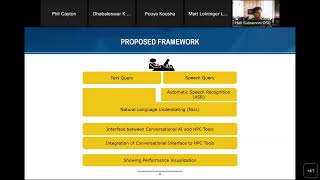
Conversational AI-Enabled User Interface for HPC Tools
Discover how AI-powered conversational interfaces can simplify complex HPC tools, making performance analysis more accessible through natural language commands and improving productivity for both novice and expert users.
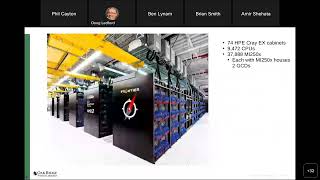
Open MPI and Libfabric Integration for the Frontier Supercomputer
Delve into high-performance computing optimization through Open MPI and libfabric implementation on Frontier supercomputer, focusing on AMD MI250X architecture and HPE Slingshot NICs integration.
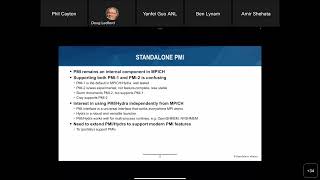
OpenFabrics Interfaces Support and GPU Integration in MPICH
Discover the latest updates on OFI integration in MPICH, focusing on GPU support implementation, network API enhancements, and Libfabric development for high-performance computing systems.
Status of OpenFabrics Interfaces (OFI) Support in MPICH
Discover the latest developments in OpenFabrics Interfaces (OFI) support within MPICH, exploring implementation status and advancements in high-performance computing infrastructure.
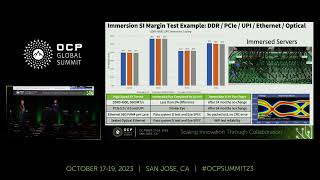
Signal Integrity in Immersion - Overcoming Challenges for High-Performance IT Platforms
Explore signal integrity challenges in immersion cooling systems, examining testing methods and design strategies for optimizing high-performance IT platform performance and data transmission.