Monitoring 400G Traffic in DPDK Using FPGA-Based SmartNIC with RTE Flow
Discover how to monitor 400G network traffic using FPGA-based SmartNIC and DPDK, featuring hardware acceleration techniques and RTE flow configuration for optimal packet processing performance.
Understanding AI PCs: Hardware, Software, and Future Implications
Explore the evolution of AI-enabled personal computing, from hardware components to software integration, and understand the potential impact on business and consumer markets.
Accelerating Scientific Computing Workloads with InfiniBand DPUs
Discover how InfiniBand DPUs and In-Network Computing accelerate complex scientific workloads, boost performance, and enable faster research insights through advanced networking capabilities.
Modular Chiplet Opportunities for High-Performance Computing
Explore how chiplet-based specialized accelerators can revolutionize High-Performance Computing (HPC) systems to overcome Moore's Law limitations and deliver enhanced scientific computing performance.
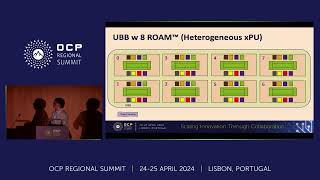
Chiplet-based Reconfigurable Open Compute Accelerator Module Architecture and Platform
Explore the innovative Chiplet-based Reconfigurable OAM platform, focusing on system packaging, standardization, and modular design for advanced accelerator solutions and microservices deployment.
Navigating the AI ASIC Frontier: Trends, Challenges, and Technological Breakthroughs
Explore cutting-edge AI hardware developments and silicon solutions, focusing on data center innovations, technological constraints, and future advancements in AI training infrastructure.
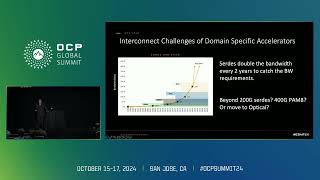
Expanding Horizons: Unleashing the Next Wave of Generative AI Computing
Discover how MediaTek's innovative semiconductor solutions power the next generation of AI computing through advanced chiplet architecture and high-speed SerDes technology for enhanced performance.
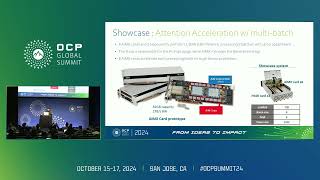
LLM Service Revolution Through Memory Computing Fusion Technology - From Datacenter to On-Device AI
Discover how SK Hynix's AiM technology revolutionizes LLM services through processing-in-memory solutions, offering enhanced efficiency and reduced costs for both datacenter and device-level AI applications.
OCP Hyperscale-Compliant AI Storage Servers with Compression and Deduplication Accelerators
Explore cutting-edge hyperscale AI storage solutions featuring advanced compression and deduplication technologies for optimized data management in enterprise environments.
Overcoming the GPU Memory Capacity Limitation with Two-Digit Nanosecond Latency CXL Controller
Explore advanced solutions for GPU memory limitations through CXL controller technology, focusing on nanosecond-level latency optimization and enhanced capacity management.
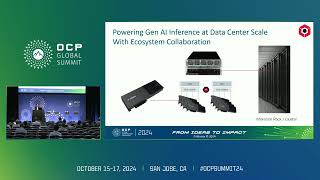
Leveraging ODSA's BoW Die-to-Die Link Technology for Generative AI Inference Transformation
Discover how d-Matrix's Corsair accelerator revolutionizes Generative AI inference through innovative chiplet architecture, digital-in-memory computing, and ODSA BoW die-to-die interconnect technology.
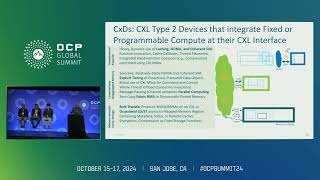
Programming Near Data Processing - Best Practices and Industry Standards
Explore best practices for optimizing Computational Memory performance through near-data processing, backed by extensive industry collaboration and standardization efforts.
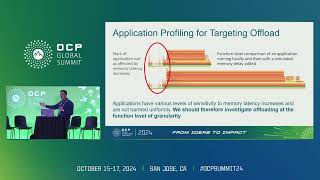
Near Memory Compute for AI Inferencing - Optimizing Data Center Design and TCO
Explore innovative approaches to AI inferencing optimization through Near-Memory Compute technology, focusing on reduced latency, cost efficiency, and sustainable data center design solutions.
SK Hynix PIM (AiM) 기반 생성형 AI 모델 가속기 플랫폼
Discover SK하이닉스's innovative AiM-based accelerator platform, designed to overcome limitations in generative AI models like GPT through Processing-in-Memory technology, offering enhanced performance and energy efficiency.
Squash - 딥러닝 서비스 추론 속도 개선기
Discover how Squash technology optimizes deep learning inference speed and reduces hardware costs through innovative model compression techniques for efficient AI service deployment.
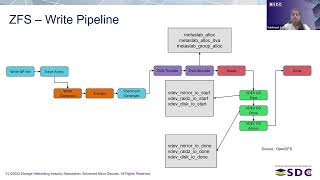
File System Acceleration Using Computational Storage for Efficient Data Storage
Explore file system acceleration techniques using computational storage, focusing on SmartSSD implementation for efficient compression and improved system performance through hardware offloading.
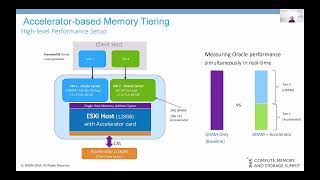
CXL Accelerator-Based Memory Solutions - Bringing Unique Customer Value
Explore how VMware and Samsung leverage CXL Type-2 accelerator solutions to enhance memory capabilities, reduce costs, and improve workload performance through innovative hardware-software integration.
Machine Learning on the Edge - From Microcontrollers to Embedded Linux Devices
Explore ML deployment on edge devices, from microcontrollers to embedded Linux systems. Learn about hardware options, model adaptation, and deployment strategies for real-world applications.
Nested Virtualization Overview - Understanding Concepts and Use Cases
Explore nested virtualization: its concept, applications, and limitations. Gain insights into this advanced virtualization technique and understand when to leverage or avoid it.
QEMU: Recent Developments and Upstream Contributions
Explore recent advancements in QEMU, including major upstream contributions and their impact on virtualization technology.
Powering Gaming Excellence - Introduction to Arm GPUs for Mobile Game Developers
Explore Arm GPUs for mobile game development, enhancing performance and efficiency. Learn key features and optimization techniques to create cutting-edge mobile games.