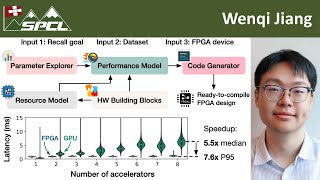
Co-design Hardware and Algorithm for Vector Search
Explore hardware-algorithm co-design for efficient vector search on FPGAs, enhancing performance in large-scale information retrieval and machine learning systems.

Cloud AI 100 High Performance Cloud-Edge Inferencing
Explore Qualcomm's Cloud AI 100 accelerator for high-performance cloud-edge inferencing, featuring leadership-class performance, power efficiency, and comprehensive software tools for production deployment.
Julia Community Reshapes Computation in Geosciences
Explore Julia's impact on geosciences: ecosystem tools, hardware acceleration, and collaborative initiatives revolutionizing Earth observation and software development in the field.
How to Make Your Electrons Do More in Java - Vector API and TornadoVM
Explore Vector API in Java and TornadoVM for GPU/FPGA computing. Enhance processing power and performance through advanced JVM techniques and native-code tooling.
Extending PyTorch for Custom Compiler Targets - Accelerator Hardware Integration
Discover how to annotate PyTorch code with custom metadata for optimizing model inference on specialized hardware accelerators, focusing on LPU deployment and performance enhancement.
ZXDH DPU Adapter and Its Application in Hardware Acceleration and Networking
Discover ZTE's ASIC-based enhanced data processor with programmable packet processing, hardware offloading, and extensive driver interfaces for virtualization, AI computing, and security applications.
Introducing UACCE Bus in DPDK - Unified Accelerator Framework Integration
Discover how UACCE bus enables seamless integration of accelerator devices in DPDK, exploring Shared Virtual Addressing implementation and its potential to enhance application performance.
Coupling Eventdev Usage with Traffic Metering and Policing for QoS
Discover how to integrate hardware RX scheduling with metering and policing modules using DPDK's eventdev framework for efficient packet processing and QoS implementation.
Lessons Learnt from Reusing QDMA NIC to Base Band PMD
Discover key insights and practical lessons from converting AMD Xilinx FPGA NIC PMD to BBDEV PMD, exploring technical challenges and implementation strategies for efficient hardware adaptation.
Revolutionizing Big Data Analytics with NeuroBlade's SQL Processing Unit (SPU)
Discover how NeuroBlade's SQL Processing Unit revolutionizes data analytics by accelerating SQL queries up to 30x faster, offering cost-effective solutions for enterprise-scale data processing and insights.
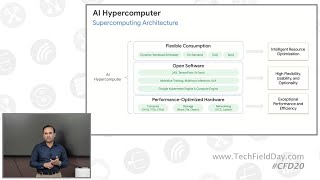
AI Workloads and Hardware Accelerators - Introducing the Google Cloud AI Hypercomputer
Discover how Google Cloud's AI Hypercomputer revolutionizes AI workload management with advanced GPUs, TPUs, and dynamic scheduling, enabling efficient, scalable, and sustainable enterprise AI solutions.
Getting Started with VMware Private AI Foundation with NVIDIA
Discover how to efficiently deploy AI infrastructure using VMware's Private AI Foundation and NVIDIA, focusing on GPU selection, virtualization, and automated deployment for enterprise AI success.
Accelerator Clusters: The New Supercomputer
Discover how accelerator clusters are revolutionizing supercomputing through NVIDIA's innovative approach to high-performance computing architecture and interconnect technologies.
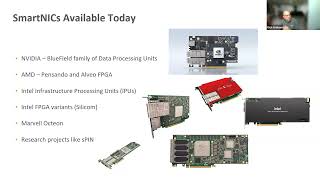
Leveraging SmartNICs for HPC and Data Center Applications - Part 1
Discover how SmartNICs revolutionize high-performance computing and data center operations, exploring key implementation strategies and performance optimization techniques for modern infrastructure.

Envisioning a Computational Storage Architecture with SDXI Data Mover - Early Efforts
Explore the integration of SDXI data mover technology with Computational Storage architectures, focusing on efficient data movement and host offloading strategies for enhanced storage performance.
Experiments with Non-Temporal Writes and Application Architectures
Explore non-temporal writes and their impact on application architectures through experimental insights and practical demonstrations.
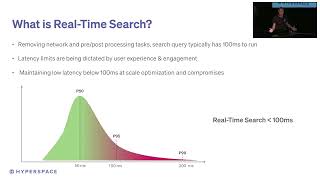
Breaking Search Performance Limits with Domain-Specific Computing
Explore advanced search techniques using domain-specific computing to achieve faster latencies and higher scalability at billion-scale, overcoming limitations of general-purpose CPUs.
Accelerate AI Inference Workloads with Google Cloud TPUs and GPUs
Optimize AI inference using Google Cloud's TPUs and GPUs. Compare accelerators for various workloads, deploy efficiently, and implement cost-effective strategies for high-performance model deployment.
AI Hardware and Real-world AI - JuliaCon 2024
Explore AI's computational impact, from theoretical understanding to efficient hardware design. Gain insights on optimizing AI models for real-world applications across various computational scales.
Programming Novel AI Accelerators for Scientific Computing - Part 2 - Tutorial 5
Explore advanced techniques for programming AI accelerators in scientific computing, focusing on optimization and performance enhancement.
Groq Tutorial - Part 5
Explore Groq's innovative AI hardware and software solutions for accelerating machine learning workloads and enhancing computational efficiency.