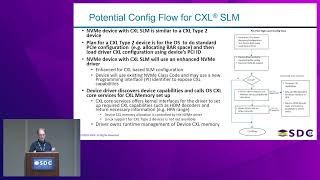
Host Addressable Subsystem Local Memory with NVMe and CXL Integration
Explore the integration of CXL and NVMe protocols, focusing on host addressable Subsystem Local Memory, computational storage benefits, and emerging developments in memory disaggregation.

Intel IPU and NVMe Initiator with SPDK - Introduction to Hardware Integration and Acceleration Framework
Discover how Intel's IPU hardware and SPDK Acceleration Framework optimize storage workflows, enhance data movement, and improve efficiency through hardware offloading capabilities for cloud service providers.

Memory Optimizations in Machine Learning
Discover essential memory optimization techniques for machine learning, from data quantization to model pruning, and learn efficient strategies for minimizing resource consumption across different hardware setups.

Smart Data Accelerator Interface (SDXI) - Use Cases, Proof Points and Future Development
Explore SNIA's Smart Data Accelerator Interface standard, covering use cases in AI, implementation demos, v1.1 features, and opportunities to contribute to this emerging memory-to-memory data movement technology.

CXL Technology for AI and ML Workloads - Memory Expansion and Performance Optimization
Explore how CXL technology revolutionizes AI/ML workloads through memory expansion, pooling, and sharing. Master performance optimization techniques for large language models and learn practical implementation strategies.
FPGA Microservices - Ultra-Low Latency with Off-The-Shelf Hardware
Discover how to achieve ultra-low latency in microservices using FPGA technology with off-the-shelf hardware, exploring practical implementations and performance optimization techniques.