Overcoming Challenges in Serving Large Language Models - SREcon23 Europe/Middle East/Africa
Explore hosting GPT models in Kubernetes, covering GPU sharding, tensor parallelism, and model optimization. Learn trade-offs between latency, accuracy, and resource allocation, with a live demo showcasing performance.

From Battlegrounds to Fairways - Terrain Procedural Tools in Frostbite
Explore Frostbite's innovative terrain procedural framework, enabling efficient creation of diverse game environments through automated workflows and GPU-based compositing for faster artist iteration.
Ray on Kubernetes - Powering Quantitative Research at Scale
Discover how Ray on Kubernetes revolutionizes quantitative research with scalable infrastructure supporting 100,000 CPU cores, spot instances, and seamless GPU integration for high-performance trading operations.
Kata Containers 4.0 - Full Lifecycle GPU Management for AI/ML Workloads
Discover how Kata Containers 4.0 revolutionizes GPU management for AI/ML workloads through CDI framework integration, enhanced security features, and streamlined resource allocation in Kubernetes environments.
Improving the World's Slowest Raytracer - RADV Implementation Progress
Dive into the evolution of RADV's raytracing implementation, exploring performance improvements, compatibility expansions, and current capabilities in Mesa 23.2's graphics rendering system.
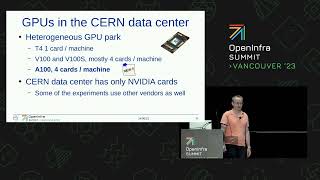
Multi-Instance GPU Deployment for Machine Learning and Particle Beam Simulations at CERN
Explore CERN's implementation of Multi Instance GPU technology using NVIDIA A100s, covering deployment strategies, virtualization approaches, and practical applications in machine learning and particle physics.
Sokovan - Container Orchestrator for Accelerated AI/ML Workloads and Massive Scale GPU Computing
Discover how Sokovan optimizes AI/ML workloads through intelligent container orchestration, featuring dual-layer scheduling and hardware acceleration integration for enhanced GPU computing performance.
Data Platform for End-to-End AI Democratization
Explore how data platforms enable AI democratization through unified processing and training architectures, improving efficiency for recommender systems and deep learning workloads.
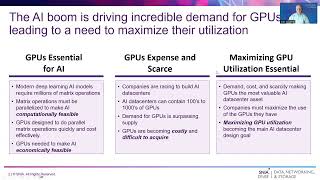
Storage Requirements for AI Infrastructure - From Data Preparation to Inference
Delve into the crucial role of storage systems across the AI lifecycle, from data preparation to inference, exploring performance requirements and infrastructure considerations for optimal GPU utilization.
Demolishing AI Gatekeepers - Breaking Down Barriers in AI Development
Explore how Web3 and decentralization can break Big Tech's monopoly on AI development by democratizing access to training data and GPU resources for unrestricted innovation.
Stable Diffusion 3.5 Large Tutorial - Configuration Guide and FLUX DEV Comparison
Master the optimal configuration and usage of Stable Diffusion 3.5 Large and FLUX DEV through SwarmUI, including model comparisons, LoRA implementation, and deployment across various computing platforms.
Rusticl OpenCL Implementation Status Update 2023
Discover the latest developments and implementations in Rusticl, exploring project updates and future outlook for this OpenCL implementation in Rust.
Mixture of Experts (MoE) in Large Language Models - A Simple Guide
Delve into the architecture and functionality of Mixture of Experts (MoE) systems in language models through clear examples and technical insights about token routing, gating networks, and computational efficiency.
Mistral 7B: Architecture, Performance and Implementation Guide
Dive into Mistral 7B's implementation, exploring grouped-query attention, efficient GPU usage, and hands-on demonstrations for running advanced language models on local hardware.
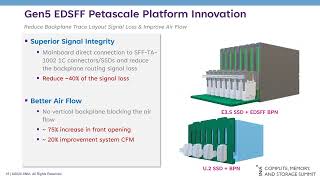
Storage Architecture Optimized for AI Workloads - High Performance Solutions for GPU Clusters
Discover how to optimize storage architecture for AI workloads, exploring high-performance solutions, capacity-optimized tiers, and real-world implementations for machine vision applications.

QLoRA: Efficient Training of Large Language Models Using Quantization and Low-Rank Adaptation
Discover how QLoRA enables efficient training of large language models on a single GPU through innovative techniques like NormalFloat, Double Quantization, and Paged Optimizers.
Fine-tuning Flan-T5 LLM with HuggingFace Accelerate - Tutorial
Learn how to fine-tune Flan-T5 LLM using HuggingFace Accelerate for multi-GPU environments, with step-by-step guidance on preprocessing and implementation for specific downstream tasks.
Fine-tune T5 Language Model for Text Summarization on Google Colab
Master fine-tuning techniques for T5 language models using HuggingFace's latest code, focusing on text summarization tasks with hands-on implementation in Google Colab's free GPU environment.
ChatGPT vs Flan-T5: Comparing Proprietary and Free LLMs with Performance Tuning
Explore the differences between ChatGPT and Flan-T5 LLM models, comparing their capabilities, accessibility, and performance optimization through practical demonstrations and hyperparameter tuning techniques.
Running BLOOM 176B LLM Inference with AWS ML and DeepSpeed
Dive into advanced LLM inference deployment using AWS's ml.p4de.24xlarge instance, exploring BLOOM 176B implementation with DeepSpeed and DJL for optimal performance and scalability.
Optimizing LLM Fine-Tuning with PEFT and LoRA Adapter-Tuning for GPU Performance
Master efficient fine-tuning of large language models using PEFT and LoRA techniques, optimizing GPU memory usage through INT8 quantization and adapter-tuning for cost-effective model development.