Tackling Kafka with a Small Team
Explore scaling Kafka with limited resources, covering challenges, failures, and tactical approaches for managing complex distributed systems in a fast-growing business environment.
SRE Classroom - How to Design a Distributed System in 3 Hours
Interactive workshop on designing distributed systems, covering scaling, failure handling, reliability, and consistency. Participants apply concepts to real-world scenarios using cloud components.
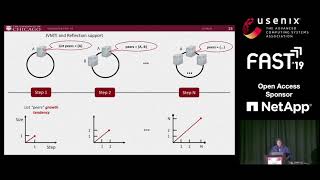
ScaleCheck - A Single-Machine Approach for Discovering Scalability Bugs in Large Distributed Systems
ScaleCheck: A novel approach for finding scalability bugs in large distributed systems using program analysis and colocation techniques, enabling testing at scale on a single commodity PC.
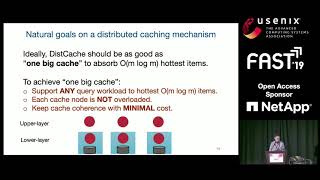
DistCache - Provable Load Balancing for Large-Scale Storage Systems with Distributed Caching
Innovative distributed caching mechanism providing provable load balancing for large-scale storage systems. Partitions hot objects and adaptively routes queries, enabling linear cache throughput increase with node count.
Datacenter RPCs Can Be General and Fast
Efficient RPC library for datacenter networks offering high performance without sacrificing generality. Handles packet loss and congestion while achieving low latency and high bandwidth on commodity hardware.
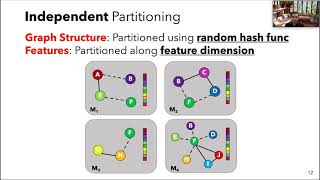
Distributed Deep Graph Learning at Scale
Explores a novel system for scaling Graph Neural Network training to large real-world graphs, introducing pipelined push-pull parallelism for faster and more efficient distributed processing.
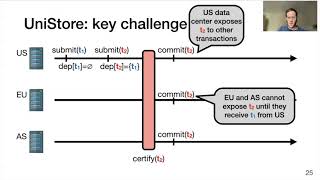
UniStore - A Fault-Tolerant Marriage of Causal and Strong Consistency
Explores a fault-tolerant data store combining causal and strong consistency for geo-distributed systems, addressing liveness challenges and optimizing durability costs in multi-consistency environments.
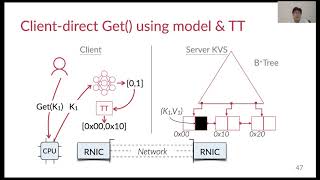
Fast RDMA-based Ordered Key-Value Store Using Remote Learned Cache
Explores XSTORE, an RDMA-based key-value store using machine learning models as cache for tree-based indexes, improving performance and scalability while efficiently handling dynamic workloads and reducing client-side memory usage.
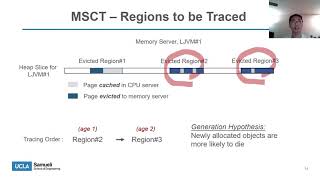
Semeru - A Memory-Disaggregated Managed Runtime
Innovative distributed JVM for memory-disaggregated environments, featuring a universal Java heap, distributed garbage collection, and efficient swap system to enhance managed cloud application performance.
Principled Performance Analytics
Explore innovative analytical methods for high-fidelity insights in distributed systems, focusing on performance analytics, statistical approaches, and practical applications in complex services at scale.
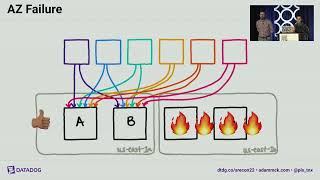
How the Metrics Backend Works at Datadog
Explore Datadog's metrics backend evolution, scaling challenges, and reliability solutions. Learn about distributed systems, Kafka implementation, and strategies for handling failures at various levels.
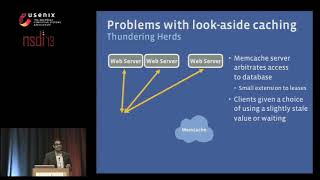
Scaling Memcache at Facebook
Explore Facebook's scaling of memcached to support billions of requests per second and trillions of items, enabling a rich experience for over a billion users worldwide.
Are We All on the Same Page? Let's Fix That
Explore Adaptive Paging, an innovative alert handler that uses tracing and heuristics to identify and notify the team closest to the problem, reducing alert fatigue in complex distributed systems.
Principles of Chaos Engineering
Explore principles of Chaos Engineering to improve resilience in distributed systems. Learn techniques for surfacing inherent chaos and building confidence in system behavior at scale.
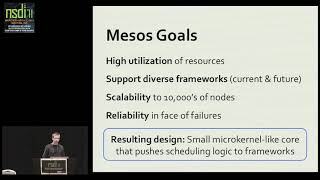
Mesos - A Platform for Fine-Grained Resource Sharing in the Data Center
Explore Mesos, a platform for efficient resource sharing in data centers. Learn about fine-grained allocation, resource offers, and improved cluster utilization across diverse computing frameworks.
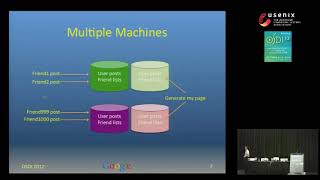
Spanner - Google’s Globally-Distributed Database
Explore Google's Spanner: a globally-distributed database with scalability, multi-version support, and synchronous replication. Learn about its structure, features, and innovative time API for external consistency.
In Search of an Understandable Consensus Algorithm
Explore Raft, a consensus algorithm for replicated logs, designed to be more understandable than Paxos while maintaining efficiency and providing a solid foundation for practical systems.
CRaft - An Erasure-coding-supported Version of Raft for Reducing Storage Cost
Explores CRaft, an erasure-coding-supported version of Raft consensus protocol, reducing storage and network costs while maintaining fault tolerance and liveness. Presents design, challenges, and performance improvements.
Why Are Distributed Systems So Hard?
Explore distributed systems' challenges, from CAP theorem myths to network partitions. Learn consensus algorithms, system design for adaptability, and strategies to mitigate risks in distributed computing.
What Happens When You Type en.wikipedia.org
Explore Wikipedia's server-side architecture, from routers to microservices, and learn how open-source technologies power one of the world's top websites.
Everyone Loves File - File Storage Service in Oracle Cloud Infrastructure
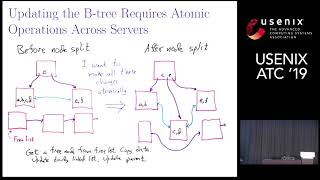
Explore Oracle Cloud's File Storage Service architecture, featuring scalable block store, B-tree implementation, and nonblocking programming for efficient, elastic NFS service with predictable performance.