Building Super-Contributors in Alluxio Open Source Community
Discover strategies for cultivating exceptional contributors in open-source projects, focusing on Alluxio's community-building approach and best practices.
Maximizing Query Speed and Minimizing Costs in Data Lakes with Open-Source Caching
Discover how to optimize data lake performance and reduce costs using open-source caching frameworks, with practical techniques for query acceleration and storage efficiency.
Advancing GPU Analytics with RAPIDS Accelerator for Apache Spark and Alluxio
Learn to accelerate GPU analytics using RAPIDS for Apache Spark and Alluxio, enabling faster data access and processing for AI and analytics workloads across any cloud environment.
Accelerating Spark Workloads in a Mesos Environment with Alluxio
Learn how Alluxio enhances Spark and Mesos performance by providing memory-speed data access across disparate storage systems, optimizing big data processing and enabling new workloads.
Accelerating Spark Workloads in an Apache Mesos Environment with Alluxio
Learn how Alluxio enhances Spark and Mesos performance by providing memory-speed data access across diverse storage systems, optimizing big data processing and enabling new workloads.
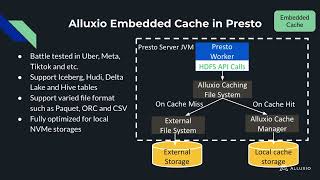
Caching Framework for Exabyte-Scale Data Lakes
Optimize exabyte-scale data lakes with open-source caching framework. Improve performance, reduce costs, and tackle challenges in complex data environments using Hadoop, Parquet, Hudi, and Alluxio.

Tackling I/O Challenges in Modern Data Lakes
Explore data lake evolution, cloud-native trends, and efficient data retrieval for big data analytics and AI workloads. Gain insights into I/O challenges and success stories in modern data platforms.
Secure and Efficient Data Sharing with Federated Cloud Storage
Discover how to build a virtual data lake system using federated cloud storage, focusing on secure data sharing between enterprises through metadata management and integration of open-source tools.
Data Caching for Enterprise-Grade Petabyte-Scale OLAP
Explores Alluxio local cache for petabyte-scale OLAP, optimizing data transfer efficiency in decoupled compute-storage models. Shares insights from Uber and Meta deployments.
Distributed Caching for Generative AI: Optimizing LLM Data Pipeline on the Cloud
Optimize LLM data pipelines on the cloud using distributed caching. Explore I/O challenges, best practices, and real-world applications to enhance efficiency in AI workloads and model training.