Understanding Microsoft Fabric - Video 2
Explore Microsoft Fabric's architecture, services, and key concepts for self-service data analytics and AI, building on UI basics from the previous video.
OpenLineage: An Open Standard for Data Lineage
Explore OpenLineage, an open framework for data lineage metadata collection. Learn its purpose, data model, and integration with tools like Apache Airflow and Spark to enhance pipeline understanding and management.
Whisky Clustering with Apache Projects - Groovy, Commons Math, Ignite, Spark, Wayang, Beam and Flink
Analyze top distilleries' whiskeys using K-means clustering from Apache projects to identify the perfect single-malt Scotch. Explore data analysis with Groovy, Commons Math, Ignite, Spark, Wayang, Beam, and Flink.

Analyzing Big Data in Azure Cloud Using Spark and Databricks
Explore Azure Databricks' key features and Spark scenarios through demos, gaining insights on best practices for big data analysis in the Azure cloud.
Building a Lakehouse on the Microsoft Intelligent Data Platform
Explore Lakehouse architecture on Microsoft Intelligent Data Platform. Learn Synapse Analytics, Delta format, and Spark-based engines for efficient big data processing and analytics.
Powering Up Your Power BI Development Workflow with Microsoft Fabric Notebooks
Explore Microsoft Fabric Notebooks: Learn Python, Spark basics, and advanced analytics with SemPy. Enhance Power BI development using CoPilot for code assistance.
Data Engineering in Microsoft Fabric - Getting Started with Notebooks and Lakehouse
Explore data engineering in Microsoft Fabric: Notebooks, Lakehouse flexibility, Spark configurations, and Copilot-enhanced efficiency for developers.
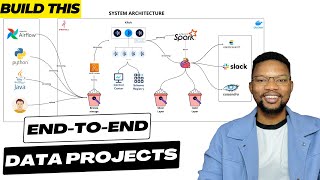
Building Data Lakehouse from Scratch - End-to-End Data Engineering Project
Design, implement, and maintain scalable lakehouse architectures using Apache Spark, Kafka, Flink, Delta Lake, AWS, and open-source tools. Enhance data potential through advanced analytics and machine learning.
Building a Unified Feature Platform with DuckDB and Arrow
Explore ML feature platform development using DuckDB and Arrow. Learn scaling strategies, DuckDB extension implementation, DeltaLake interoperability, and performance comparison with Spark.

Apache Spark Performance Tuning and Best Practices
Optimize Apache Spark performance with best practices for production environments, covering system tuning, casting, broadcasting, serialization, and memory management.

Apache Spark Structured APIs Using Databricks
Master Apache Spark Structured APIs for data manipulation using Databricks. Learn RDD, DataFrame API, data aggregation, and ETL operations in this comprehensive overview.

Getting Started with Delta Lake on Databricks
Explore Delta Lake's optimized data storage in Databricks, enhancing query performance and enabling time travel while reducing system complexity.

CodeCamp - Functional Programming Principles
Master functional programming principles and apply them to build scalable, efficient applications using Scala's powerful features.

CodeCamp: Functional Programming Principles - Part 2
Master functional programming principles in Scala, exploring polymorphic functions, data structures, and pattern matching for industry-ready applications.

Getting Started with Apache Spark
Learn Apache Spark's architecture, data lineage, and DAG concepts. Explore this multi-language engine for data engineering, data science, and machine learning on single-node machines or clusters.

Introduction to PySpark
Learn the fundamentals of PySpark for efficient big data processing and analytics using Python in Apache Spark's distributed computing environment.
Moving Data Platforms from Hadoop to Kubernetes
Explore migrating data platforms from Hadoop to Kubernetes, improving operations and developer satisfaction while enhancing performance and deployment strategies.
What's New in Serverless Spark for Data Analytics and AI
Explore Walmart's approach to simplifying data analytics using Spark on Google Cloud, combining open-source flexibility with cloud-native advantages for scalable, secure solutions.
The Birth and Growth of Spark: An Open Source Success Story
Explore a insightful conversation with Matei Zaharia, creator of Apache Spark, on open-source success, MLflow development, and the future of AI applications combining LLMs with other systems.
The Emerging Toolkit for Reliable, High-quality LLM Applications
Explore emerging techniques in LLMOps for building, tuning, and maintaining high-quality LLM applications. Learn about testing tools, programming frameworks, and methods to control LLM outputs for desired goals.
Securing Apache Spark Big Data Operations: Threats, Best Practices, and Pragmatic Steps
Explore Apache Spark security best practices, threat modeling, and practical steps to safeguard big data operations in various environments.