Operating Deep Learning Pipelines Anywhere Using Kubeflow
Explore building and operating production-grade deep learning pipelines using Kubeflow, covering data preparation, storage, automation, and infrastructure management for multiple tenants.
Apache Spark on Kubernetes - A Technical Deep Dive
Explore Apache Spark's native integration with Kubernetes, including technical details, benefits, and future roadmap for large-scale data processing applications.
Building MLOps POCs and Sandbox Environments Using k3s and Argo
Explore building MLOps POCs using k3s and Argo. Learn to reduce implementation time and costs for data pipeline automation and ML workflows, with insights on lightweight Kubernetes and Edge Computing.
Scala - The Unpredicted Lingua Franca for Data Science
Explore how Scala has become a key language for data science, offering distributed computing capabilities and integrating seamlessly with big data technologies like Apache Spark.
Build a Recommender System in Apache Spark and Integrate It Using Akka
Learn to build and integrate a recommender system using Apache Spark and Akka HTTP. Discover the components of recommender systems and implement one with machine learning techniques in a practical, hands-on session.
Distributed Real Time Stream Processing - Why and How
Explore state-of-art distributed streaming frameworks, their differences, trade-offs, and use-cases. Learn how to choose between Spark Streaming, Storm, Samza, and Flink for your specific streaming needs.
Beyond Shuffling - Scaling Apache Spark
Scaling Apache Spark: best practices for large datasets, performance optimization, and efficient data processing techniques. Covers counters, key/value operations, caching, and functional transformations with Datasets.
The Future of Scala Performance on Big Data
Explore Scala's performance in big data, new benchmarks, and optimizations for datacenter computing. Gain insights into Apache Spark and real-world workload improvements.
Distributed Real-Time Stream Processing - Why and How
Explore state-of-the-art open-source distributed streaming frameworks, their trade-offs, use-cases, and selection criteria. Learn about Spark Streaming, Storm, Samza, and Flink for modern data processing challenges.
Scala - The Unpredicted Lingua Franca for Data Science
Explore Scala's emergence as a key language for data science, covering its features, integration with Spark, and advantages over traditional options like Python and R.
Scala and the JVM as a Big Data Platform - Lessons from Apache Spark
Explore Scala's advantages for Big Data, focusing on Apache Spark. Learn about JVM optimizations and Spark's Tungsten project for improved performance in data processing.
Connecting Reactive Applications with Fast Data Using Reactive Streams
Explore integrating Spark Streaming with reactive applications using Reactive Streams. Learn about Spark's streaming model, back pressure support, and see a demo of a fully integrated reactive system.
Build a Recommender System in Apache Spark and Integrate it Using Akka
Learn to build and integrate a recommender system using Apache Spark and Akka HTTP. Discover the basics of machine learning and how to implement it in your applications for personalized recommendations.
Fault Tolerance in Distributed Systems - A Case Study in Apache Spark
Explore fault tolerance in distributed systems through Apache Spark, examining design principles, challenges, and lessons for building robust systems and understanding their limitations.
Analyzing Pwned Passwords with Apache Spark
Learn to analyze large datasets of compromised passwords using Apache Spark, exploring data processing techniques and security implications in this Scala Days conference talk.
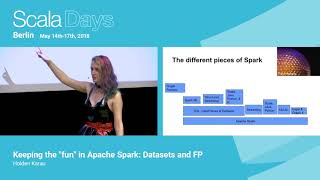
Keeping the Fun in Apache Spark - Datasets and FP
Explore Apache Spark's Datasets and functional programming techniques for efficient data processing, with insights on maintaining code readability and performance optimization.
Keeping the Fun in Apache Spark Datasets and FP
Explore functional programming techniques in Apache Spark Datasets with Holden Karau, focusing on maintaining enjoyment while leveraging powerful data processing capabilities.
Analyzing Pwned Passwords with Apache Spark
Learn to analyze compromised passwords using Apache Spark, exploring data processing techniques and security implications in this Scala Days conference talk.
A Story of Unification from Apache Spark to MLflow
Explore the journey of unification from Apache Spark to MLflow, highlighting key developments and innovations in big data processing and machine learning workflows.
Gallia - Practical Data Transformation in Scala
Explore Gallia, a schema-aware Scala library for practical data transformation. Learn its benefits, usage, and comparison with alternatives like Pandas and Apache Spark through live coding demonstrations.
Stream Data Processing for Fun and Profit
Explore distributed data processing frameworks for handling large-scale event streams. Learn about Apache Storm, Spark, and emerging platforms to build reliable, scalable systems for real-time data processing.