Building AI Applications with Transformers
Learn to leverage transformers for AI applications like auto-completion, semantic search, and document AI using open-source tools and models. Explore embeddings, Generative AI, and emerging trends in multimodal and large language models.
Transformer and Large Language Models - Part I - Lecture 12
Explore Transformer architecture and Large Language Models in this comprehensive MIT lecture, covering key concepts and recent advancements in AI.
Transformer and Large Language Models - Part I - Lecture 12
Explore Transformer architecture and Large Language Models in this comprehensive MIT lecture, covering key concepts and recent advancements in AI.
Transformer and Large Language Models - Part II - Lecture 13
Explore advanced concepts of Transformers and Large Language Models in this in-depth lecture from MIT's EfficientML course.
Transformer and Large Language Models - Part II - Lecture 13
Explore advanced concepts of Transformers and Large Language Models, focusing on efficiency and optimization techniques in AI and machine learning.
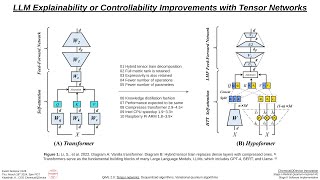
LLM Explainability and Controllability Improvements with Tensor Networks
Explore how Tensor Networks enhance explainability and controllability of Large Language Models, focusing on transformer self-attention and multi-layer perceptron layer modifications.
The Emergence of Essential Sparsity in Large Pre-trained Models
Explore essential sparsity in large pre-trained models, examining efficient handling of complex transformers and the impact of weight removal on performance.
Knowledge Circuits in Pretrained Transformers Explained
Explore knowledge circuits in pretrained transformers, uncovering computational mechanisms behind language models' articulation of specific knowledge. Gain insights into AI's inner workings.
Toward Length Extrapolatable Transformers
Explore innovative techniques for enhancing transformer models' ability to handle longer sequences, improving their performance and scalability in natural language processing tasks.
An Overview and Challenges of Interactive HMI for Realizing Human-Like Interaction - 2024 JSALT
Explore interactive human-machine interfaces, their history, and recent advancements. Delve into HMI components, text-to-speech research, and future challenges in realizing human-like interactions.
EyeFormer - Predicting Personalized Scanpaths with Transformer-Guided Reinforcement Learning
Dive into advanced eye-tracking prediction using transformer-guided reinforcement learning to understand and model personalized visual attention patterns and scanpaths.
Reinforcement Learning with Human Feedback - Understanding LLM Fine-tuning with PPO and DPO
Dive into the fundamentals of Reinforcement Learning with Human Feedback (RLHF) and discover how PPO and DPO techniques enhance large language models for improved text generation.
Hardware-aware Algorithms for Language Modeling - FlashAttention and Mamba Architectures
Delve into advanced hardware optimizations for language models, exploring FlashAttention-3's improvements and Mamba's efficient architecture for enhanced performance and linear scaling capabilities.
Towards Compositional Interpretability for XAI
Explore a mathematical framework using category theory and string diagrams to understand AI model interpretability, focusing on compositional structures and their explainability benefits in neural networks and transformers.
Fourier-Enhanced Fine-Tuning Vision Language Models Using PEFT-VFPT
Discover how Visual Fourier Prompt Tuning revolutionizes vision model fine-tuning by integrating Fast Fourier Transform, enhancing adaptability and accuracy while using minimal trainable parameters.

TokenFormer - Rethinking Transformer Scaling with Tokenized Model Parameters
Delve into an innovative approach to transformer architecture scaling that treats model parameters as tokens, enabling flexible parameter adjustments without complete retraining from scratch.
Fine-tuning T5-Large Model for Text Summarization with MLFlow
Master fine-tuning T5-Large models for text summarization using MLflow, covering model tracking, logging, and specialized training techniques for enhanced summarization capabilities.
Introduction to AI - Understanding Core Technologies and Implementation Best Practices
Gain insights into AI fundamentals, from NLP and machine learning to ethical considerations, while exploring real-world applications, security practices, and implementation strategies.

Encoder-Only Transformers: Understanding BERT and RAG Architecture
Discover how encoder-only transformers power RAG, sentiment analysis, and classification through clear explanations of word embedding, positional encoding, and attention mechanisms.
Evaluating World Models in Generative AI - A Critique of AI Intelligence Assessment
Explore groundbreaking research from top universities challenging AI evaluation methods, revealing limitations in language models' structural understanding and proposing new assessment frameworks.
How Transformers Learn Causal Structure with Gradient Descent
Delve into the mathematical foundations of how transformer models learn and encode causal relationships through self-attention mechanisms and gradient-based training algorithms.