Transformers from Scratch - Part 2: Building and Training a Weather Prediction Model
Dive deep into advanced transformer concepts, exploring encoder-decoder architectures, GPT-4o, and positional embeddings. Apply knowledge to weather prediction and analyze model performance.
Fine-Tuning a Diffusion Model with Your Photos
Learn to fine-tune a diffusion model using your own photos. Explore Flux Schnell, set up GPU environments, create datasets, and understand the intricacies of diffusion models and their architectures.
Fast LLM Serving with vLLM and PagedAttention
Explore vLLM, an open-source library for fast LLM inference using PagedAttention. Learn how it achieves higher throughput and its implementation for efficient AI model serving.
Synthetic Data - Friend or Foe in the Age of Scaling?
Explore synthetic data's impact on AI scaling laws, model performance, and potential degeneration. Analyze theoretical frameworks and experimental findings for future AI development challenges.
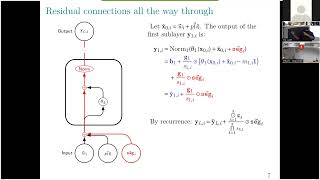
Linear Structures in Transformer Embedding Spaces
Explore linear structures in Transformer embedding spaces, examining anisotropy, BERT's next sentence prediction, layer behavior, and multi-head attention modules.
Metric Space Magnitude and Generalization in Neural Networks
Exploring metric space magnitude in neural networks: new topological complexity measures for assessing generalization capabilities, with applications to transformers and deep graph networks.

Python Apple MLX Tutorial: Introduction to Machine Learning on Apple Silicon
Learn MLX framework for Apple Silicon: GPU operations, transformers, language models, and generative AI concepts. Applicable to PyTorch and NumPy users.

Informer Architecture Explained - Complete Guide
Comprehensive exploration of Informer encoder architecture, detailing its components and implementation for advanced time series forecasting and sequence modeling tasks.

Informer: Training and Inference
Explore time series prediction using Informer, a transformer-based model. Learn to train and make predictions through hands-on coding, enhancing your skills in advanced forecasting techniques.
Pioneering a Hybrid SSM Transformer Architecture - Jamba Foundation Model
Explore AI21 Labs' Jamba: a groundbreaking hybrid Transformer-Mamba MoE model with unparalleled throughput and a 256K context window, revolutionizing large language model development.
Understanding the Expressive Power of Transformers Through Formal Language Theory
Explore the intersection of formal language theory and machine learning, focusing on transformer expressiveness and recent developments in understanding their learning capabilities.
Learning Linear Models In-Context with Transformers
Explore in-context learning of linear models using transformers with UC Davis professor Spencer Frei in this insightful seminar.
Text-to-Speech Fine-tuning Tutorial - StyleTTS2 Voice Cloning and Model Adaptation
Master text-to-speech fine-tuning techniques, from dataset preparation to model training. Explore voice cloning, StyleTTS2, and performance optimization for advanced speech synthesis projects.
Efficient Transformers - Lecture 20
Explore efficient transformer architectures for optimized deep learning on resource-constrained devices. Learn techniques to enhance performance and reduce computational demands.
Efficient Transformers - Lecture 20
Explore efficient transformer architectures for optimized deep learning on resource-constrained devices. Learn techniques to enhance performance and reduce computational demands.

Privacy Backdoors: Stealing Data with Corrupted Pretrained Models - Explained
Explore how tampering with pretrained models can compromise privacy, enabling attackers to reconstruct finetuning data. Learn about privacy backdoors in transformers and their implications for machine learning security.

Informer: Complete Code from Scratch - Time Series Transformer Analysis
Line-by-line exploration of the time series transformer, focusing on implementation details and code structure for deep learning enthusiasts and practitioners.
Getting Started with Generative Text and Fine-Tuning LLMs in Hugging Face
Dive into practical LLM implementation using Hugging Face's transformers library, from basic text generation to efficient model fine-tuning techniques for customized applications.
Vision Transformer for Efficient Machine Learning - Lecture 16
Dive into Vision Transformer architecture and implementation with MIT Prof. Song Han, exploring key concepts and practical applications in modern computer vision and machine learning.
Long-Context Large Language Models - Lecture 15
Dive into advanced techniques for handling extended context in Large Language Models, exploring efficiency strategies and implementation methods for enhanced AI processing capabilities.

Deep Dive into ChatGPT: Architecture and Comparison with Bard and LLaMa
Explore ChatGPT's architecture, implementation, and evolution. Compare with Bard and LLaMa. Learn to build tinyGPT. Gain insights into transformers, attention mechanisms, and the GPT family of models.