Managing Vendor Incidents - Strategies for Effective Incident Management
Dive into effective strategies for managing vendor incidents, from classifying vendors to building relationships and handling documentation issues. Learn to create runbooks, collect essential information, and conduct post-incident reviews.
ServiceNow SLA
Learn to create and manage Service Level Agreements (SLAs) in ServiceNow. Covers SLA definitions, workflows, schedules, and durations for administrators and developers.

ServiceNow SLA Configuration - SLA Definition
Learn to configure and manage Service Level Agreements (SLAs) in ServiceNow, including creation, definition, workflows, and application across various stages and states.

ServiceNow
Comprehensive ServiceNow training covering API integrations, workflows, service portal development, asset management, and advanced features for beginners and experienced users.
ServiceNow Tutorials
Comprehensive tutorials on ServiceNow covering problem management, security, user management, reporting, and comparisons with Cherwell. Ideal for administrators and IT professionals.
Starting the SLOs Implementation
Learn to implement Service Level Objectives (SLOs) effectively, enhancing system reliability and performance in site reliability engineering practices.
SLA vs SLO: Optimizing Service Levels for Revenue Generation
Discover how to optimize SLO metrics beyond SLA compliance to maximize revenue potential, using dynamic system evaluation and feature-value assessment in high-traffic infrastructure environments.
Oracle Multitenant - Best Practices for Rapid Deployment and Workload Isolation
Explore Oracle Multitenant's comprehensive isolation architecture and best practices for rapid deployment, focusing on efficiency, agility, and workload provisioning in database management.
Improving the Reliability of Kubernetes Load Balancers
Explore strategies to enhance Kubernetes load balancer reliability, addressing failure modes, optimizing configurations, and improving application-specific traffic routing for better SLA adherence.
SLIs, SLAs, and SLOs - Learning About Service Uptime from Homer Simpson
Explore service uptime concepts through Homer Simpson's lens. Learn about SLIs, SLAs, and SLOs in a fun, engaging way to improve your understanding of system reliability.
Don't Get Out of Bed for Anything Less Than an SLO
Learn how to implement effective Service Level Objectives (SLOs) to improve system reliability and prioritize engineering efforts in DevOps practices.
Confessions of a Systems Engineer - Learning from My 20+ Years of Failure
Insights from a seasoned systems engineer on designing and running large-scale online services, drawing from 20+ years of failures and lessons learned in the tech industry.
Site Reliability Engineering at Google
Explore Google's approach to Site Reliability Engineering, covering dev-ops collaboration, error budgets, staffing strategies, and incident management for maintaining large-scale infrastructure.
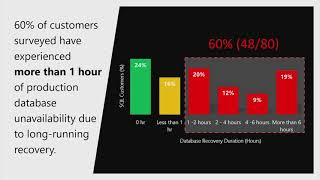
Improving Availability in SQL Server and Azure SQL Database with Accelerated Database Recovery and Resumable Operations
Discover innovations in SQL Server 2019 and Azure SQL Database that enhance database availability, reduce downtime, and streamline maintenance operations for improved performance and reliability.
Kubernetes? But I'm a Product Manager
Discover how Kubernetes can benefit product managers in delivering better products faster, focusing on extensibility, scalability, and cloud-agnostic solutions for improved customer outcomes.
DataOps as a Service - Applying DevOps Practices to Data Engineering
Explore DevOps practices in data engineering, addressing challenges and showcasing the Versatile Data Kit for implementing DataOps principles.
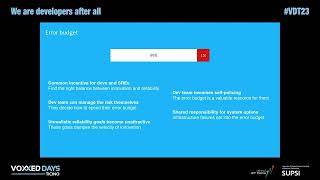
SRE - What Is It All About?
Explore Site Reliability Engineering concepts, including SLAs, SLIs, SLOs, error budgets, and reliability prioritization. Learn how to implement SRE methodology and improve service reliability.
5G Transport Network Slicing with Cisco Crosswork Network Controller
Dive into advanced network slicing capabilities for 5G transport using Cisco Crosswork, exploring deployment scenarios, orchestration management, and innovative service assurance features for optimal SLA delivery.
Multi-Tenancy in Self-Served Platforms - Challenges and Solutions
Explore real-time data reporting platform challenges, including self-service adoption, noisy neighbor issues, and multi-tenancy solutions for improved performance and resource isolation.
Traffic Management: Quality of Service and Integrated Service Model - Part 2
Explore Quality of Service (QoS) concepts, including its necessity and implementation methods, with a focus on the Integrated Service Model.
Latency Monitoring Metrics: Why Average Is Not a Good Measure
Explore why average latency metrics are inadequate. Learn about max latency, true impact, and latency distributions for comprehensive monitoring and analysis of system performance.