In-SRAM Computing for Generative AI and Large Language Models
Explore innovative In-SRAM computing architecture and its role in reducing power consumption for large language models and generative AI in datacenter environments.

Quantization in Deep Learning: Types, Algorithms, and Implementation
Explore quantization techniques in deep learning, from uniform to non-uniform approaches, and learn practical implementation strategies for optimizing large-scale neural networks.
Simple Quantization of LLMs - A Hands-on Guide to Absolute Max and Zero Point Methods
Master practical LLM quantization techniques through hands-on implementation of Absolute Max and Zero Point methods, building foundational skills for advanced approaches like GPTQ and AWQ.

QLoRA: Efficient Training of Large Language Models Using Quantization and Low-Rank Adaptation
Discover how QLoRA enables efficient training of large language models on a single GPU through innovative techniques like NormalFloat, Double Quantization, and Paged Optimizers.
AI Phone: From Voice Assistants to Advanced AI Integration and Reasoning
Explore the revolutionary concept of AI Phone technology, from LLM quantization to advanced reasoning systems, and discover how AI-centric devices could transform mobile computing and human interaction.
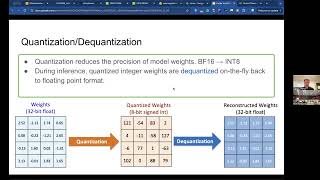
Faster and Cheaper LLMs with Weight and Key-value Cache Quantization
Explore advanced techniques for optimizing Large Language Models through weight and key-value cache quantization methods to improve speed and reduce computational costs.
Debugging Machine Learning on the Edge with MLExray
Explore MLExray for efficient debugging of edge-deployed machine learning models, covering benefits, deployment challenges, and practical demonstrations.
SAMPL Research Group Presentations on Machine Learning Hardware and Systems
Presentations on cutting-edge machine learning hardware, efficient cloud communication, dynamic tensor rematerialization, alternative datatypes, and quantized ML kernels by UW graduate students.
High Fidelity Neural Audio Compression - Paper & Code Explained
Explore neural audio compression techniques achieving 10x compression rates, with in-depth analysis of paper and code implementation, including VQ-VAE, VQ-GAN, and AudioGen applications.
Deploying Optimized Deep Learning Pipelines
Survey of deep learning pipeline optimization techniques, exploring quantization, distillation, and math library selection. Discusses trade-offs for deployment and provides insights for efficient ML implementation.
Leaner and Greener AI with Quantization in PyTorch - Suraj Subramanian
Discover how quantization in PyTorch can make AI models lighter, faster, and more power-efficient without compromising accuracy. Learn techniques and workflows from an ML expert at Meta AI.
Scaling Up AI Research to Production with PyTorch and MLFlow
Explore PyTorch's latest advancements in AI research and production, including distributed training, model optimization, and deployment using MLFlow, with insights on scaling and efficiency.
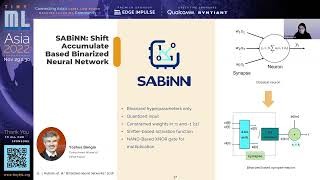
Power Efficient Neural Network Based Hardware Architecture for Biomedical Applications
Power-efficient neural network hardware architecture for biomedical applications, focusing on sleep apnea detection using ECG and SpO2 data. Introduces SABiNN technique for reduced power consumption and compact design while maintaining accuracy.
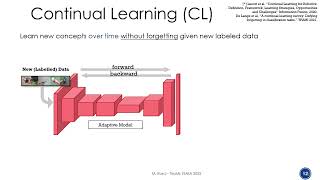
Continual On-Device Learning on Multi-Core RISC-V Microcontrollers
Explore continual on-device learning for multi-core RISC-V microcontrollers, focusing on system architecture, memory-energy-accuracy trade-offs, and efficient implementation of backpropagation techniques using latent replays.
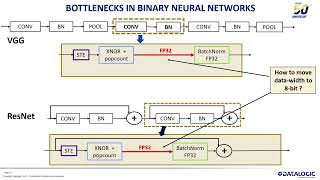
Optimizing Data-Flow in Binary Neural Networks
Explore optimizing data flow in Binary Neural Networks, focusing on hardware efficiency, quantization techniques, and accuracy improvements for embedded systems.
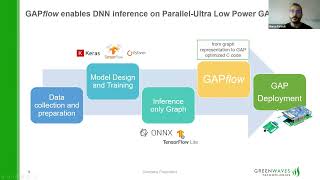
TinyML Auto ML Deep Dive: GAPflow - From TFLite and ONNX to Optimized C Code
Explore GAPflow: transform neural networks into optimized C code for ultra-low-power GAP processors. Learn quantization, validation, and memory allocation for efficient AI deployment on energy-constrained devices.
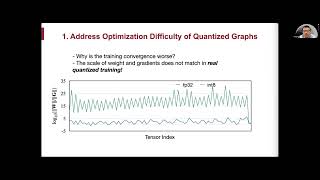
On-Device Learning Under 256KB Memory - Challenges and Solutions for IoT Devices
Explore on-device learning for IoT devices with limited memory. Learn techniques for efficient model adaptation, quantization-aware scaling, and sparse updates to enable continuous learning on tiny hardware.
Inference and Quantization for AI - Session 3
Explore quantized inference, TensorRT 5, and TensorFlow integration for AI model optimization. Learn about NVIDIA's inference server and techniques to improve model efficiency and performance.
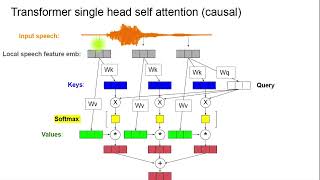
On-Device Speech Models Optimization and Deployment for Mobile Hardware
Explore on-device speech model optimization and deployment, covering streaming-aware design, quantization techniques, and benchmarks for popular speech processing model topologies on mobile platforms.
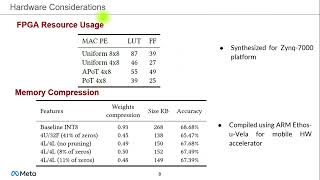
Power-of-Two Quantization for Low Bitwidth and Hardware Compliant Neural Networks
Explore power-of-two quantization for efficient neural networks, focusing on low bitwidth and hardware compatibility. Learn about key problems, methods, and results in this cutting-edge research.

TinyML Talks Germany - AutoFlow - An Open Source Framework to Automatically Implement Neural
Explore AutoFlow: an open-source framework for automating neural network implementation on embedded devices, covering model building, optimization, and deployment.