Master Databricks and Apache Spark Step by Step - PySpark Using RDDs
Explore PySpark and RDDs in Databricks: Learn about lazy evaluation, transformations, and actions while analyzing data using Resilient Distributed Datasets.
Cryptography - Cryptocurrency and Blockchain
Explore cryptocurrency fundamentals, Bitcoin mechanics, Ethereum setup, and smart contracts in this comprehensive overview of blockchain technology.
Data Science: Introduction to Pandas
Explore Pandas for data manipulation: peek, sort, filter, and analyze with mathematical functions, correlation, and covariance.
Data Science Tutorial 1 - Pandas Analysis
Learn to analyze data using Pandas, covering data types, columns, plotting, correlation, and covariance in this comprehensive tutorial.
Data Analysis with Pandas
Learn essential Pandas techniques for data analysis, including data manipulation, correlation analysis, and visualization, to enhance your Python data science skills.
Cyber & Data - What is Data?
Explore data types, formats, and structures in cybersecurity. Learn parsing, encoding, compression, and file analysis techniques for effective data handling and security.
Pandas UDFs and Python Type Hints in Apache Spark 3.0
Explore redesigned pandas UDFs in Apache Spark 3.0, leveraging Python type hints for clearer, more Pythonic data science workflows and improved static analysis capabilities.
Accelerating Data Processing in Spark SQL with Pandas UDFs - Optimization Techniques
Learn to optimize Spark SQL data processing using Pandas UDFs. Discover techniques to speed up queries, profile jobs efficiently, and leverage custom UDFs for significant performance gains in large-scale data pipelines.
Data Microservices in Apache Spark Using Apache Arrow Flight
Explore efficient machine learning pipelines using Apache Arrow Flight in Spark, enabling faster data transport and simplified microservices for improved ML model production.
Data Science Across Data Sources with Apache Arrow - Accelerating Analytics and Interoperability
Explore Apache Arrow's columnar in-memory data representation for real-time analytics across distributed systems. Learn how it accelerates data processing and enables interoperability between various analytical tools and data sources.
AutoML Toolkit Deep Dive - Automating Feature Engineering and Model Optimization
Explore Databricks Labs' AutoML Toolkit for automating feature engineering, model selection, tuning, and deployment. Learn to accelerate machine learning workflows and enhance productivity.
Portable and Scalable Data Visualization Techniques for Apache Spark and Python Notebooks
Explore portable and scalable data visualization techniques for Apache Spark and Python notebooks, covering strategies, packages, headless rendering, animations, and big data integration.
Introducing Apache Spark 3.0 - A Decade of Progress and Future Outlook
Apache Spark 3.0: Reflecting on a decade of progress and unveiling new features to enhance data processing accessibility, speed, and compatibility across various sources and environments.
Managing the Complete Machine Learning Lifecycle with MLflow - Introduction to MLflow Tracking
Introduction to MLflow: tracking experiments, packaging projects, deploying models, and managing lifecycle. Learn to record, reproduce, and compare ML runs using MLflow's components and UI.
WooCommerce for Beginners
Learn to set up and manage an online store with WordPress's popular e-commerce plugin. Master product creation, pricing, upsells, and customization to launch your successful digital storefront.
Shopify vs. WooCommerce - Comparing Top eCommerce Platforms
Comprehensive comparison of Shopify and WooCommerce, exploring key features, ease of use, customization options, and pricing to help you choose the best eCommerce platform for your online store.
WooCommerce for Beginners
Learn to set up and customize an online store with WooCommerce. Master product management, configure settings, and explore extensions to enhance your WordPress-based e-commerce platform.
Improving Apache Spark Application Processing Time - Configuration and Optimization Techniques
Optimize Spark streaming app performance through configurations, code improvements, and custom data source implementation for processing 700 MB/s of compressed data with strict KPIs.
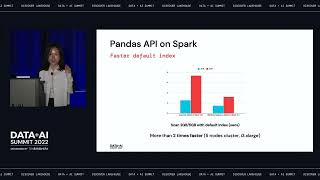
PySpark in Apache Spark 3.3 and Beyond
Explore PySpark's evolution in Apache Spark 3.3, including improved Pandas API, enhanced productivity features, and future developments. Learn about new functionalities, usability improvements, and performance enhancements.

Jump Start on Data Science with an Azure Data Science VM
Learn to quickly set up and use an Azure Data Science Virtual Machine, equipped with essential tools for data science and machine learning projects.
Running Linux Apps on Windows - How and Why?
Explore running Linux apps on Windows with WSL, covering Windows Terminal, Docker, and GUI applications. Learn about system architecture, performance, and practical use cases.