Understanding Graph Neural Networks - Part 1
Comprehensive introduction to Graph Neural Networks, covering fundamentals, mathematics, and practical implementation using NetworkX and PyG. Ideal for beginners seeking hands-on experience with GNNs.
How You Can Build Your Own Worldwide Wildfire Data Collection and Host on Kaggle
Learn to collect, process, and visualize global wildfire data using NASA sources, data engineering techniques, and tools like Kepler.gl, mapboxgl, and Streamlit for insightful analysis and presentation.
Implementing Nivo Graphs into CoreUI React Template
Comprehensive guide to integrating Nivo graphs into CoreUI React template, covering various chart types, customization, and implementation steps for creating interactive data visualizations.
A Very First Look at H2O Hydrogen Torch
Explore H2O Hydrogen Torch: a no-code deep learning tool for diverse AI tasks. Learn its capabilities, experiment as novice and expert, and understand prediction pipelines and deployment options.
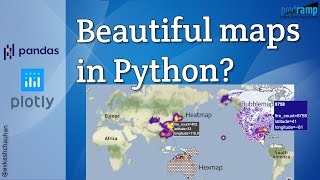
Impactful and Informative Geo Maps With Pandas and Plotly
Create impactful geo maps using Pandas and Plotly. Learn to visualize large datasets with bubble, heat, and hexagon maps. Hands-on tutorial covers data processing, Plotly integration, and map creation techniques.

Learn Data Science Full Course - 2020
Comprehensive introduction to data science, covering key concepts, tools, and methodologies. Ideal for beginners seeking to understand the field's fundamentals and career prospects.
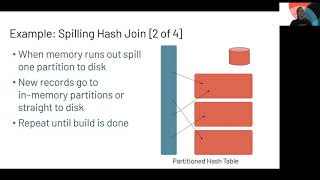
Photon: Accelerating SQL Queries on Databricks Lakehouse Platform
Explore Photon, a C++ component for efficient query execution in Databricks Lakehouse. Learn about its vectorized processing, compatibility with Apache Spark, and performance enhancements for data-driven decision-making.
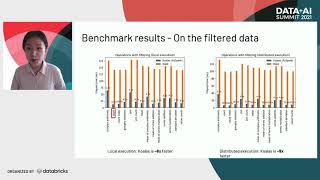
Koalas: Scaling Pandas APIs on Apache Spark - Performance and Comparison with Dask
Explore Koalas: pandas-like APIs for big data on Apache Spark. Compare performance with Dask, learn about recent updates, and understand its scalability for data science tasks.
Growing the Delta Ecosystem - Delta-RS for Rust and Python
Explore delta-rs, a Rust library extending Delta Lake beyond Spark. Learn its current capabilities, roadmap, and real-world application in kafka-delta-ingest for high-throughput data transfer.
Accelerating MLOps with Apache Spark and SingleStore
Learn to accelerate MLOps using Apache Spark and SingleStore. Discover how to build fast analytical applications, manage supervised learning models, and scale AI/ML operations for data science success.
Project Zen - Improving Apache Spark for Python Users
Discover improvements in Apache Spark for Python users, including redesigned documentation, type hints, PyPI distribution options, and enhanced PySpark features for a more Pythonic experience.
Encoding Multi-Layered Vega-Lite COVID-19 Geodata Visualizations with MLflow
Learn to create and manage multi-layered Vega-Lite visualizations for COVID-19 geodata using MLflow, enhancing data communication and lifecycle management for powerful insights.
Fugue: Unifying Big Data Analytics Ecosystems for ETL and Machine Learning
Unifying big data ecosystems with Fugue: SQL-like framework for ETL and ML pipelines, compatible with Spark, TensorFlow, and more. Simplifies development, improves performance, and enhances maintainability.
Dumb-Proofing Data Pipelines: Techniques for Configurable and Maintainable ETL - Databricks
Techniques to create configurable, maintainable data pipelines. Learn to externalize configurations, validate inputs, and leverage Scala features for robust, easily deployable ETL processes.
Fully Utilizing Spark for Data Validation with Fugue and Pandera
Explore lightweight data validation for Spark using Fugue and Pandera, enabling partition-specific rules and efficient big data processing without compromising on functionality.
Deep Dive into New Features of Apache Spark 3.1
Explore Apache Spark 3.1's new features: ANSI SQL compliance, streaming enhancements, Python improvements, and performance optimizations for faster, easier, and smarter data processing.
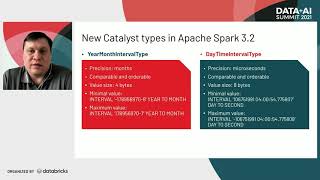
Comprehensive View on Intervals in Apache Spark 3.2
Explore Apache Spark 3.2's interval enhancements, including ANSI SQL conformance, new interval types, and improved APIs. Learn to construct, use, and manage intervals effectively in Spark SQL and PySpark.
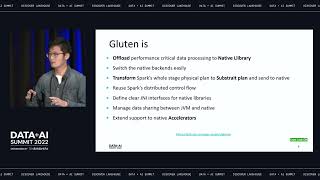
Gazelle-JNI: Offloading Spark SQL to Native Engines for Execution Acceleration
Explore Gazelle-Jni, a middle layer integrating native SQL engines with Spark SQL for accelerated execution through Substrait-transformed physical plan offloading.
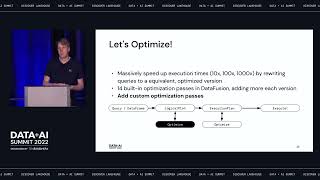
DataFusion and Apache Arrow: Supercharging Data Analytics with a Rust-Based Query Engine
Explore Rust, Apache Arrow, and DataFusion to accelerate modern data stacks. Learn implementation timelines, optimization techniques, and key features for efficient data analysis and querying.
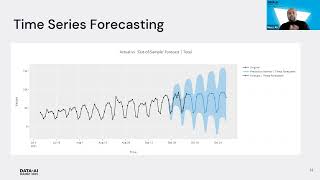
Time Series Forecasting with PyCaret
Explore automated time series forecasting with PyCaret's low-code module. Learn setup, EDA, training, and forecasting techniques to streamline your predictive modeling workflow.
Scaling XGBoost for Thousands of Features with Databricks
Scaling XGBoost for online advertising: Learn to handle thousands of features, optimize model training, and avoid common pitfalls in both Python and Scala implementations on Spark.