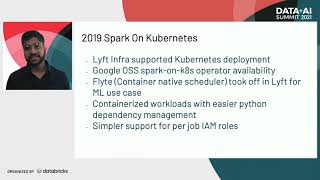
Hybrid Apache Spark Architecture: Optimizing YARN and Kubernetes for Lyft's Workloads
Explore Lyft's hybrid Apache Spark architecture using YARN and Kubernetes, addressing scalability challenges and optimizing workload management for improved reliability and efficiency.
Running Apache Spark on Kubernetes - Best Practices and Pitfalls
Learn best practices and pitfalls for running Apache Spark on Kubernetes, covering setup, performance optimization, resource management, security, and future developments in this comprehensive overview.
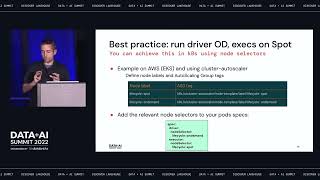
How to Make Apache Spark on Kubernetes Run Reliably on Spot Instances
Learn to run Apache Spark on Kubernetes using spot instances for cost savings. Discover best practices, code examples, and techniques to handle spot interruptions while maintaining reliability and performance.
Improving Apache Spark Application Processing Time - Configuration and Optimization Techniques
Optimize Spark streaming app performance through configurations, code improvements, and custom data source implementation for processing 700 MB/s of compressed data with strict KPIs.
Apache Spark on Kubernetes - Lessons Learned from Launching Millions of Spark Executors
Lessons learned from running massive Spark workloads on Kubernetes at Apple, covering orchestration, resource management, monitoring, and optimization for scalability and performance.
Deploying Apache Spark Jobs on Kubernetes with Helm and Spark Operator
Learn to deploy Scala Spark jobs on Kubernetes using Helm and Spark Operator. Live coding demo shows scalable, flexible deployments with minimal custom configurations for stress-free implementation.
Cloud-Native Apache Spark Scheduling with YuniKorn on Kubernetes
Explore cloud-native Apache Spark scheduling on Kubernetes using YuniKorn. Learn about efficient resource management, quota handling, and auto-scaling for large-scale Spark jobs in cloud environments.
Running Apache Spark Jobs Using Kubernetes
Learn to run Apache Spark jobs on Kubernetes, unifying analytics and data science on a cloud-native architecture. Discover how this approach simplifies infrastructure, enables on-demand deployment, and eliminates big data cluster overhead.
Introduction to Fluentd and Fluent Bit for Log Collection and Stream Processing
Explore Fluentd and Fluent Bit for efficient log collection and stream processing in Kubernetes. Learn deployment, configuration, and practical applications for enhanced observability.
Introduction to Kubeflow and Machine Learning on Kubernetes
Comprehensive introduction to Kubeflow 1.3, covering its new features and guiding users through running data science workloads on Kubernetes. Includes hands-on examples and practical deployment techniques.
Digital Onboarding Microservices Platform With KYC & Electronic Signature
Explore a multi-tenant microservices platform for digital onboarding, featuring KYC and e-signatures. Learn about dynamic API generation and mass-producing personalized workflows for financial services.
Apache Camel K - Build and Deploy on Kubernetes
Discover Apache Camel K's rapid development capabilities for Kubernetes, featuring custom operators, resources, and build image reuse for lightning-fast application deployment and updates.
Training and Ensuring Reliability of ML Models - The Power of ArgoCD, Flyte, and Argo Workflows
Explore Wolt's approach to reliable ML model training and deployment using ArgoCD, Flyte, and Argo Workflows. Learn strategies for scalability, consistency, and collaboration in ML operations.
Our Journey Through Cloud-Native as Mentee and Mentor
Explore mentorship in cloud-native communities through personal experiences. Learn how to start your journey as a mentee or mentor, overcome challenges, and advance in the field.
Rook - Introduction and Deep Dive with Ceph Storage
Comprehensive introduction to Rook, a cloud-native storage operator for Kubernetes. Explore how Rook integrates Ceph with Kubernetes to provide stable block, file system, and object storage for production data.
Building Apache Druid on Kubernetes - How Dailymotion Serves Partner Data
Explore Dailymotion's implementation of Apache Druid on Kubernetes for partner data management, covering architecture, challenges, and optimizations for scalability and performance.
Efficient Access to Shared GPU Resources: Mechanisms and Use Cases
Explore GPU scheduling in Kubernetes, including time sharing and Nvidia MIG, to optimize resource utilization for HEP and machine learning workloads. Benchmark results and management strategies included.
Kubernetes: The Cornerstone of Modern Data Engineering
Explore Kubernetes' impact on data engineering, focusing on open-source tools, scalability, and efficiency. Learn how it's shaping the future of data processing and management.
Monitoring Fluent Bit in Production - Metrics and Best Practices
Explore strategies for monitoring Fluent Bit in production, including key metrics, storage considerations, and detecting pipeline health issues. Learn from real-world experiences and gain practical insights for optimizing your logging infrastructure.
Kubernetes and AI in Cancer Diagnosis and Treatment
Explore how distributed Kubernetes clusters and AI revolutionize cancer diagnosis, combining computational biology with cloud computing for faster, more precise treatments.
Managing Multi-Cloud Apache Spark on Kubernetes
Learn strategies for managing Apache Spark on Kubernetes across multiple clouds, focusing on auto-scaling, scheduling, and observability techniques for efficient data science infrastructure.