Navigating Microsoft Fabric - Choosing the Right Workload for Your Needs
Choose the right Microsoft Fabric workload for your business needs and understand current limitations in this informative session led by experienced Microsoft program managers.
Microsoft Fabric Adoption: Measuring Success with KPIs - What Gets Measured, Gets Done
Implement specific measures and KPIs to track Microsoft Fabric and Power BI adoption, enhancing data-driven decision making and organizational performance.
Microsoft Purview Universe - More than Just a Data Catalogue
Explore Microsoft Purview's comprehensive suite, understanding its components and their synergy for effective data management and governance.
New Features in Power Query for Power BI, Fabric, and Excel
Discover the latest Power Query features in Power BI Desktop, Fabric Dataflows, and Excel, enhancing data transformation capabilities.
Data Quality Revolution: The Fabric-OpenAI Approach
Master data cleaning techniques using Fabric and OpenAI to transform chaotic datasets into valuable insights, enhancing your data quality skills for improved analysis and decision-making.
Getting to Know Podman, Podman Desktop and Friends
Explore Podman's daemonless container engine, its advantages over Docker, and related tools for efficient container management and deployment.
Serverless Computing: Benefits, Drawbacks, and Application Development
Explore serverless computing benefits, drawbacks, and application building. Learn about cost reduction, scalability, faster development, and real-world deployment challenges.
Simplifying Containers and Kubernetes on Your Laptop with Podman Desktop
Explore Podman Desktop for simplified container and Kubernetes management on your local machine, featuring multiple containers and local Kubernetes capabilities.
Decoupling with Event-Driven Architecture: Implementing Data Mesh Using Galapagos
Explore event-driven architecture with Galapagos, an open-source tool for Apache Kafka. Learn how to decouple teams, improve data management, and enhance business communication through event-driven thinking.
Building a Winning Data Engineering Culture
Learn to build a successful data engineering team and culture, empowering engineers and partners for efficient data systems and fruitful projects. Explore critical roles and strategies for data-driven decision-making success.
Approaching Kafka Replication at Scale - Go Big or Go Home
Explore scaling strategies for Kafka, including horizontal and vertical scaling, replication techniques, and routing events between clusters. Learn to overcome bottlenecks and manage large-scale data processing effectively.
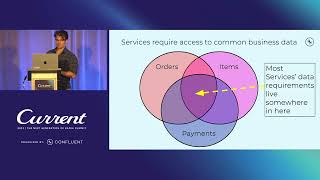
Off-Label Data Mesh - A Prescription for Healthier Data
Explore data mesh application beyond analytics, using event streams for real-time and batch operations. Learn practical guidelines, overcome hurdles, and implement a minimally viable data mesh for improved data management.
Configuring Kafka Connect for Scalability - Best Practices
Optimize Kafka Connect clusters for scalability. Learn best practices to configure and manage Kafka Connect effectively, ensuring successful integration of external systems with Apache Kafka at scale.
Beyond Monoliths: Thrivent's Lessons in Building a Modern Integration Architecture
Explore strategies for modernizing data architecture, from technical aspects like JSON Schema and OpenTelemetry to human factors like building trust and adopting a product-focused mindset.
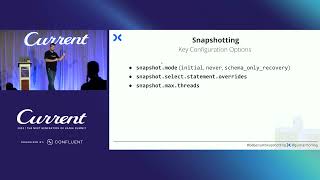
Debezium Snapshots Revisited - Incremental Snapshots for CDC Pipelines
Explore innovative incremental snapshot techniques for Debezium CDC connectors. Learn to pause, resume, and parallelize snapshots, and customize snapshot contents for efficient data pipeline management.
Dynamic Change Data Capture with Flink CDC and Consistent Hashing
Implement dynamic Change Data Capture for large databases using Flink CDC connectors and consistent hashing. Overcome challenges with incremental snapshotting and Postgres replication slots.
Analytics: The Final Data Frontier - Why Users Need Your Data and How Pinot Serves It
Explore Apache Pinot's real-time analytics capabilities for user-facing applications, leveraging streaming data from Apache Kafka to deliver rapid insights across diverse business domains.
10 Tips to Enable Data Discovery and Governance in Your Organization
Discover 10 essential tips for enhancing data discovery and governance in your organization, from establishing a common data language to implementing data contracts and fostering collaboration.
Implementando el Patrón CQRS con Debezium, PostgreSQL, Redis y Kafka
Aprende a implementar el patrón CQRS utilizando Debezium, PostgreSQL, Redis y Kafka para mejorar el rendimiento y la escalabilidad de tus aplicaciones Java con Spring Boot.

Tutorial DuckDB: La Base de Datos Rápida y Ligera para Analítica, ETL, Scripting y Microservicios
Explora DuckDB, una base de datos veloz y liviana para análisis, ETL, scripting y microservicios. Aprende sus ventajas y aplicaciones prácticas.
Rapidly Deploy NFV with VyOS on Kubernetes
Deploy NFV rapidly using VyOS on Kubernetes for flexible, scalable virtual network routing and advanced networking features.