Subsets and Supermajorities - Optimal Hashing-based Set Similarity Search
Explore optimal hashing techniques for efficient set similarity search, focusing on subsets and supermajorities in data structures and algorithms.
Advanced RAG Techniques - RAG Fusion Implementation - Lecture 6
Explore RAG fusion technique to enhance retrieval-augmented generation models, combining multiple search queries and ranking results using reciprocal rank fusion with LangChain implementation.
GPT-4 Turbo Documentation Converter to JSON Format
Convert documentation into easily chunkable JSON format using GPT-4 Turbo, enhancing retrieval accuracy. Explore basic to advanced implementations and iteratively improve generated documentation for better searchability.

End-to-End LLM Project: Langchain with Pinecone Vector Database
Learn to build an end-to-end LLM project using Langchain and Pinecone vector database. Covers data processing, vector creation, database operations, and similarity search implementation.
Accessible Neural Search and Cloud-Nativeness for ML Engineers
Explore neural search for cross-modal data, learn Jina's architecture for building cloud-native AI applications, and understand essential technologies for production-ready systems.
LLM News: ESM3, CriticGPT, Gemma 2, LLM Compiler, LongRAG, and GraphReader
Explore latest AI advancements: ESM3, CriticGPT, Gemma 2, LLM Compiler, LongRAG, GraphReader. Gain insights on cutting-edge language models, tools, and techniques shaping the future of artificial intelligence.
Semantic Search: Revolutionizing Information Retrieval - Nils Reimers
Explore semantic search's power to enhance retrieval accuracy using pre-trained transformer networks. Learn how it overcomes lexical limitations and improves multilingual search efficiency across 100+ languages.
Near Real-Time Logging Solution Using Fluent Bit and OpenSearch for Kubernetes
Explore a near real-time logging solution for Kubernetes using Fluent Bit and OpenSearch. Learn about architecture, implementation challenges, and ensuring data privacy in multi-node clusters.
The Power of AI in Search - Transforming Digital Interactions
Richard Socher discusses AI's impact on search engines, exploring You.com's innovative approach, security measures, ethical considerations, and the future of AI in transforming digital interactions and work.
Vector Embeddings for Semantic Search Made Easy with Practical Tips
Explore vector embeddings for semantic search, learning techniques to create meaningful representations, efficient similarity search algorithms, and practical strategies for enhanced information retrieval.
LangChain Multi-Query Retriever for RAG - Advanced Technique for Broader Vector Space Search
Learn advanced RAG techniques using LangChain's Multi-Query Retriever. Explore how to broaden search results, customize queries, and integrate this method into larger RAG pipelines for improved AI applications.

Getting Started with Retrieval Augmented Generation (RAG) in Java and Spring AI
Learn to implement Retrieval Augmented Generation (RAG) using Java and Spring AI. Explore RAG's applications, setup process, and practical implementation with a simple example.
Advanced RAG: Chunking, Embeddings, and Vector Databases
Explore advanced RAG concepts: chunking for efficient retrieval, embeddings for text representation, and vector databases for optimized storage and retrieval in LLM applications.
Langchain: Conversational QA Tool with Gemini, Langchain, and Faiss
Crea un chatbot de preguntas y respuestas conversacional utilizando Langchain, Gemini Pro 1.5, Faiss y Vertex AI para consultar una base de conocimientos personalizada.
LLMOps with Langchain, OpenAI, and Faiss on Databricks - Creating a Retrieval QA Tool
Develop a Retrieval QA tool using Langchain, OpenAI, and Faiss. Learn to save components in Databricks' MLFLOW, work with Model Governance, and perform inference after chain retrieval.
Data Extraction with LangChain and OpenAI for Machine Learning and Data Science
Extraer información de fuentes no estructuradas utilizando LangChain y OpenAI para aprendizaje automático y ciencia de datos.
Llama 2, Ollama and Pinecone - Vector Database Search for Machine Learning and Data Science
Explore embedding and searching text using Llama 2, Ollama, and Pinecone Vector Database for efficient information retrieval in machine learning projects.
NVIDIA NIM Integration with Langchain for RAG Q&A
Explore NVIDIA NIM integration with Langchain, creating a RAG Q&A system using Faiss for enhanced machine learning and data science applications.
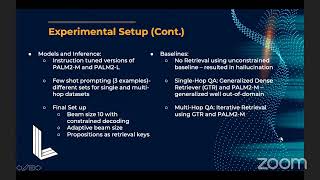
From RAG to RICHES - Retrieval Interlaced with Sequence Generation
Innovative AI approach integrating retrieval into sequence generation, simplifying RAG systems. Adapts to new tasks through prompting, supports multi-hop retrievals, and excels in Open Domain Question Answering.
Vector Search at Uber - Implementing and Scaling KNN Search with Apache Lucene
Explore Uber's implementation of Vector Search using Apache Lucene, enabling semantic search and Gen AI support. Learn about HNSW algorithm integration, live vector updates, and scalability optimizations.
Navigating Challenges and Enhancing Performance of LLM-based Applications
Explore strategies for optimizing Retrieval-Augmented Generation applications, addressing challenges in evaluation and performance enhancement for improved accuracy and contextual depth in AI-generated responses.