Personalized Recommendations and Search with Retrieval and Ranking at Scale - Hopsworks Workshop
Implement personalized recommendations using retrieval and ranking architecture with two-tower embedding models. Learn offline and online infrastructure for scalable, low-latency systems on Hopsworks platform.
Traditional Methods for Similarity Search - Jaccard, W-Shingling, Levenshtein
Explore three traditional similarity search methods: Jaccard Similarity, w-shingling, and Levenshtein distance. Learn their applications in language comparison and document matching for effective search engines.
IndexLSH for Fast Similarity Search in Faiss
Explore fast similarity search using IndexLSH in Faiss. Learn efficient implementation techniques for large-scale data retrieval and comparison in AI applications.
Choosing Indexes for Similarity Search - Faiss in Python
Explore Faiss indexes for efficient similarity search, comparing Flat, LSH, HNSW, and IVF to optimize performance in large-scale datasets. Learn to choose and implement the best index for your needs.
FAISS - Introduction to Similarity Search
Explore efficient similarity search with Facebook AI Similarity Search (FAISS). Learn implementation, options, and how FAISS enhances semantic search speed.
Natural Language Processing with Qdrant for Vector Similarity Search
Master vector similarity search using Qdrant to create embeddings from text data, perform contextual searches, and build recommendation systems for enhanced natural language processing applications.
Getting Started with Qdrant - Introduction to Vector Database and Similarity Search
Master vector similarity search using Qdrant to build semantic search and recommendation systems through hands-on practice with sample datasets and practical implementations.
Qdrant Vector Database and Search Engine Implementation in Rust
Dive into vector database technology with Qdrant, exploring its architecture, implementation in Rust, and applications in similarity search, matching, and recommendations systems.
Embeddings and Similarity Search with Qdrant Vector Database
Explore vector embeddings and similarity search concepts through hands-on demonstrations using Qdrant database, with practical examples for implementing efficient search solutions.
Enhancing Apache Cassandra Drivers with Vector Support
Explore vector support integration in Python, Java, and NodeJS drivers for Apache Cassandra, enabling similarity search and AI applications. Gain insights into technical challenges and future implications.
GPT-4 Codes Near Perfect Langchain Code Using Vector DB from Documentation
Learn to crawl documentation, extract code, create datasets, and generate Langchain applications using GPT-4. Explore advanced techniques for embedding, similarity search, and AI-powered code generation from simple descriptions.
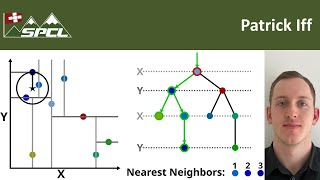
Finding Relevant Items Using Approximate Nearest Neighbor Search Algorithms
Explore algorithms for nearest neighbor search, from KD-Trees to modern approaches like HNSW and IVF-PQ, understanding their applications and performance tradeoffs.
Gemini and GPT Sales Agents with RAG - Comparison and Implementation
Explore Gemini and GPT capabilities for building AI sales agents with retrieval-augmented generation, including code demonstrations and practical comparisons.
Locality Sensitive Hashing for Search with Shingling + MinHashing - Python
Learn efficient similarity search using Locality Sensitive Hashing (LSH) with shingling and MinHashing techniques in Python. Explore implementation steps, from data preprocessing to LSH tuning, for approximate nearest neighbor search.
QA Chat with a Website - OpenAI Embeddings Tutorial: Use GPT-3 API and OpenAI ADA-2 Embeddings
Learn to create a QA chatbot using OpenAI embeddings and GPT-3 API. Convert website content for similarity search, set up the environment, and implement the system step-by-step.
Search with Vectors - Simon Hughes
Explore vector-based search techniques and their applications in modern information retrieval systems for improved accuracy and efficiency.

End-to-End LLM Project: Langchain with Pinecone Vector Database
Learn to build an end-to-end LLM project using Langchain and Pinecone vector database. Covers data processing, vector creation, database operations, and similarity search implementation.
Vector Embeddings for Semantic Search Made Easy with Practical Tips
Explore vector embeddings for semantic search, learning techniques to create meaningful representations, efficient similarity search algorithms, and practical strategies for enhanced information retrieval.
Hugging Face Datasets - Dataset Builder Scripts for Beginners
Learn to create and manage dataset builder scripts for Hugging Face, including download management, Apache Arrow datatypes, and integration with popular machine learning frameworks for efficient model training and fine-tuning.
Similarity Search - Taking Your Search Engine to the Next Level
Dive into advanced similarity search techniques and AWS services for enhancing search engine capabilities, understanding observability, monitoring, and telemetry implementation.
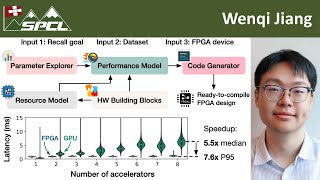
Co-design Hardware and Algorithm for Vector Search
Explore hardware-algorithm co-design for efficient vector search on FPGAs, enhancing performance in large-scale information retrieval and machine learning systems.