How to Design Database-as-a-Service (DBaaS) - Cloud Native Approach
Explore the design principles and best practices for creating a robust Database-as-a-Service solution in cloud-native environments, enhancing scalability and efficiency.
Azure Cosmos DB - Low Latency and High Availability at Planet Scale
Explore Azure Cosmos DB's architecture, focusing on high availability, low latency, and scalability. Learn about storage engine design, request routing, and performance optimization for planet-scale services.
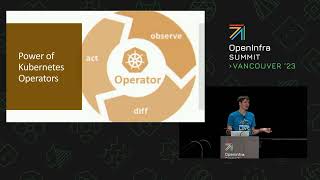
Best Practices for Running Open Source Databases on Kubernetes
Master essential strategies for deploying and managing open-source databases on Kubernetes, covering high availability, security, backups, and disaster recovery using Percona Operators for MySQL, MongoDB, and PostgreSQL.
Under Pressure: Applying Machine Learning in Real-Time Systems
Explore real-time machine learning implementation strategies, from handling low latency requirements to building scalable systems for streaming scenarios in autonomous vehicles, healthcare, and fraud detection.
Kubernetes Everywhere: Lessons Learned From Going Multi-Cloud
Insights on deploying Kubernetes across multiple cloud providers, exploring networking differences, scaling challenges, and successful strategies for multi-cloud infrastructure management.
Transparent Live Migration of Services Between Kubernetes Clusters
Explore techniques for seamlessly migrating distributed databases between Kubernetes clusters across cloud providers, addressing challenges in networking, DNS, and data persistence.
Kubernetes 101 - Running Application Containers and Scaling Deployments
Comprehensive Kubernetes workshop covering pods, manifests, controllers, scaling, deployment, and observability. Includes hands-on labs for practical application and explores metrics management with Prometheus.
Site Reliability Engineering with Kubernetes - Designing for 99.99% Uptime
Learn best practices for achieving 99.99% service uptime using Kubernetes, focusing on reliability in production environments and design strategies.
Cloud Native Live - Kubernetes-Native Pipelines for Stateful Applications
Explore Kubernetes-native pipelines for stateful applications, enhancing cloud-native development and deployment strategies for robust, scalable solutions.
Thriving With Kubernetes On-Call - Best Practices and Lessons Learned
Panel discussion on best practices for managing Kubernetes on-call rotations, covering strategies for engineer satisfaction, alert management, proactive issue handling, and on-call preparation at large tech companies.
Unleashing the Power of GitHub Actions for Platform Engineering
Explore GitHub Actions for platform engineering, learn to abstract complex IaC, and simplify deployment management for developers. Discover existing actions or build custom solutions.
Architecting for Resilience: Strategies for Fault-Tolerant Systems - DevOps 2024
Explore strategies for building fault-tolerant systems, covering failure types, design requirements, architecture, and redundancy in DevOps environments.
What Exactly Is High Availability? Failover and High Availability Demonstration
Comprehensive demonstration of high availability principles, failover models, and practical implementation using keepalived, focusing on maximizing uptime and accessibility for websites and applications.
High Availability with BGP - Metal Monday
Explore high availability using BGP on Equinix Metal. Learn about bare metal challenges, BGP basics, and configure nginx, haproxy, and bird for robust load balancing and routing.
Introduction to Kube-VIP - Bare Metal Load Balancing for Kubernetes
Explore kube-vip for bare metal Kubernetes load balancing. Learn about Plunder for server provisioning and see practical demos of control plane HA and service load balancing.
High Availability with Docker and Java EE
Explore containerization for Java projects, covering technology, pitfalls, and practical implementation. Learn to deploy and run your own containers for improved delivery.
Make Stateful Applications Highly Available with Docker Swarm Mode and Docker Plugins
Learn to containerize and persist data for any application using Docker Swarm Mode. Explore storage solutions, high-availability, and automated recovery for stateful applications in this comprehensive overview.
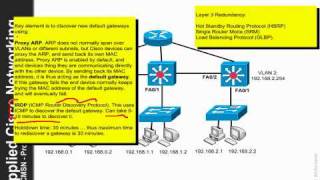
Cisco Switching: High Availability and Redundancy - Part 1
Learn about Cisco switching availability, including redundancy, HSRP, VRRP, and gateway discovery. Enhance network reliability and performance with expert insights.
Proxmox VE - How to Setup High Availability
Learn to set up high availability in Proxmox VE to minimize downtime. Covers HA groups, VM configuration, shutdown policies, and resource scheduling for efficient cluster management.
The Ins and Outs of the Cloud Provider in Kubernetes
Explore Kubernetes' cloud provider framework, external cloud providers, and cloud controller manager. Learn implementation, responsibilities, and migration strategies for zero-downtime clusters.
The Day We Deleted Production - Kubernetes Infrastructure Recovery at CERN
Explore CERN's Kubernetes infrastructure resilience: Learn how a major incident was managed with minimal impact, and discover strategies for high availability and rapid recovery in critical environments.