Setting up Etcd with Kubernetes to Host Large-Scale Clusters - Best Practices
Learn best practices for deploying etcd in large-scale Kubernetes clusters, focusing on performance, reliability, and scalability for thousands of nodes. Insights from Datadog and Google Cloud experts.
The Power of Self-Managing Clusters in Kubernetes
Explore self-managing Kubernetes clusters: streamline management, enhance scalability, and overcome challenges in multi-tenant cloud environments. Learn from VMware's successful implementation.
Recovering from Regional Failures at Cloud Native Speeds
Explore k8gb, an open-source global load balancing solution for Kubernetes, enabling efficient recovery from regional failures and improving app reliability across dispersed clusters.
Cortex - Running a Rock Solid Multi-Tenant Prometheus
Explore resilience strategies for Cortex, a scalable multi-tenant storage solution for Prometheus. Learn about hash-ring replication, zone-aware replication, tenant limits, instance limits, and shuffle sharding.
Multi-AZ Multi-Cluster Management - Session 8
Explore advanced strategies for managing multi-zone and multi-cluster Kubernetes environments, focusing on scalability, resilience, and efficient resource allocation across distributed infrastructures.
Migrating From Single-Node Kubernetes Control Plane to HA in Production
Learn how Databricks migrated from single-node to multi-node Kubernetes control planes, enhancing reliability and enabling safer, faster upgrades across their cluster fleet without disrupting production workloads.
Multi-Cluster StatefulSet Migration: A Solution to Upgrade Pain
Explore solutions for seamless migration of stateful workloads across Kubernetes clusters, focusing on operational challenges, data protection, and the StatefulSet Partition enhancement for simplified maintenance.
Spreading Apps, Controlling Traffic and Optimizing Costs in Kubernetes
Explore strategies for high availability, traffic management, and cost optimization in Kubernetes using pod anti-affinity, Istio, and Karpenter to overcome challenges in app distribution and resource scaling.
SIG Scheduling Deep Dive in Kubernetes - Latest Enhancements and Opportunities
Explore recent enhancements in Kubernetes SIG Scheduling, including improved scheduler performance, better support for rolling updates, and new features like SchedulingGates for external integrators.
Simplifying Multi-cluster Kubernetes Management with Karmada
Explore Karmada, a CNCF project simplifying multi-cluster Kubernetes management. Learn about its API, scheduling capabilities, and solutions for common challenges in hybrid and multi-cloud environments.
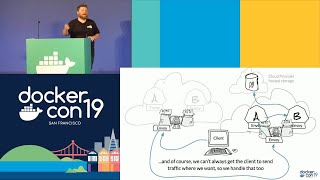
Practical Istio Use Cases and Demonstrations
Explore real-world Istio implementations for high availability, secure communication, and traffic management in microservices architectures through concrete use cases and live demos.
Spreading Apps, Controlling Traffic and Managing Costs in Kubernetes
Explore strategies for high availability, traffic management, and cost optimization in Kubernetes. Learn about pod anti-affinity, locality-aware load balancing, and workload consolidation for efficient cluster scaling.
High Availability Containers with Virtual IP
Explore implementing high availability for containers using Virtual IP across multiple hosts, with configuration insights for containers and keepalived in microservices architectures.
Cluster API – Yesterday, Today, Tomorrow
Explore Cluster API for Kubernetes lifecycle management, comparing alternatives and discussing its role in infrastructure provisioning and potential for higher-level orchestration.
How to Migrate Databases into Kubernetes
Learn to deploy and migrate databases to Kubernetes, implement automatic failover, and build database-as-a-service. Gain insights on production-ready setups and self-service storage provisioning for stateful workloads.

Zero-Touch Fault-Tolerance for Cloud-Native Geo-Distributed Databases
Explore zero-touch fault-tolerance for cloud-native geo-distributed databases using multi-cluster orchestration and YugabyteDB's synchronized replication for automatic failure handling and high availability.
Two-Node High Availability for Edge Kubernetes - A New Approach
Explore a novel approach to 2-node high availability for edge Kubernetes, enhancing resilience and efficiency in cloud-native deployments at the network edge.
Fields Tested: Running a Game Server with Kubernetes and Agones
Explore game server management using Kubernetes and Agones, focusing on scalability, deployment, and efficient resource allocation for multiplayer gaming infrastructure.
Effective Disaster Recovery Strategies for Kubernetes
Explore Kubernetes disaster recovery strategies, including fault tolerance, high availability, and backup/restore components for mission-critical cloud-native applications with near 100% uptime requirements.
MicroK8s HA Under the Hood - Kubernetes with Dqlite
Explore MicroK8s' high availability design using distributed SQLite for production Kubernetes, offering zero-ops experience and seamless functionality in cloud and server deployments.
Highly Scalable SaaS Apps on Kubernetes - Real Life Case Studies
Explore real-life case studies on building global, cloud-native SaaS applications using Kubernetes. Learn strategies for scaling, high availability, monitoring, tracing, and security in DevOps environments.