Analyzing Configuration of Cellular Networks at Nokia with Apache Hadoop, Apache Spark, and Presto SQL
Explore big data solutions for cellular network configuration analysis using Apache Hadoop, Presto SQL, and related technologies. Learn about challenges, pitfalls, and optimizations in building a massively parallel processing system.
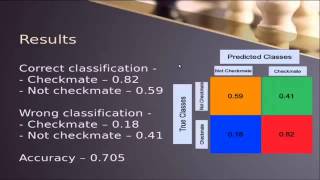
Learning Chess from Data
Discover chess rules and gain insights through Machine Learning and Hadoop analysis of game data. Explore feature importance, representation, and sample size for understanding complex systems.
Integrating SQL Server Analysis Services with Hadoop
Explore the integration of SQL Server Analysis Services with Hadoop, focusing on leveraging big data for enhanced business intelligence and analytics capabilities.
Hadoop Essentials for the SQL Server Professional
Learn Hadoop essentials, including HDFS, MapReduce, and Hive, with a focus on comparisons to SQL Server. Explore on-premises and cloud options for implementing Hadoop ecosystems.
The Role of Polybase in the Modern Data Warehouse
Explore PolyBase's role in modern data warehousing: streamline ETL, export dimensions, use Hadoop for archiving, and enrich relational data with ambient data from Hadoop.
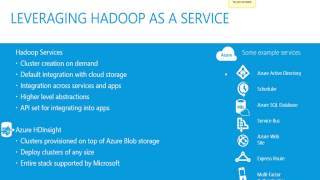
Extending Your Hadoop Implementations to the Cloud
Explore cloud-based Hadoop deployment benefits, including scalability and cost-efficiency. Learn to integrate on-premise and cloud implementations for optimal performance and flexibility.
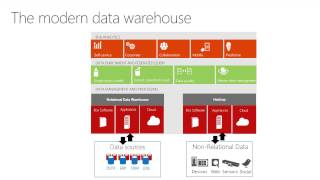
The Modern Data Warehouse
Explore Microsoft's approach to evolving data warehouse infrastructure, addressing explosive data growth and new data types. Learn about scale-out technologies, in-memory performance, and Hadoop integration.
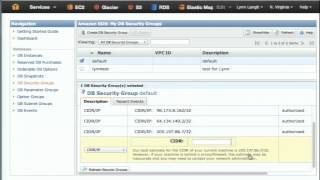
Using Amazon's Cloud for the SQL Server Professional
Explore Amazon Web Services for SQL Server pros: EC2, S3, RDS, NoSQL, and more. Learn to leverage cloud storage, virtual machines, and PaaS solutions for efficient data management and processing.
Relational Databases vs Non Relational Databases vs Hadoop
Explore the differences between relational, non-relational databases, and Hadoop, covering origins, key features, use cases, and Microsoft's data platform solutions.
Big Data Architectures and The Data Lake - Cloud
Explore big data architectures, data lakes, and modern data warehousing. Learn about Hadoop, cloud benefits, and strategies to effectively manage and analyze large-scale data for business intelligence.
The ABCs of BDCs - Big Data Clusters for Beginners
Explore SQL Server 2019's Big Data Clusters: architecture, deployment, and capabilities for combining relational and non-relational data, enhancing your big data skills and career prospects.
Elephant on Wheels - Petabyte-scale AI @ LinkedIn
Explore LinkedIn's journey in integrating Kubernetes for AI workloads, focusing on secure HDFS access and innovative scheduling solutions for petabyte-scale operations.
Lesson Learned on Running Hadoop on Kubernetes
Explore LinkedIn's journey in deploying Hadoop on Kubernetes, reducing infrastructure setup time and enabling rapid feature testing for their massive data environment.
Peanut Butter and Chocolate - Integrating Hadoop with SQL Server
Learn to bridge SQL Server and Hadoop using tools like SSIS, Sqoop, and PolyBase. Discover seamless data migration and integration techniques for database and app developers.
A Case Study in API Cost of Running Analytics in the Cloud at Scale with an Open-Source Data Stack
Explore cloud analytics cost optimization through Uber's case study, examining I/O strategies and performance-cost trade-offs in cloud-native environments versus traditional HDFS deployments.
Data Mesh for Instant Query - Why Trino on Data Mesh
Discover how modern data platforms are evolving from producer-centric to consumer-centric approaches, exploring Trino's role in data mesh architecture for efficient cross-platform data analysis and instant querying.
The Implementation of DataOps in Unicom Digital Division: Building Integrated Data Capabilities
Explore Unicom's DataOps implementation using Apache DolphinScheduler, including challenges and solutions for large-scale Hadoop task scheduling.
Dataproc Persistent History Server: Up and Running
Learn to access and troubleshoot Hadoop and Spark application logs using Persistent History Server for ephemeral clusters and Dataproc Serverless, enhancing job monitoring and exploration capabilities.
Data Caching for Enterprise-Grade Petabyte-Scale OLAP
Explores Alluxio local cache for petabyte-scale OLAP, optimizing data transfer efficiency in decoupled compute-storage models. Shares insights from Uber and Meta deployments.
Apache Spark Processing with AWS EMR - Data Engineering Project
Master AWS EMR for data processing: set up, submit Spark jobs, visualize on Hadoop UI, and leverage cloud computing for efficient big data handling.

How to Use Google Cloud Storage to Unify Data for Analytics Workloads
Unify data analytics workloads with Google Cloud Storage. Learn to scale, achieve consistency, and reduce costs while integrating with BigQuery, Hadoop, Spark, and Kafka.