Data Engineering Full Hands-on Course
Comprehensive hands-on introduction to data engineering, covering data lake architecture, Cloudera tools, Apache Sqoop, and practical HDFS and MySQL operations.
Hadoop, Machine & Deep Learning on Azure Cloud - Tutorial Series
Comprehensive hands-on tutorial series covering Azure cloud services, Hadoop, Spark, and machine learning, with practical demos and step-by-step guidance for various Azure tools and technologies.
Sber.DS Codeless Platform for AI/ML Developers
Визуальная платформа для разработки и валидации AI/ML моделей с поддержкой мульти-облачных сред, микросервисной архитектурой и широкими возможностями интеграции и расширения.
Best Practice for Cloud Native Storage in Finance Industry
金融行业云原生存储最佳实践:探讨浦发银行大数据平台的存储解决方案,包括本地卷、NAS、Longhorn和Piraeus等,分享性能评估和运营经验,介绍CSI-NFS-Export项目。
Data Engineering and Data Science Platform Based on Hadoop/Spark
Hadoop/Sparkを中心とした大規模データ活用基盤の構築と運用。SQL-on-Hadoop、Spark、Pythonを用いたデータエンジニアリングとデータサイエンスの実践的アプローチを紹介。
Xiaomi HDFS Data Governance Practices and Evolution
Explore Xiaomi's HDFS data governance practices, focusing on hot and cold data tiered storage solutions. Learn about cold data analysis, S3 integration, and future plans for optimizing data management.
Bytedance Cloud-Native YARN Practice: Serverless YARN for Efficient Resource Management
Explore ByteDance's Serverless YARN solution for efficient cloud-native big data processing, improving resource utilization and enabling seamless migration of Hadoop ecosystem jobs.
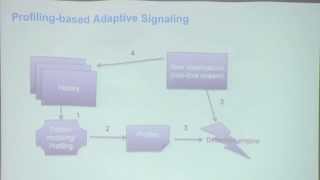
Devil in the Haystack - Application Security Through Statistical Analysis and Machine Learning
Exploring statistical and machine learning techniques for in-app security at Salesforce. Focuses on adaptive, data-driven approaches for detecting and preventing attacks and abuses on the platform.
Unlocking Scalable and Efficient Data Storage with Apache Ozone
Discover how Apache Ozone revolutionizes distributed object storage, offering scalable solutions for managing massive data volumes while ensuring reliability, cost-effectiveness, and seamless integration with Hadoop ecosystem.
Usama Fayyad at ODSC Boston 2015 - From Big Data to Data Science
Explore the evolution from Big Data to Data Science with Usama Fayyad, focusing on predictive analytics in a changing data landscape and its impact on business growth and competitive advantage.
Master Databricks and Apache Spark - Introduction
Learn the fundamentals of Databricks and Apache Spark, exploring scale-up vs. scale-out concepts and laying the groundwork for mastering these powerful data processing tools.
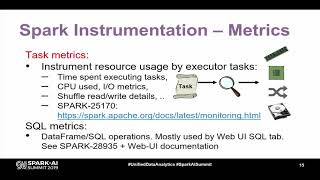
Performance Troubleshooting Using Apache Spark Metrics - Databricks Talk
Explore Apache Spark metrics for performance troubleshooting in distributed data processing. Learn to deploy dashboards, use sparkMeasure, and leverage Spark 3.0 improvements for optimizing workloads.
Migrating Pinterest Apache Spark Clusters from HDFS to S3
Explore Pinterest's migration of Apache Spark clusters from HDFS to S3, addressing technical challenges, optimizing performance, and achieving a smooth transition process.

Hadoop and Big Data with Java
Explore Hadoop and Big Data concepts in this NightHacking presentation, focusing on their integration with Java for efficient data processing and analysis.
Big Data Processing on Small Computers
Explore distributed computing, MapReduce, and parallel programming techniques for handling big data on small-scale systems with expert insights.
Big Problems with Big Data - Hadoop Interfaces Security
Explore Hadoop interfaces security challenges and solutions in big data environments, focusing on potential vulnerabilities and best practices for robust protection.
Embracing Big Data Workloads in Cloud-Native Environments with Data Locality
Explore data locality in cloud-native big data workloads, focusing on Apache Hadoop Ozone's network topology support and its benefits for performance and scheduling in Kubernetes environments.
Spark Over a Mesos Secured Productive Environment
Explore advanced Spark and Mesos integration for secure, isolated Big Data environments. Learn to enhance protection, manage secrets, and implement network solutions in enterprise-level deployments.
Hadoop Safari: Hunting for Vulnerabilities
Explore Hadoop security vulnerabilities, attack vectors, and tools for accessing data in Big Data clusters. Learn about design flaws and practical techniques to exploit weaknesses in Hadoop infrastructure.
Building Robust Streaming Data Pipelines with Apache Spark
Learn to build robust streaming data pipelines using Apache Spark, Kafka, and Camel. Explore ETL challenges, data management, and lessons from running these technologies in Docker.
Data Storage Systems - Taking a Look at Redshift, MySQL, PostgreSQL, Hadoop and Others
Explore key data storage systems like Redshift, MySQL, PostgreSQL, and Hadoop. Learn their features, pros, cons, and ideal use cases to make informed decisions for your data infrastructure needs.