Containerizing and Orchestrating Hadoop Infrastructure at Scale
Explore Uber's journey in containerizing Hadoop infrastructure, addressing technical challenges, designing zero-downtime migration, and transforming team culture for efficient large-scale operations.
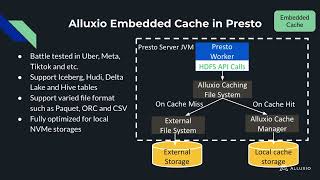
Caching Framework for Exabyte-Scale Data Lakes
Optimize exabyte-scale data lakes with open-source caching framework. Improve performance, reduce costs, and tackle challenges in complex data environments using Hadoop, Parquet, Hudi, and Alluxio.
Optimizing HDFS Performance: Balanced Utilization of Hardware Accelerators and ARM64 Multi-Implementation - Transparent Encryption
Optimize HDFS Transparent Encryption performance by balancing CPU cores and hardware accelerators. Learn to leverage OpenSSL 3.0 for dynamic resource allocation and improved efficiency in cloud services.
ByteDance's 100 Billion File HDFS Clustering Practice
Explore ByteDance's HDFS clustering practices for 100 billion files. Learn about storage scheduling, multi-region computing, and data management techniques for large-scale big data applications.
Apache HBase on Ozone - Data Storage and Computing
Discover how Apache HBase integrates with Ozone for enhanced distributed storage capabilities, exploring architecture, deployment strategies, and performance optimization techniques.
No Data Silos with Azure Blob Storage
Explore Azure Blob Storage's capabilities for unified data lakes, multi-protocol support, and secure scaling solutions to effectively manage and store data from various sources in the cloud.
The Evolution and Innovation of CubeFS
Explore CubeFS, a cloud-native distributed storage solution for big data, machine learning, and data sharing. Learn about its protocols, redundancy strategies, and hybrid-cloud acceleration features.
Opening Doors Through Open Source - Benefits and Insights from LinkedIn
Discover the hidden benefits of open source for engineers and organizations, from improved code quality to enhanced company culture and reputation.
Open Source Matters - The Journey of NTT DATA
Explore NTT DATA's journey in open source contributions, from PostgreSQL to Hadoop, and learn about their future focus on confidential computing and Kubernetes operators.
Scale R to Big Data with Hadoop & Spark
Learn to scale R for big data using Hadoop and Spark. Set up a Spark cluster, wrangle HDFS data, and build/deploy machine learning models using Microsoft R Server and distributed processing libraries.
Machine Learning at Scale with MLflow and Apache Spark
Explore Société Générale's journey in scaling machine learning, focusing on MLflow and Apache Spark for production deployment, CI/CD pipelines, and overcoming challenges in large-scale ML implementation.
MLflow at Company Scale - Scaling and Optimizing for High-Volume Machine Learning
Learn how Criteo scaled MLflow to handle massive data volumes, including horizontal scaling, monitoring, SSO integration, and hadoop cluster integration for data scientists.
Migrating Hybrid Big Data Platforms at Scale to Kubernetes
Explore challenges and solutions for migrating legacy big data workloads to Kubernetes, focusing on resource management, multi-tenancy, and enterprise-ready solutions for effective data insights.
How We Built a Highly Scalable Machine Learning Platform Using Apache Mesos
Explore building a scalable machine learning platform using Apache Mesos, combining microservices with big data technologies for efficient machine translation and data processing.
Using External Persistent Volumes for High Availability on DC/OS - Reducing Recovery Times
Learn to reduce recovery times and achieve high availability for distributed applications on DC/OS using external persistent volumes, with practical examples and demonstrations.
State is Hard: An SDK for Building Stateful Applications
Learn to build robust stateful applications using the DC/OS SDK, simplifying development on Apache Mesos and DC/OS platforms while standardizing service interactions and handling common challenges.
Using External Persistent Volumes for High Availability on DC/OS
Explore strategies for reducing recovery times and achieving high availability in DC/OS using external persistent volumes, focusing on distributed applications like Cassandra and HDFS.
HDFS CSI Plugin: Speeding Up Kubernetes in On-Premises Big Data Clusters
Explore HDFS CSI plugin design for Kubernetes in on-premises big data clusters, including architecture, best practices, and performance analysis using Spark and TPC-DS benchmarks.
GraphLab - Machine Learning for Big Data in the Cloud
Explore GraphLab, a framework for efficient parallel machine learning algorithms handling Big Data. Learn about its advantages over existing tools and its impact on large-scale tasks.
A Short Summary of the Last Decades of Data Management - GOTO 2024
Explore the evolution of data management over decades, from monolithic systems to open-source engines and cloud computing, examining key trends, successes, and failures in this trillion-dollar industry.
Data Engineering Roadmap and Full Course with Python and SQL for 2024
Comprehensive guide to data engineering, covering Python, SQL, big data technologies, cloud platforms, and data warehousing tools. Includes hands-on tutorials and real-world projects for practical skill development.