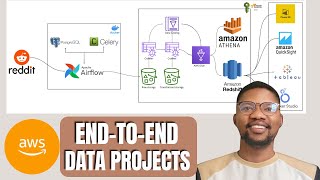
Reddit Data Pipeline Engineering with AWS - End-to-End Data Engineering
Build a comprehensive Reddit data pipeline using AWS services, integrating Airflow, S3, Glue, Athena, and Redshift for efficient ETL processes and analytics.
Apache Airflow with Spark for Data Engineers - Full Course
Build end-to-end data engineering projects using Apache Airflow, Docker, Spark, and multiple programming languages. Learn to create and submit jobs to Spark clusters for processing and view real-time results.

Delta Live Tables: Building Reliable Data Pipelines with Databricks
Simplify ETL development with declarative pipelines, automatic testing, and deep visibility for reliable batch and streaming data on Databricks Lakehouse Platform.
Building Scalable and Effective Data Pipelines with Argo for Large-Scale Metadata Processing
Discover how to build high-performance data pipelines using Argo's parallelization techniques, achieving massive scale with 450% faster processing times and efficient metadata ingestion for large-scale data operations.
Building Production-Ready Data Applications with Databricks Asset Bundles - Cookies Dataset Analysis
Master real-time analytics and streaming data applications using Databricks Asset Bundles, featuring hands-on experience with the Bakehouse application and AI-powered store location optimization.