Data Pipeline Scorecard: Evaluating Python Processing Approaches
Explore data processing approaches in Python, comparing different methods and their practical applications for building efficient data pipelines and optimizing workflow performance.

Kafka Connectors: Introduction to Kafka Connect Framework
Explore Kafka Connect framework for integrating Kafka with external systems, focusing on cluster setup and connector functionality.

Azure Data Factory: Cloud ETL Service for Data Integration and Transformation
Master Azure Data Factory for serverless data integration and transformation, with code-free UI and SSIS compatibility.

Charting the Lakehouse Trail: A Data Migration Adventure
Explore a data migration journey from legacy warehouse to modern lakehouse. Gain insights on overcoming challenges and achieving seamless transitions for your organization.
SQL 엔진을 더욱 강력하게 - 비정형 데이터 분석 정상에 서다
Discover how SK Hynix transforms unstructured semiconductor equipment data into structured formats using TrinoPy+, an enhanced SQL solution that enables seamless data preprocessing, analysis, and loading with single SQL queries.
Building Mobility Data Platform with EMR and Airflow
Discover how to build and optimize a mobility data platform using AWS EMR and Airflow, focusing on migration strategies, cost optimization, and infrastructure automation with Terraform.
On-Premise Kubernetes and Airflow ETL Platform (Haflow) - Introduction and Implementation
Discover SK하이닉스의 클라우드 네이티브 ETL 플랫폼 Haflow의 구축 사례와 아키텍처를 통해 기존 ETL 솔루션의 한계 극복 방안과 리소스 최적화 전략을 파악하세요.
Enriching the Data vs Filtering in Apache Spark
Explore data enrichment vs filtering in Spark for improved performance and scalability in cloud-native applications, with practical examples and insights from Capital One's loyalty use case.
Apache NiFi, Kafka, RisingWave, and Iceberg for Stock Data Processing with LLM - Conf42 Python 2024
Explore stream processing with Apache NiFi, Kafka, RisingWave, and Iceberg. Learn real-time analytics, event-driven applications, and integrating stock data with LLMs in this comprehensive overview.
Building Apache NiFi 2.0 Python Processors - Conf42 Python 2024
Explore Apache NiFi 2.0 Python processors for data engineering, covering features, use cases, and real-time generative AI integration with a live demo.
Top 10 Azure Data Factory Tips and Tricks for Speed, Cost, and Performance
Discover 10 essential Azure Data Factory tips to enhance performance, reduce costs, and streamline data integration solutions for improved efficiency.

Choosing Between Microsoft Fabric, Azure Synapse Analytics and Azure Data Factory
Compare Microsoft Fabric, Azure Synapse Analytics, and Azure Data Factory to select the optimal Data Integration solution for your project. Gain insights on their strengths and limitations.
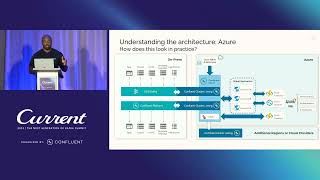
Unlocking Real-Time Data Insights: Leveraging Confluent Cloud on Azure
Leverage Confluent Cloud on Azure to build real-time data flows, capture changes instantly, and simplify data pipeline development. Boost productivity and innovate faster with streaming data pipelines and self-service access.

Processing Trillions of Records with Mini Serverless Databases at Okta
Explore serverless DuckDBs for efficient data processing, optimizing batch ETL, streaming, and SQL flexibility while addressing Kafka, latency, and ELT complexities in large-scale environments.
Transforming Legacy Reporting to Cloud-Based BI Applications
Streamlining 900+ legacy reports into a centralized cloud-based metric hub for TD's Personal Banking, enhancing data governance and cost-efficiency while providing a single source of truth.
Architecture Analysis for ETL Processing - CPU vs GPU
Explore GPU acceleration for ETL operations, comparing CPU and GPU architectures. Learn about performance gains in database operations and SQL query acceleration using GPUs.
Integrating Informatica Cloud Data Integration with Databricks Unity Catalog
Integrate Informatica Cloud with Databricks Unity Catalog for enhanced data quality, lineage tracking, and analytics. Learn to configure Databricks connectors in Informatica for seamless data ingestion and transformation.
Fabricator - Streamlining Declarative Feature Engineering at DoorDash
Découvrez comment DoorDash a développé Fabricator, un framework complet pour rationaliser l'ingénierie des caractéristiques déclaratives, orchestrant efficacement 1400 tâches quotidiennes et gérant 2,2 billions de valeurs.

End-to-End Modern Data Engineering with DBT and BigQuery
Master modern data engineering with DBT and BigQuery. Set up, link, transform data, convert tables to views, seed data, write tests, and generate documentation in this comprehensive tutorial.
Next-Gen Data Modeling, Integrity, and Governance with YODA - Insights from Yotpo and ZipRecruiter
Explore next-gen data modeling strategies for large-scale systems. Learn about YODA, an internal tool combining developer experience, DBT, Databricks, and more, to address data standardization and governance challenges.
The Future of Streaming Data - Challenges and Opportunities
Explore the future of streaming data, focusing on managing complex data connections, adopting Kafka internally, and addressing challenges in data governance, security, and movement across organizations.