Reaching Lightspeed Data Science - ETL, ML, and Graph with NVIDIA RAPIDS
Accelerate data science workflows using GPUs and RAPIDS. Learn performance gains, easy migration, and new possibilities in ETL, ML, and graph analytics.
Uber's Batch Analytics Evolution from Hive to Spark
Explore Uber's strategic migration from Hive to SparkSQL for batch analytics, including automation features, challenges faced, and efficiency gains achieved in this data processing evolution.
Building a Multimodal Data Lakehouse with the Daft Distributed Python Dataframe
Explore Daft, a next-gen distributed query engine for processing multimodal data at scale. Learn to build a multimodal data lakehouse using familiar dataframe interfaces on existing infrastructure.
Moving from SAP Business Warehouse to Databricks - Insurance Company Case Study
Explore an insurance company's migration from SAP BW to Databricks, highlighting improved performance, automated ETL, enhanced self-service, and cost reduction. Learn insights and future possibilities.
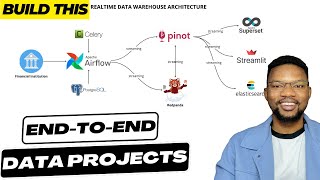
Building Realtime Data Warehouses from Scratch - End-to-End Data Engineering Project
Design and implement a real-time data warehouse with Apache Airflow, Kafka, and Pinot. Create custom hooks, ingest batch and streaming data, and visualize evolving data using Apache Superset.
The Metadata-Driven Data Warehouse
Streamline data warehouse development using metadata-driven approaches. Learn efficient techniques for Insert/Update/Delete operations and pipeline management.
Query Folding in Power Query: Importance for Performance
Discover query folding's importance for Power Query performance and learn factors that can hinder its effectiveness.
Building Tomorrow's Warehouse Today - Modern Data Warehouse Modelling Insights
Explore fundamental shifts in data warehousing architecture and processing design principles for modern, efficient data management and analysis.
How to Pick the Best Data Transformation Strategy
Explore tools for combining data from multiple sources, including Azure Synapse, Spark, and Power BI Data Flows. Learn to select the optimal tool for your data environment.
Declarative ETL Pipelines with Delta Live Tables - Modern Software Engineering for Data Analysts and Engineers
Modernize ETL pipelines using Delta Live Tables for efficient data management. Learn development, production, and best practices for reliable, testable, and scalable data processing.
Introduction to Orchestrating ETL Processes with Apache Airflow
Master Apache Airflow's workflow management capabilities for ETL processes through practical examples. Learn core concepts like DAGs, Tasks, Variables, and XComs while building efficient data engineering pipelines.
Master Azure Automation - The Azure Automation Service
Learn to automate tasks in Azure using Automation Accounts. Explore job scheduling, runbooks, configuration management, and PowerShell modules for efficient cloud operations.
Apache Kafka and the Rise of the Streaming Platform
Explore streaming platforms with Apache Kafka as the core, revolutionizing data flow management. Learn how this technology acts as a central nervous system for modern digital businesses.
Rise, Fall and Re-Rise of the Semantic Layer - Evolution and Future of Data Management
Explore the evolution of semantic layers in data management, from traditional systems to modern metric stores, while understanding key challenges and future directions in data truth management.
Leveraging Large Language Models for ETL, Analytics, and Modern Data Stack
Discover how Large Language Models revolutionize data workflows, from ETL processes to analytics automation, with practical insights on implementation challenges and production deployment strategies.
Building an Integrated Data Asset Platform with Apache DolphinScheduler - DataOps Track
Discover how Apache DolphinScheduler powers Unicom Digital Technology's integrated data asset platform, exploring key features and implementation strategies for efficient data operations.
Experimental KERAS Feature Space for Medical AI Heart Attack Prediction
Dive into advanced feature scaling with KERAS Feature Space, building a medical AI system to predict heart attack probabilities using structured data classification and optimized data pipelines.
Solving Migration Pipelines
Explore strategies for solving migration pipeline challenges in cloud-native environments, focusing on efficiency and scalability.
Building a Petabyte-Scale Cybersecurity Data Mesh in Azure with Delta Lake - HSBC Case Study
Explore HSBC's innovative approach to building a petabyte-scale cybersecurity data mesh in Azure, leveraging Delta Lake to address unique challenges and empower analysts with a unified, scalable platform.
Data Engineering Roadmap and Full Course with Python and SQL for 2024
Comprehensive guide to data engineering, covering Python, SQL, big data technologies, cloud platforms, and data warehousing tools. Includes hands-on tutorials and real-world projects for practical skill development.
Managing ETL Change Using BIMLScript
Automate ETL processes using BIMLScript and metadata to easily adapt to source file changes, demonstrated with US census data and applicable to SSIS and Azure Data Factory.