Introducing PyTorch 1.0 - A Research-Focused, Production-Ready Deep Learning Framework
Explore PyTorch 1.0, a powerful deep learning framework that bridges research and production, accelerating AI development with innovative features and tools.
Taking Models to the Next Level with Azure Machine Learning
Explore Azure Machine Learning for custom model training, from pre-built cognitive services to AutoML and hyperparameter tuning, with practical examples for text analysis and sentiment analysis.
Recently Engineered Variants of Split Learning - Seminar 87
Explore advanced variants of split learning techniques in federated systems, focusing on recent engineering developments and applications in distributed machine learning architectures.
Scaling Deep Learning Model Training
Learn techniques for scaling deep learning model training across distributed systems, reducing training time from days to hours while maintaining cost efficiency.
Distributed Training and Gradient Compression - Lecture 14
Explore distributed training challenges, focusing on bandwidth and latency bottlenecks. Learn gradient compression techniques and delayed gradient averaging to optimize communication in deep learning systems.
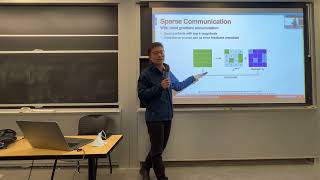
Distributed Training and Gradient Compression - Lecture 14
Explore distributed training challenges, focusing on bandwidth and latency bottlenecks. Learn gradient compression techniques and delayed gradient averaging to optimize communication in deep learning.
Distributed Training: Techniques and Strategies - Part II - Lecture 18
Explore advanced distributed training techniques for machine learning, focusing on efficiency and scalability in large-scale AI systems.
Distributed Training for Efficient Machine Learning - Part II - Lecture 18
Explore advanced distributed training techniques for machine learning, focusing on efficiency and scalability in large-scale systems.
Systems Engineering in Machine Learning - Navigating Low-Level Challenges
Explore systems engineering in ML with Andrew Dye, discussing low-level work, blending disciplines, and ML infrastructure challenges. Gain insights on distributed training, managing scale, and bridging gaps between firmware and MLOps.
Accelerating Multimodal AI - From Tabular ML to Generative Video Systems
Explore challenges and solutions in multimodal AI, from data management to efficient inference. Learn about systems supporting research and productionization in generative video and language models.
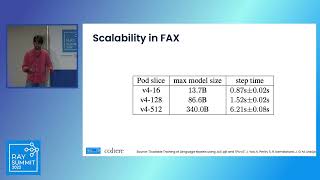
Scalable Training of Language Models Using Ray, JAX, and TPUv4
Explore challenges and design decisions for scalable language model training, with quantitative analysis of efficiency improvements using Ray, JAX pjit, and TPUv4.
Best Practices for Productionizing Distributed Training with Ray Train
Explore fault-tolerant distributed training techniques using Ray Train, covering experiment restoration, node failure recovery, cloud storage snapshots, and large model checkpointing for efficient AI workloads.
Next-Generation Networks for Machine Learning
Explore next-gen networks for machine learning, focusing on optical fabrics and scheduling techniques to accelerate distributed DNN training workloads and overcome datacenter network bottlenecks.
Detecting and Overcoming GPU Failures During ML Training
Explore GPU failure challenges in ML training, learn proactive detection methods, and discover fault-tolerant distributed training principles to mitigate issues and optimize performance.
Leverage Topology Modeling and Topology-Aware Scheduling to Accelerate LLM Training
Explore topology modeling and scheduling techniques to optimize LLM training performance. Learn to address network bottlenecks and enhance resource allocation for AI workloads in Kubernetes environments.
Distributed Training and Gradient Compression - Part I - Lecture 13
Explore distributed training of neural networks, focusing on data parallelism and model parallelism techniques for efficient machine learning on resource-constrained devices.
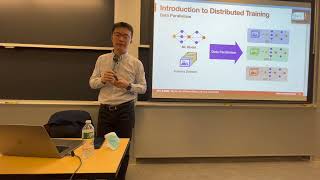
Distributed Training and Gradient Compression - Part I - Lecture 13
Explore distributed training of neural networks, focusing on data parallelism and model parallelism techniques for efficient machine learning on resource-constrained devices.
Distributed Training for Efficient Machine Learning - Part I - Lecture 17
Explore distributed training techniques for machine learning, focusing on data and model parallelism strategies to enhance efficiency and scalability.
Distributed Training - Part I - Lecture 17
Explore distributed training techniques for efficient machine learning, covering key concepts and strategies for scaling ML models across multiple devices.
Azure AI Training and Fine-tuning Custom LLMs with Distributed Training
Master distributed training techniques for custom LLMs using Azure AI infrastructure, focusing on performance optimization, scalability, and efficient deployment with ND H100 and H200 series.
Distributed Training Methods and Parallelization Techniques - Lecture 19
Explore advanced distributed training concepts, from data parallelism and communication primitives to pipeline, tensor, and sequence parallelism methods for efficient machine learning systems.