
AutoML and Training Working Group Updates - Kubeflow Developments
Explore AutoML and Training Working Group updates for Kubeflow, including Katib's V1 API graduation, advanced parameter distribution, and LLM tuning, plus Training Operator's roadmap for enhanced ML framework support.
A Scalable Platform for Training and Inference Using Kubeflow at CERN
Explore CERN's Kubeflow-based machine learning platform for data preparation, analysis, training, and inference in physics research, with insights from the ATLAS experiment.
AutoML and Training Working Group Updates for Kubeflow
Explore AutoML and Training Working Group updates for Kubeflow, including Katib's 2024 roadmap, Training Operator enhancements, and advancements in distributed ML training on Kubernetes.
Building the Fine-Tuning Pipeline for Alignment of LLMs
Explore key aspects of aligning LLMs and set up infrastructure for a versatile alignment pipeline. Learn data collection, prompt tuning, and workflow management techniques.
Democratizing Machine Learning on Kubernetes
Learn to scale machine learning on Kubernetes, exploring data and model parallelization, distributed training, and performance optimization techniques for large-scale AI projects.
Building and Managing a Centralized ML Platform with Kubeflow at CERN
Explore CERN's centralized ML platform using Kubeflow, covering data preparation, model training, and serving. Learn about resource optimization, integration challenges, and cloud expansion possibilities.
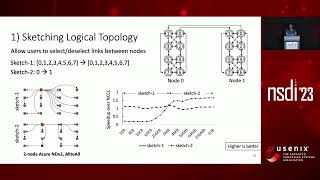
TACCL - Guiding Collective Algorithm Synthesis Using Communication Sketches
Innovative tool for synthesizing efficient communication algorithms in multi-GPU machine learning, outperforming NCCL and accelerating model training across various hardware configurations.
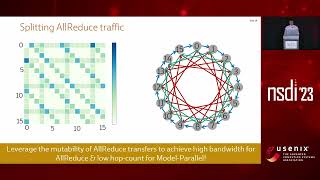
TopoOpt - Co-optimizing Network Topology and Parallelization Strategy for Distributed Training Jobs
Novel direct-connect fabric optimizing distributed DNN training across computation, communication, and network topology. Reduces training time by up to 3.4x compared to similar-cost Fat-Tree interconnects.
Machine Intelligence at Google Scale
Explore Google's scalable machine learning infrastructure, including pre-trained APIs and distributed training with TensorFlow, accelerating custom model development by 10x-40x.
Using Kubernetes for Machine Learning Frameworks
Explore Kubernetes for machine learning frameworks, covering setup, training, and inference phases. Learn to deploy TensorFlow, Apache MXNet, and PyTorch on Kubernetes clusters for efficient ML model production.
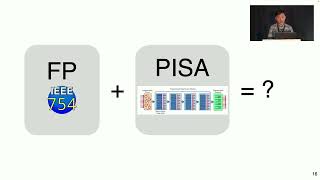
Unlocking the Power of Inline Floating-Point Operations on Programmable Switches
Explore FPISA, a novel floating-point representation for programmable switches, enabling efficient acceleration of machine learning and query processing applications in network hardware.
Operating Deep Learning Pipelines Anywhere Using Kubeflow
Explore building and operating production-grade deep learning pipelines using Kubeflow, covering data preparation, storage, automation, and infrastructure management for multiple tenants.
Scale Your Batch, Big Data, and AI Workloads Beyond the Kubernetes Scheduler
Explore solutions for scaling batch, big data, and AI workloads on Kubernetes. Compare projects like Karmada, Koordinator, and Kueue to optimize cluster utilization and overcome scheduling challenges.
Enabling Efficient Trillion Parameter Scale Training for Deep Learning Models
Explore DeepSpeed's optimizations for efficient distributed training of large-scale deep learning models, addressing memory, compute, and data challenges in extreme model scaling.
Simplified Training, Tuning and Deployment of Foundational Models as a Service with Red Hat OpenShift
Simplify end-to-end lifecycle of foundation models using Red Hat OpenShift Data Science. Learn about cloud-native, scalable stack for training, tuning, and inferencing with integrated open-source components.
VeScale - A PyTorch Native LLM Training Framework
Explore a novel PyTorch-native framework for LLM training, combining automatic parallelism and ease of use. Scale your models efficiently with single-device code and transparent nD parallelization.
Metis - Fast Automatic Distributed Training on Heterogeneous GPUs
Efficient distributed training system for heterogeneous GPUs. Optimizes parallelism plans, improves resource utilization, and achieves significant speed-ups for large deep learning models.
Supercharging AI Training with Mosaic Streaming and Lance Columnar Format
Explore innovative data infrastructure for efficient AI model training, featuring Mosaic StreamingDataset and Lance columnar format for improved performance and cost-effectiveness in large-scale datasets.
Machine Intelligence at Google Scale - Vision - Speech API
Explore Google's scalable Machine Learning solutions, including Vision and Speech APIs, TensorFlow, and Cloud ML. Learn about distributed training and pre-trained services for efficient AI development.
Machine Learning Using Kubeflow and Kubernetes
Explore machine learning workflows on Kubernetes using Kubeflow, covering deployment, training, inference, and advanced features like hyperparameter tuning and automated pipelines.

Inside TensorFlow - tf.data + tf.distribute
Explore best practices for tf.data and tf.distribute in TensorFlow, covering input pipelines, performance optimization, and distributed training strategies for multi-GPU and TPU setups.