Building a Distributed Search Engine for Logs
Explore efficient architecture for building a distributed search engine to handle terabytes of logs, inspired by Snowflake's compute-storage separation approach.
Property-Testing Async Code in Rust for Reliable Distributed Systems
Explore property-testing techniques for async Rust code to enhance reliability in distributed systems. Learn to implement a deterministic runtime for comprehensive asynchronous execution path testing.
Communication Between Microservices - Call Me Maybe
Explore microservice communication strategies through a demo app, comparing REST APIs, gRPC, event busses, and automated networking for effective architecture design.
Modern Development of Cloud Applications Using Service Weaver
Explore Service Weaver, a Go framework for high-performance distributed apps. Learn to simplify development, improve latency, reduce costs, and optimize cloud deployments compared to traditional microservices.
Building a Cloud Platform for Global Deployments in Go
Explore building a cloud platform for global Go app deployments using BareMetal, Nomad, Kuma, and gRPC. Learn key strategies for worldwide distribution and scalability.
Gophers Like Waiting in Postgres Queue - Implementing Asynchronous Processing with Go and PostgreSQL
Implement reliable asynchronous job processing using Postgres as a queue mechanism in Go. Simplify architecture and improve observability for distributed workloads.
Introduction to Apache Kafka - Core Concepts and Use Cases
Explore Apache Kafka's fundamentals, history, key concepts, and real-world applications. Learn how to deploy and manage Kafka using Canonical's Charmed Kafka solution.
AI Storage with Ceph - Optimizing Storage for AI/ML Workflows
Explore AI's impact on storage systems and how Canonical Ceph can optimize AI/ML workflows for faster insights and innovation.
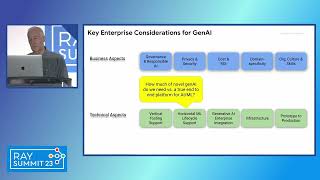
Making Your Enterprise GenAI Ready and GenAI Enterprise Ready
Prepare your organization for GenAI challenges and opportunities. Learn best practices for integrating GenAI capabilities with enterprise security, privacy, and guardrails. Explore Google Cloud's innovative GenAI solutions for enterprise environments.
Fast LLM Serving with vLLM and PagedAttention
Explore vLLM, an open-source library for fast LLM inference using PagedAttention. Learn how it achieves higher throughput and its implementation for efficient AI model serving.
Embeddings and Vectors: The Key to Production AI
Explore how teams program AI with data using embeddings and vectors, and learn about future approaches for building production AI applications.
Large Scale Pathways Recommender Systems (PaRS) at Verizon
Explore Verizon's innovative multi-task learning recommender system, PaRS, leveraging Ray ecosystem to enhance customer experience through deep learning and efficient large-scale model training.
Enabling End-to-End LLMOps on Michelangelo with Ray
Explore Uber's extension of Michelangelo for end-to-end LLMOps, leveraging Ray for scalable development with hundreds of A100 GPUs and integrating open-source techniques for efficient custom LLM creation.
A Ray-based ML Platform for Early Cancer Detection
Explore how Ray enhances scalability and efficiency in machine learning for early cancer detection, focusing on improved model development and evaluation for potential diagnostic applications.
Ray Train: A Production-Ready Library for Distributed Deep Learning
Explore Ray Train's architecture for efficient, cost-effective distributed deep learning. Learn about resource scheduling, API simplicity, and exclusive features for LLM training, including Distributed Checkpointing.
Scalable and Flexible Distributed Reinforcement Learning Systems
Explore scalable distributed reinforcement learning systems, focusing on flexible training loops, statement management, and GPU allocation. Gain insights into building efficient RLHF systems for large-scale applications.
The Role of MPI in Modern AI - Rusty Lusk's Legacy
Explore MPI's crucial role in modern AI and its impact on parallel computing, honoring Rusty Lusk's contributions to the field.
From Two Strong Oxen to Billions of Fleas - The Evolution of Massively Parallel Distributed Supercomputers
Explore massively parallel distributed supercomputers, focusing on distributed-memory parallelism and RDMA through MPI. Gain insights into current designs and future challenges in high-performance computing.
Evaluating Large-Scale Learning Systems
Explore challenges and solutions in evaluating large-scale machine learning systems, including federated networks and large language models. Gain insights into reliable assessment methods.
Lies, Damned Lies and Timeouts Engineering
Explore the complexities of timeouts in distributed systems with Twitter's Principal Software Engineer. Learn to interpret and utilize timeouts effectively for robust system design.
The Challenges of Kubernetes Data Protection - Real Examples and Solutions
Explore real-world challenges in Kubernetes data protection, focusing on application definition, data consistency, and cross-environment restoration. Learn practical solutions using Velero.