Rook - Introduction and Deep Dive with Ceph Storage
Explore Rook, a cloud-native storage operator for Kubernetes, and its integration with Ceph. Learn about block, file system, and object storage solutions for production environments.
Highly Available Search Platform for Data Resilience and Compliance at Shopify
Explore Shopify's highly available search platform, leveraging Kafka for real-time indexing and Elasticsearch for efficient querying across global regions, ensuring data resilience and compliance.
How Camunda 8 Manages Diverse Endpoints in Distributed Systems
Explore Camunda 8's integration of diverse endpoints in distributed systems, showcasing flow logic implementation and end-to-end process visualization across microservices, people, and devices.
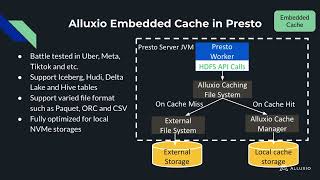
Caching Framework for Exabyte-Scale Data Lakes
Optimize exabyte-scale data lakes with open-source caching framework. Improve performance, reduce costs, and tackle challenges in complex data environments using Hadoop, Parquet, Hudi, and Alluxio.
New Features of Apache NiFi - Tips and Techniques
Explore Apache NiFi's latest features, processors, and best practices. Build efficient data flows using cutting-edge techniques, with tips and guides for optimal implementation.
Through the Looking Glass: Key Architectural Choices in Flink and Kafka Streams
Explore architectural differences between Apache Flink and Kafka Streams, gaining insights into stream processing fundamentals and design choices for improved system performance.
Meta Velox - Advanced Database Systems - Lecture 23
Explore Meta's Velox query execution engine, its architecture, and its role in modern data processing systems. Learn about its features and performance optimizations.

Snowflake Data Warehouse Internals - Lecture 21
Explore Snowflake's data warehouse architecture, design principles, and internal mechanisms for efficient cloud-based data management and analytics.
Modern Analytical Database Systems - Lecture 2
Explore modern analytical database systems, covering distributed architectures, query execution, and OLAP commoditization in this advanced CMU lecture.
Snowflake Database Architecture Overview - Lecture 25
Explore Snowflake's cloud-based database architecture, including query execution, optimization, and workload management, with insights from industry experts.
Yellowbrick Data Warehouse System - Lecture 21
Explore Yellowbrick's innovative data warehouse system, its architecture, and performance optimizations for analytical workloads in this advanced database systems lecture.
Snowflake Data Warehouse Internals - Lecture 19
Explore Snowflake's data warehouse architecture, design principles, and internal workings. Gain insights into its innovative approach to cloud-based data management and analytics.
The Secret to Great Developer Experience Is Killer Content
Discover strategies for creating compelling developer-focused content that enhances user experience, drives engagement, and differentiates open-source projects from commercial products.

Elasticsearch Capability - Introduction and Overview
Discover powerful distributed search and analytics with Elasticsearch. Learn to index, analyze, and retrieve data in real-time for diverse applications.
ByteDance's 100 Billion File HDFS Clustering Practice
Explore ByteDance's HDFS clustering practices for 100 billion files. Learn about storage scheduling, multi-region computing, and data management techniques for large-scale big data applications.
Introducing Apache Pinot: Real-time Analytics for Large-Scale Data
Explore Apache Pinot's real-time analytics capabilities, architecture, and data model. Learn about its query language, indexing, and use cases in high-performance applications.
Building a Real-Time Analytics Database
Odkryj tajniki tworzenia bazy danych do analityki w czasie rzeczywistym. Poznaj kluczowe koncepcje i najlepsze praktyki w tej dziedzinie.
Gravitino - A Multi-Regional Geo-Distributed Meta Datalake
Discover how to build and manage distributed meta datalakes using Gravitino, exploring multi-regional architectures and implementation strategies for scalable data solutions.
AI and Blockchain - Shaping the Future Through Synergistic Technologies
Explore how AI and blockchain technologies converge to create powerful synergies, examining their complementary strengths in data integrity, security, and decision-making capabilities.

Unlocking the Power of Apache Flink - An Introduction in 4 Acts
Explore Apache Flink's core principles for real-time data processing, including shared-nothing architecture, event-time processing, and state snapshots, through practical examples and demos.
Breaking Out of the Habit of Bulk Loading Everything - Lessons from Streaming Data Integration
Explore transitioning from bulk loading to streaming data integration, leveraging Azure services for real-time analytics and long-term storage in data warehousing.