Analyzing and Visualizing OpenTelemetry Traces with SQL
Hands-on workshop exploring OpenTelemetry trace analysis using SQL and Grafana. Learn to ingest, query, and visualize distributed system data for powerful insights and proactive issue detection.
The Unexplored World of OpenTelemetry and Service Mesh
Explore the pros and cons of using service mesh tools like Istio for generating traces compared to OpenTelemetry. Learn about sampling, third-party services, implementation, and visualization to make informed decisions.
CNL - Using OTel Distributed Tracing for Real-Time Observability
Explore real-time observability with OTel distributed tracing, covering challenges, deployment architecture, service maps, and error detection in cloud-native environments.
Chaos Engineering with LitmusChaos - Project Update
Explore the latest advancements in Chaos Engineering using LitmusChaos, a powerful tool for enhancing system resilience and reliability in cloud-native environments.
Writing Reliable, Scalable, Fault-Oblivious Code on Kubernetes - Best Practices and Abstractions
Learn best practices for writing distributed app code that excels at scale, focusing on resiliency, distributed locking, and optimization for Kubernetes environments.
Innovations in Theoretical Computer Science 2020 - Session 5
Explore cutting-edge research in theoretical computer science, including secure computation, communication protocols, coding theory, and fault-tolerant algorithms presented at ITCS 2020.
Systems Research Group Presentations on Distributed Storage and Kernel Extensibility
Graduate students present cutting-edge research on distributed systems, including scalable storage, efficient model checking, and safe kernel extensibility, showcasing innovative solutions to complex computing challenges.
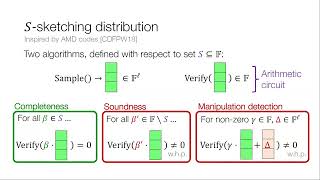
Secret Sharing - Crypto 2023 Session 2
Explore advanced cryptographic techniques and applications of secret sharing in this Crypto 2023 session, chaired by Arkady Yerukhimovich.
How We Built a gRPC Consistent Hashring for SpiceDB
Explore the development of a gRPC consistent hashring for SpiceDB, enhancing distributed system performance and scalability in cloud-native environments.
Building Choreography Sagas in Kalix
Explore choreography sagas in Kalix for cloud-native computing. Learn to implement distributed transactions and manage complex workflows in microservices architectures.

Threshold Cryptography and Distributed Broadcast - AC 2023 Session
Explore cutting-edge advancements in threshold cryptography and distributed broadcast systems in this comprehensive session from AC 2023, featuring expert insights and discussions.
SIG-Multicluster Introduction and Deep Dive - Managing Multiple Kubernetes Clusters
Explore SIG-Multicluster's solutions for managing multiple Kubernetes clusters, including best practices, current projects, and future directions. Learn how to contribute and shape the multi-cluster Kubernetes landscape.
Real-time Adaptive Controls for Increased Resiliency - Lecture
Explore real-time Adaptive Controls for dynamic tuning of distributed systems, enhancing resilience through automatic parameter adjustment based on error and latency sampling, as implemented at CrowdStrike.
Monitoring and Metadata - Exploring Approaches to Attaching Metadata to Logs, Metrics and Traces
Explore approaches for attaching metadata to logs, metrics, and traces in complex systems. Learn how metadata enhances observability, enables effective troubleshooting, and improves analysis in monitoring systems.
APRON: Authenticated and Progressive System Image Renovation
Innovative approach to secure OS recovery, minimizing downtime through progressive block repair and verification. Outperforms conventional methods, enabling swift system restoration with minimal performance impact.
Linux in Space: Fault Detection, Recovery and Fault-Tolerant System Designs
Explore fault detection, recovery, and fault-tolerant system designs for Linux in space environments. Learn strategies to ensure reliability and autonomy in hostile conditions.
Cognitive and Self-Adaptive System for Effective Distributed Tracing
Explore a cognitive, self-adaptive system for effective distributed tracing using Jaeger and Open Tracing. Learn how ML improves trace collection, reduces MTTR, and optimizes resource utilization.
Scala-Powered Strategies for Building Fault-Tolerant Systems
Explore Scala-based strategies for building resilient systems, covering bulkhead, caching, config management, fallback mechanisms, retries, and circuit breakers.
Chaos Engineering in Action - Building Fault-Tolerant Systems
Explore chaos engineering principles and practices to build resilient systems. Learn to plan, execute, and analyze experiments for improving fault tolerance and system reliability.
Scaling OpenTelemetry Collectors Using Kafka - Conf42 SRE 2024
Learn to scale OpenTelemetry collectors using Kafka for improved observability in large-scale systems. Explore architecture, implementation, and monitoring techniques for efficient data processing and analysis.
Simplifying Multi-Cloud Observability with OpenTelemetry
Explore multi-cloud observability challenges and learn how OpenTelemetry simplifies monitoring across diverse cloud environments for improved system visibility and performance.