Cross-Server Data Joins on Slow Networks with Python
Efficient techniques for querying and joining data across distant machines using Python, addressing slow network transfers and large datasets that exceed local memory.
Data of Unusual Size - Interactive Visualization
Learn techniques for analyzing and visualizing massive datasets using Python libraries like Dask and hvPlot. Explore efficient data formats, parallel computation, cloud resources, and interactive visualization for large-scale data science projects.
Programmazione MapReduce in Python con Pydoop
Esplora la programmazione MapReduce utilizzando Pydoop, un potente framework Python per l'elaborazione di big data distribuita su cluster Hadoop.
Data Plumbing with Python
Explore efficient data manipulation techniques using Python for seamless integration, transformation, and analysis of diverse datasets.
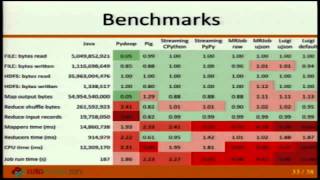
Big Data with Python and Hadoop
Introduction to big data processing using Apache Hadoop and Python. Explores Hadoop concepts, infrastructure, Python implementations, and available libraries for efficient big data handling and job acceleration.
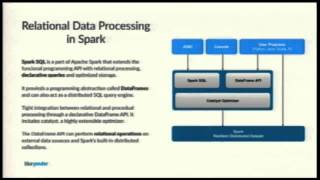
PySpark - Data Processing in Python on Top of Apache Spark
Learn PySpark for large-scale data processing with Python on Apache Spark. Covers RDDs, DataFrame API, transformations, actions, and data sources. Ideal for those seeking efficient big data analysis techniques.
Building a Multi-Purpose Platform for Bulk Data Using SQLAlchemy
Learn to build a scalable platform for processing bulk data across multiple business domains using SQLAlchemy, with insights on optimizing performance and maintaining flexibility.
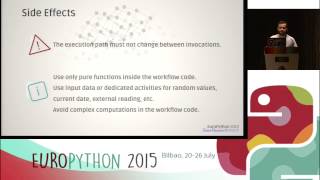
Distributed Workflows with Flowy
Explore distributed, asynchronous workflows with Flowy, a library for orchestrating complex processes across multiple machines. Learn execution models, topologies, and scaling techniques.
Data-Visualisation with Python and Javascript - Crafting a Data-Viz Toolchain for the Web
Explore data visualization using Python and JavaScript, from scraping and cleaning data to creating engaging web visualizations with tools like Scrapy, Pandas, Flask, and D3.js.
Scale Your Data, Not Your Process - Welcome to the Blaze Ecosystem
Explore the Blaze ecosystem for scaling data processing across various technologies. Learn about tools for querying, migrating, and analyzing large datasets efficiently.

Things I Wish I Knew Before Starting Using Python for Data Processing
Discover essential Python techniques and software development principles for effective data processing, enhancing your skills beyond the scientific stack.
Facing the Challenge of Climate Change with Xarray and Dask
Explore climate data analysis using xarray and Dask, leveraging Python's scientific ecosystem to process and visualize complex climate forecasts and projections from the Copernicus Climate Change Service.
Feeding Data to AWS Redshift with Airflow
Explore Airflow for efficient data pipelines and learn to integrate it with AWS Redshift for effective ETL processes, schema management, and data transformation techniques.
Using Pandas and Dask to Work with Large Columnar Datasets in Apache Parquet
Explore efficient techniques for handling large columnar datasets using Pandas and Dask with Apache Parquet, including partitioning, row group skipping, and optimized data layout for faster queries.
All You Need is Pandas - Unexpected Success Stories
Discover efficient data processing with Pandas through real-world examples, from SVG stroke extraction to letter composition, showcasing improved performance and code maintainability.
Django Queries Optimization
Optimize complex Django queries by moving selection logic, calculations, and aggregations to the database, improving performance and maintainability of your web applications.
Distributed Multi-GPU Computing with Dask, CuPy and RAPIDS
Explore distributed multi-GPU computing using Dask, CuPy, and RAPIDS. Learn to leverage GPU acceleration and distributed systems for faster, more efficient data processing and analysis.
Extracting Tabular Data from PDFs with Camelot and Excalibur
Learn to extract tabular data from PDFs using open-source Python tools Camelot and Excalibur. Discover installation, usage, and automation techniques for efficient data extraction and processing.
Practical Optimisations for Pandas
Discover techniques for optimizing Pandas code, including bottleneck identification, computational efficiency, and memory management for improved performance in data processing tasks.
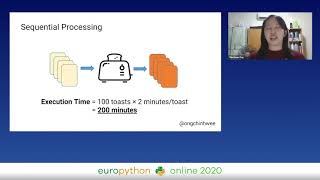
Speed Up Your Data Processing
Explore parallel and asynchronous programming techniques to optimize data processing pipelines, enhancing efficiency in data science workflows and overcoming common bottlenecks.
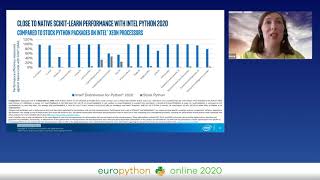
The Painless Route in Python to Fast and Scalable Machine Learning
Learn to optimize Python for high-performance machine learning, from Intel-enhanced packages to scalable data processing and analytics pipelines that rival C++/MPI performance on large datasets and clusters.