Top 15 Python Tips for Data Cleaning - Understanding
Discover 15 essential Python tips for effective data cleaning and understanding, focusing on Pandas and NumPy libraries to enhance your data analysis skills.
Mastering a Data Pipeline with Python - 6 Years of Learned Lessons from Mistakes
Explore key insights and best practices for building robust data pipelines with Python, covering data acquisition, transformation, storage, and workflow management based on 6 years of experience.
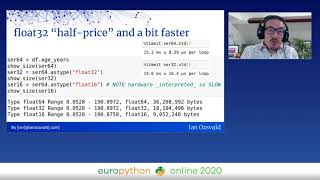
Making Pandas Fly
Optimize Pandas for larger datasets: compression techniques, faster operations, and alternatives like Dask and Vaex. Learn to process more data efficiently and boost your data analysis capabilities.
Innovation in the Newsroom
Explore BBC News Labs' innovative approach to enriching digital output using Python and AWS, focusing on extracting detailed information from TV and radio programme running orders.
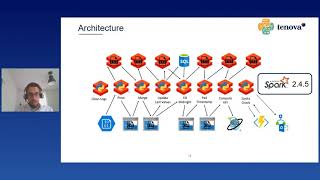
From Telemetry Data to CSVs with Python, Spark and Azure Databricks
Transforming industrial telemetry data into CSV format using Python, Spark, and Azure Databricks for analytics and AI model retraining in the context of Industry 4.0.
Measuring Memory - Python Memory Profilers and When to Use Them
Learn to measure and optimize Python memory usage, exploring profilers for different scenarios like web apps and data processing to prevent crashes and improve performance.
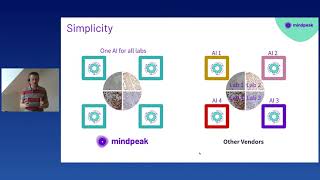
Speeding Up the Deep Learning Development Life Cycle for Cancer Diagnostics
Optimizing deep learning development for cancer diagnostics: strategies to accelerate iteration, from task prioritization to GPU parallelization, enhancing model robustness across diverse laboratory settings.
Czech Drought Monitoring System - A Journey from Manual Work to Global Drought Monitoring and Machine Learning, Powered by Python
Explore the journey of building a robust drought monitoring system using Python, geospatial tools, and data processing libraries for Czechia and Central Europe.
Python's Role in Unlocking the Secrets of the Universe with the James Webb Space Telescope
Explore how Python powers data processing for the James Webb Space Telescope, enabling groundbreaking discoveries about the Universe's origins, star formation, and exoplanets.
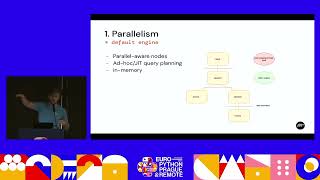
What Polars Does for You
Explore Polars, a fast and efficient DataFrame library built in Rust. Learn about its design, features, and advantages for modern data processing and analysis.
Apache Spark vs Cloud-Native SQL Engines
Opinionated comparison of Apache Spark and cloud-native SQL engines, exploring their strengths, use cases, and complementary nature for data processing and business intelligence tasks.
24HoP Spanish - Procesando XML de estructuras complejas con SSIS
Aprenda a procesar estructuras XML complejas utilizando SQL Server Integration Services (SSIS) para una eficiente manipulación y transformación de datos.
Data Positioning - Self-Defense or a Brilliant New Architecture
Explore Data Positioning's evolution in data management, learning its history, principles, and architecture for delivering value in current and future scenarios.
Batch Execution Mode on the Rowstore
Descubra como o Modo de Execução em Lote acelera o processamento de grandes volumes de dados em índices Rowstore no SQL Server 2019 e Azure SQL DB, suas vantagens e desafios.
Power Query: il tesoro nascosto dentro Power BI
Scopri le potenzialità di Power Query per la trasformazione dei dati in Power BI, inclusi i fondamenti del linguaggio M e le migliori pratiche per ottimizzare il suo utilizzo.
Big Data Analytics in SQL Server 2019 Big Data Cluster Using Spark
Learn to leverage Apache Spark for big data analysis in SQL Server 2019 Big Data Cluster, exploring techniques for processing and analyzing large-scale datasets efficiently.
Managing ETL Change Using BIMLScript
Automate ETL processes using BIMLScript and metadata to easily adapt to source file changes, demonstrated with US census data and applicable to SSIS and Azure Data Factory.
Head to Head - SSIS Versus Azure Data Factory
Comparative analysis of SSIS and Azure Data Factory, exploring strengths, weaknesses, and real-world applications for data movement and transformation in SQL Server environments.
Code Like a Snake Charmer – Advanced Data Modeling in Python
Comprehensive Python data modeling tutorial covering extraction, cleaning, transformation, visualization, predictive modeling, validation, and deployment using popular libraries and Azure integration.
Power Query, M and Dataflow - The Lightsaber for the Data Jedi
Discover Power Query's transformation capabilities, M language benefits, and Dataflows' role in Power BI. Learn advanced features through demos to enhance your data preparation skills.
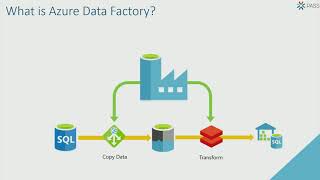
ETL in Azure Made Easy with Data Factory Mapping Data Flows
Explore Azure Data Factory's Mapping Data Flows for efficient, scalable ETL without coding. Learn to transform data using Databricks integration and graphical tools.