Why Lakehouse Architecture Now - Exploring Enterprise Data Warehouse Failures and the Need for Lakehouse Paradigm
Explore the shift from enterprise data warehouses to lakehouse architecture, focusing on benefits, challenges, and Starburst's role in powering SQL-based analytics on Delta Lake.
Building End-to-End Delta Pipelines on GCP
Explore building end-to-end Delta pipelines on GCP, covering data reliability, performance, and the Bronze-Silver-Gold architecture pattern, with practical code examples and Big Query integration.
Engagement Activity Delta Lake for Einstein Analytics and Sales Cloud Einstein
Explore how Salesforce built an engagement activity platform using Delta Lake to support Einstein Analytics and Sales Cloud Einstein, covering data ingestion, incremental reads, and mutation handling.
Accelerating MLOps with Apache Spark and SingleStore
Learn to accelerate MLOps using Apache Spark and SingleStore. Discover how to build fast analytical applications, manage supervised learning models, and scale AI/ML operations for data science success.
Designing and Implementing a Real-time Data Lake with Dynamically Changing Schema
Learn to build a robust streaming ETL pipeline that handles dynamically changing schemas and new event types without downtime, using Delta Lake and Databricks for real-time data lake implementation.
Cost Efficiency Strategies for Managed Apache Spark Service with Databricks
Explore cost-efficient strategies for Azure Databricks, including resource management, tier selection, and best practices for optimizing Apache Spark workloads in a managed cloud environment.
Migrating Airflow-Based Apache Spark Jobs to Kubernetes - The Native Way
Learn to migrate Airflow-based Apache Spark jobs to Kubernetes, reducing costs and improving stability. Explore challenges, best practices, and native Airflow integration for seamless transition from AWS EMR to K8s.
Getting Started with Apache Spark on Kubernetes
Learn to deploy and optimize Apache Spark on Kubernetes with hands-on demos, covering environment setup, application sizing, performance tuning, and monitoring for efficient data pipeline management.
Delta Lake: Optimizing Merge Operations
Explore Delta Lake merge optimization techniques, including inner and full outer joins, partition pruning, and file pruning. Learn tips for handling large merges efficiently.
Stateful Streaming with Apache Spark - Updating Decision Logic at Runtime
Learn how to implement stateful streaming with Spark, focusing on updating decision logic at runtime for real-time offer personalization in loyalty programs like PAYBACK.
Leveraging Apache Spark and Delta Lake for Efficient Data Encryption at Scale
Efficient data encryption solution for privacy compliance using Apache Spark and Delta Lake. Automates consumer deletion requests, enhances security, and maintains data integrity while ensuring accessibility when needed.
Fugue: Unifying Big Data Analytics Ecosystems for ETL and Machine Learning
Unifying big data ecosystems with Fugue: SQL-like framework for ETL and ML pipelines, compatible with Spark, TensorFlow, and more. Simplifies development, improves performance, and enhances maintainability.
Presto on Apache Spark - A Tale of Two Computation Engines
Explore the integration of Presto and Spark, combining low-latency evaluation with robust execution for enhanced SQL experience in both interactive and batch use cases at Facebook scale.
From Idea to Model: Productionizing Data Pipelines with Apache Airflow
Learn to productionize data pipelines using Apache Airflow, bridging data science and engineering. Explore collaborative workflows, custom operators, and scalable solutions for efficient model deployment and iteration.
Designing the Next Generation of Data Pipelines with Apache Spark - Zillow's Approach
Zillow's data engineering team shares their journey in redesigning data pipelines using Apache Spark, focusing on scalability, maintainability, and robustness while reducing code complexity.
Simplify and Boost Spark 3 Deployments with Hypervisor-Native Kubernetes
Explore integrating Spark 3 with VMware Pacific for scalable, reliable, and high-performance big data analytics deployments using hypervisor-native Kubernetes on vSphere 7.
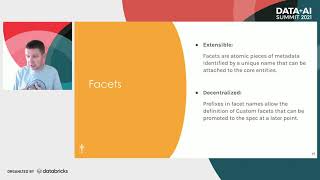
Observability for Data Pipelines with OpenLineage
Explore data pipeline observability using OpenLineage, enhancing reliability and auditability. Learn how metadata collection enables understanding of data flow and dependencies across teams and technologies.
Dumb-Proofing Data Pipelines: Techniques for Configurable and Maintainable ETL - Databricks
Techniques to create configurable, maintainable data pipelines. Learn to externalize configurations, validate inputs, and leverage Scala features for robust, easily deployable ETL processes.
Learn to Use Databricks for Data Science
Discover how Databricks simplifies data science with a unified platform for analytics workloads, from data preparation to predictive analytics, enhancing collaboration and productivity at scale.
Fully Utilizing Spark for Data Validation with Fugue and Pandera
Explore lightweight data validation for Spark using Fugue and Pandera, enabling partition-specific rules and efficient big data processing without compromising on functionality.
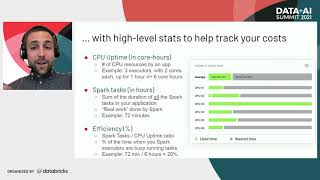
Delight - Improved Apache Spark UI for Performance Troubleshooting
Explore Delight, a free monitoring dashboard for Apache Spark. Learn to troubleshoot and optimize data engineering pipelines using system metrics and Spark information for improved performance and cost-effectiveness.