Deep Dive into New Features of Apache Spark 3.1
Explore Apache Spark 3.1's new features: ANSI SQL compliance, streaming enhancements, Python improvements, and performance optimizations for faster, easier, and smarter data processing.
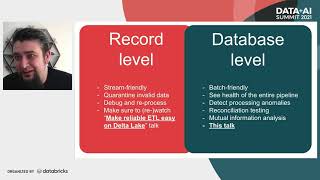
Data Quality Tools Comparison for Continuous Data Imports
Comparison of open-source data quality tools for continuous imports, covering maturity, documentation, extensibility, and features like data profiling and anomaly detection.
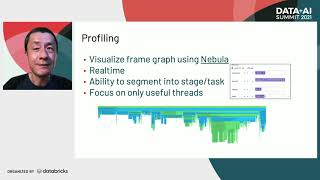
Migrating ETL Workflows to Apache Spark at Scale - Pinterest's Experience
Explore Pinterest's journey migrating ETL workflows to Apache Spark, covering challenges, solutions, and performance improvements. Learn about semantic gaps, thrift objects, and innovative Spark profiling techniques.
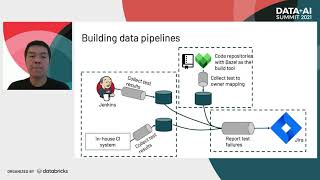
Managing Millions of Tests Using Databricks - Automated Monitoring and Reporting System
Explore automated test monitoring and reporting for Databricks Runtime using Delta, analyzing results from various sources to track quality and efficiently report failures to owners.
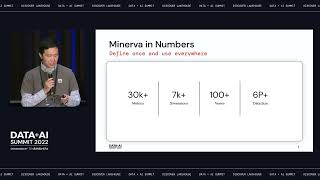
Democratizing Metrics at Airbnb - Minerva Platform Architecture and Future Plans
Explore Airbnb's Minerva platform for data consistency at scale, architectural improvements for flexibility, and plans for open-sourcing this centralized metrics solution.
Enable Production ML with Databricks Feature Store
Simplify production ML with Databricks Feature Store. Learn to overcome data challenges, enable real-time inference, and streamline ML projects using a unified data lakehouse platform integrated with Apache Spark and MLflow.

Delta Live Tables: Modern Software Engineering for ETL Pipelines
Learn how Delta Live Tables simplifies ETL, enhances data pipeline reliability, and automates tasks. Discover modern software engineering practices for efficient data transformation and improved analytics, data science, and ML outcomes.

Discover the Data Lakehouse: Simplifying Data Architecture for Analytics and ML
Explore the data lakehouse architecture for managing massive data, supporting diverse analytics and ML requirements across multi-cloud environments, and enabling data teams to derive value efficiently.
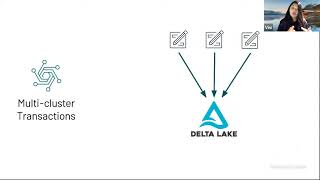
Delta Lake Roadmap 2021 H2 - Features Overview and Community Feedback
Overview of Delta Lake's 2021 roadmap, highlighting new features, integrations, and community-driven developments for enhanced data management and analytics capabilities.
Multi-Table Transactions with LakeFS and Delta Lake - Tech Talk
Explore multi-table transactions using LakeFS and Delta Lake for collaborative data lake management, enabling CI/CD deployment and simplified multi-table pipelines in cloud storage systems.
Master Databricks and Apache Spark - Introduction
Learn the fundamentals of Databricks and Apache Spark, exploring scale-up vs. scale-out concepts and laying the groundwork for mastering these powerful data processing tools.
Using SQL Window Functions in Databricks and Apache Spark - Lesson 16
Learn to leverage Spark SQL window functions for advanced data engineering on Databricks, including cumulative totals, ranking, and aggregations alongside detail rows, enhancing your data manipulation capabilities.

Understanding Spark SQL - Lesson 6
Explore Spark SQL's powerful features for data engineering, including query optimizations and support for Python, R, and Scala, enhancing parallel processing performance.
Using the Data Science Process - Lesson 5
Explore the data science process from project inception to completion, covering key steps for successful implementation in Databricks and Apache Spark projects.
Databricks Workspace Tour and Notebook Demo - Lesson 3
Comprehensive tour of Databricks Workspace, demonstrating tools and features with focus on the proprietary notebook IDE. Provides foundation for advanced Databricks and Apache Spark usage.
How Adobe Processes 2 Million Records Per Second Using Apache Spark
Explore Adobe's high-performance data processing using Apache Spark, covering optimization techniques, join strategies, structured streaming, skew handling, and integration with Redis for enhanced efficiency.
Automating FAA's SWIM Data Ingestion and Analysis with Databricks
Automating FAA's SWIM data ingestion and analysis using cloud-based services, showcasing infrastructure setup, configuration, and insights derived from flight data for improved air transportation management.
Delta from a Data Engineer's Perspective - Creating Robust Big Data Solutions
Explore a data engineer's challenges in creating robust Big Data solutions, covering Delta, Spark streaming, schema enforcement, and time travel functionality in data processing.
Composable Data Processing with Apache Spark - Scaling Development and Error Handling
Learn about SIP, an extensible plugin framework for Apache Spark that enhances data processing efficiency, error handling, and scalability in Adobe's Experience Platform.
Re-Imagining Apache Spark Development - Tools for Productivity and Standardization
Exploring next-gen tools for Apache Spark development, focusing on productivity, code standardization, metadata, lineage, and CI/CD agility to overcome limitations of traditional ETL tools.
Predictive Maintenance on IoT Data for Early Fault Detection with Delta Lake
Explore predictive maintenance using IoT data and Delta Lake for early fault detection. Learn about Industry 4.0 applications, data analytics, and machine learning techniques for improved efficiency and cost savings.