The Real Modern Data Stack - Building ETL Pipelines with Open Source Tools
Discover how to build powerful, cost-effective ETL data stacks using open-source tools like sling, dbt, duckdb, and dagster - transforming months of implementation into rapid deployment.
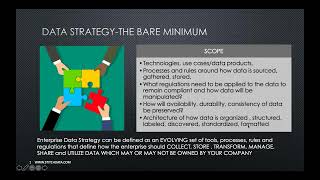
Data Planning to Implementation
Explore the journey from data planning to implementation, covering data strategy, maturity, roadmaps, and best practices for turning insights into actionable solutions across businesses.
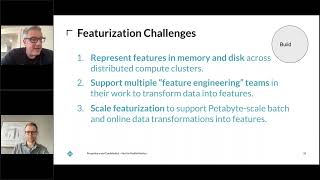
Streaming Featurization with Ibis, Substrait and Apache Arrow
Explore real-time streaming data processing using Ibis, Substrait, and Apache Arrow. Learn how this software stack enhances featurization workflows for fast, accurate insights and decision-making in data science.
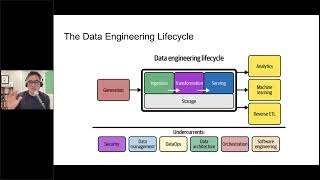
Getting Into Data Engineering
Explore data engineering career paths, industry changes, and essential skills with Joe Reis. Gain insights on transitioning from software engineering or data analysis roles and receive valuable career advice.
ODSC West 2015 - Cloud Native Data Science
Cloud-native design principles for data science applications: creating scalable, stateless models easily deployable in modern cloud systems. Insights on open-source platforms and best practices.
How Companies Are Using Tachyon, a Memory Centric Distributed Storage
Explore Tachyon, a memory-centric distributed storage system for fast big data processing. Learn about its benefits, use cases, and integration with popular frameworks like Spark and Hadoop.
Applying Engineering Best Practices in Data Lakes Architectures - Einat Orr
Explore engineering best practices for data lakes architectures, covering data infrastructure evolution, building blocks of data products, and practical tooling examples for effective data engineering.
Mastering Fake Business Data Creation in Python With Faker
Learn to generate realistic fake business data using Python's Faker library. Covers standard and community providers, creating diverse datasets, and integrating with Pandas for analysis.
How You Can Build Your Own Worldwide Wildfire Data Collection and Host on Kaggle
Learn to collect, process, and visualize global wildfire data using NASA sources, data engineering techniques, and tools like Kepler.gl, mapboxgl, and Streamlit for insightful analysis and presentation.
Modern and Postmodern Data Stack - Architecture and Why You Need It
Explore modern and postmodern data stack architectures, their features, and importance in data engineering. Learn why organizations need to evolve their data infrastructure for improved analytics and decision-making.
Data Engineering and Storage Concepts - With ETL, ELT, Warehouse, Lake, and Lake House
Comprehensive overview of data engineering concepts, including storage solutions, ETL/ELT processes, and modern data architectures like data mesh, with practical examples and best practices for effective data management.
Funnel Analysis with Apache Spark and Druid for Advertising Campaign Effectiveness
Learn to perform funnel analysis at scale using Apache Spark, Druid, and DataSketches. Discover techniques for measuring campaign effectiveness and analyzing user behavior in chronological order for large-scale advertising campaigns.
Introduction, Principles and Origin of Dagster
Introduction to Dagster: A data orchestrator for the entire application lifecycle. Covers principles, development, deployment, and monitoring. Includes demo and code snippets showcasing Dagit UI and Dagster programming model.
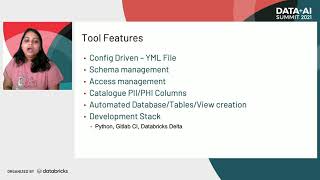
Automated Metadata Management in Data Lakes - A CI/CD Driven Approach
Discover a CI/CD-driven approach to automated metadata management in data lakes, focusing on balancing development speed, governance, and schema evolution for rapidly growing organizations.
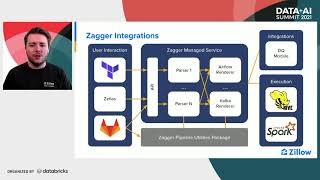
Empowering Developers with Self-Service ETL - Zillow's Approach
Zillow's self-service ETL solutions empower teams to build, maintain, and monitor data pipelines, abstracting complex processes and catering to diverse user needs while leveraging internal services for efficient implementation.
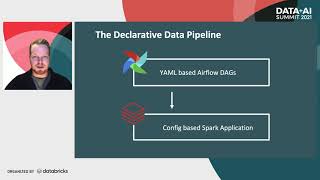
Code Once, Use Often - Declarative Data Pipelines
Learn to build efficient, reusable data pipelines using declarative approaches. Explore techniques for reducing food waste through data-driven solutions and automation in this developer-focused session.
Advancing GPU Analytics with RAPIDS Accelerator for Apache Spark and Alluxio
Learn to accelerate GPU analytics using RAPIDS for Apache Spark and Alluxio, enabling faster data access and processing for AI and analytics workloads across any cloud environment.
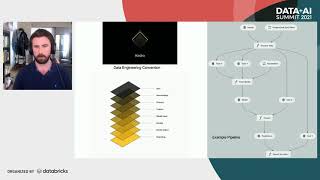
A Collaborative Data Science Development Workflow Using Kedro and MLflow
Explore a collaborative data science workflow using Kedro pipelines, MLflow tracking, and cloud-agnostic GPU containers for efficient model development, training, and production deployment.
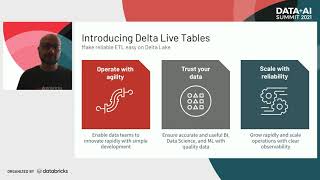
Make Reliable ETL Easy on Delta Lake
Learn to simplify ETL development on Delta Lake, improving data quality and scaling operations. Discover how Databricks streamlines the ETL lifecycle for efficient data engineering and management.
Delta Lake Streaming - Internals and Query Progress Logs
Explore Delta Lake streaming internals, focusing on structured streaming components, Query Progress Logs, and checkpoint directories for efficient real-time data pipeline management.
Building Data Quality Pipelines with Apache Spark and Delta Lake
Learn to build robust data quality pipelines using Apache Spark and Delta Lake. Explore rule templates, reporting models, and PowerBI integration for effective data remediation and self-healing in enterprise environments.