No More Runtime Setup - Bundling, Distributing, Deploying, and Scaling LLMs Seamlessly with Ollama Operator
Discover Ollama Operator: simplify LLM deployment, bundling, and scaling across environments. Eliminate runtime complexities and dependency issues for seamless large language model management in Kubernetes.
Create GUI App with Stable Diffusion, Docker, and Flask - Beginner Friendly
Learn to build a text-to-image AI app using Stable Diffusion, Docker, and Flask. Create high-res images from text prompts, explore Docker Init, CUDA, FreeU, and more in this beginner-friendly Python tutorial.
Linear Algebra Coming to Standard C++ - std::linalg
Explore std::linalg, a new C++ library for efficient linear algebra computations using modern C++ idioms. Learn its benefits, implementation, and potential impact on C++ development.
Foundation of GPU Programming
Explore GPU architecture, performance sources, and programming models. Gain insights into SIMD processing, DRAM parallelism, and software/memory hierarchies for confident GPU utilization.
Introduction to CUDA Programming for Physicists - Lecture 3
Explore GPU architecture, memory operations, CUDA kernels, and reduction operations. Learn to accelerate critical code sections using GPUs for physics computations.
Introduction to CUDA Programming for Physicists - Lecture 2
Explore GPU architecture, memory operations, CUDA kernels, and reduction techniques for physicists. Learn to accelerate critical code sections using GPUs and leverage specialized libraries.
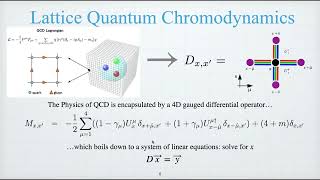
GPU Computing and Krylov Solvers
Explore GPU computing and Krylov solvers for advanced numerical computations, enhancing problem-solving skills in high-performance computing environments.
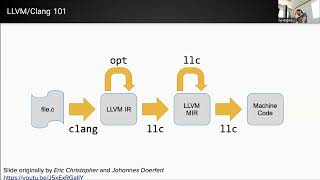
LLVM in HPC - Enabling Performance Portability, Interoperability, and Novel Features - Part 1
Explore LLVM's impact on HPC, covering portable CUDA, debugging at scale, GPU execution of legacy code, and ML in compilers. Learn about efforts to enhance performance, tooling, and development in HPC.
C++ Performance Portability - A Decade of Lessons Learned - Lecture
Explore a decade of C++ performance portability challenges and solutions, focusing on Kokkos ecosystem development for efficient cross-platform scientific computing.
Which GPU Sharing Strategy Is Right for You? A Comprehensive Benchmark Study Using Dynamic Resource Allocation
Explore GPU sharing strategies in Kubernetes using Dynamic Resource Allocation (DRA), comparing Multi-Instance GPUs, MPS, and CUDA Time-Slicing for optimal workload performance.

Pathfinder to GPU Offload in WASM
Explore GPU offloading in WebAssembly for AI workloads, discussing integration challenges and potential solutions to enhance security and performance in cloud environments.