Advancing CXL Memory Architecture for Enhanced Performance and Flexible Integration
Explore advanced CXL memory architecture concepts, focusing on performance optimization, integration strategies, and the latest developments in memory system design for modern computing platforms.
Overcoming the GPU Memory Capacity Limitation with Two-Digit Nanosecond Latency CXL Controller
Explore advanced solutions for GPU memory limitations through CXL controller technology, focusing on nanosecond-level latency optimization and enhanced capacity management.
Real World Implementation of the OCP Hyperscale CXL TME Specification
Explore practical implementations of OCP's Hyperscale CXL TME specification, examining real-world applications and technical considerations for memory expansion solutions.
Explainable AI to Increase Safe Use of AI - A Case of Manufacturing
Explore how explainable AI enhances safety and transparency in manufacturing processes, focusing on practical applications and implementation strategies.
Case for DRAM Translation Layer - It's Like FTL but for CXL DRAM
Explore the innovative DRAM Translation Layer technology and its application in CXL DRAM systems, drawing parallels with Flash Translation Layer for enhanced memory management.
A Blueprint for Liquid-Cooled AI Rack Clusters for Modern Datacenters
Discover best practices for AI cluster design and direct-to-chip liquid cooling solutions to optimize datacenter efficiency, boost productivity, and reduce operational costs.
Addressing Future Thermal Challenges Driven by AI - Data Center Cooling Solutions
Explore thermal management innovations and solutions for AI-driven computing challenges, focusing on liquid cooling technologies and power efficiency in modern data centers.
Enabling Sustainable AI Datacenters with ARM-based Chiplets
Discover how Arm's Total Design and Neoverse CSS enable sustainable AI datacenter solutions through innovative chiplet ecosystems, optimizing power efficiency for modern workloads.
Exploring the Inner Workings of Azure's Advanced AI Infrastructure
Delve into Azure's advanced AI infrastructure, exploring GPU architectures, networking technologies, and system designs powering modern AI model training and deployment at scale.
Open Network Switching for Hyperscale Cloud AI Infrastructure
Explore how open networking architectures can revolutionize cloud AI infrastructure, enabling greater flexibility, scalability, and innovation for hyperscale operators.
Optimizing Networks with Infrastructure Processing Units for Cloud and Enterprise
Discover how Infrastructure Processing Units (IPUs) revolutionize datacenter performance through secure workload acceleration, improved CPU utilization, and next-generation transport protocols for cloud and AI connectivity.
Modular Firmware for Modern Data Centers: A Collaborative Approach to Scalability and Security
Discover how modular open-source firmware frameworks drive innovation in data centers through scalable, secure solutions and industry collaborations for next-generation computing architectures.
Open Ecosystems in the Era of AI - Building Collaborative Infrastructure for Machine Learning
Explore how Google navigates AI infrastructure challenges through collaborative approaches to power delivery, cooling, security, and sustainability in modern computing ecosystems.
Applying Model-Based Systems Engineering to the Data Center Lifecycle
Discover how model-based systems engineering (MBSE) integrates stakeholder concerns and optimizes data center lifecycle management, from business goals to technical decisions and operational efficiency.
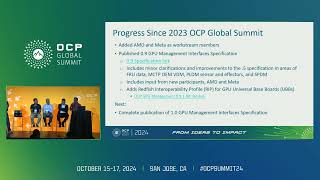
Standardizing Hyperscaler Requirements for GPU Management and Acceleration
Discover how leading tech companies are standardizing GPU management in hyperscale data centers using DMTF standards, focusing on accelerating implementation and adoption of new GPU designs.
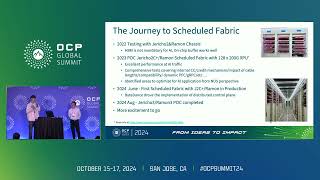
Insights from Production Scheduled Ethernet Fabric in Large AI Training Clusters
Discover how ByteDance implements Scheduled Ethernet Fabric to optimize networking performance and scalability in large-scale AI training clusters with thousands of xPU units.
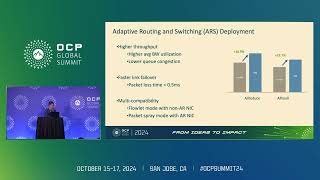
Optimal Path Utilization for Multi-Plane Fabric Design in Network Architecture
Explore advanced techniques for optimizing link utilization and throughput in multi-plane fabric networks, focusing on cross-rail communication and resilience strategies.
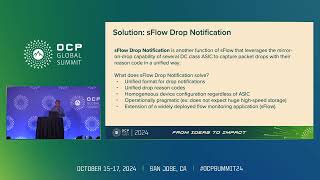
Leveraging Open Technologies to Monitor Packet Drops in AI Cluster Fabrics
Discover how to implement effective packet drop monitoring in AI clusters using open technologies like SAI and sFlow, optimizing network performance and troubleshooting capabilities.
Rethinking System Design for the New Wave of AI GPUs and CPUs
Explore innovative server design strategies for optimizing thermal management, power delivery, and performance in next-generation AI computing infrastructure with advanced GPUs and CPUs.
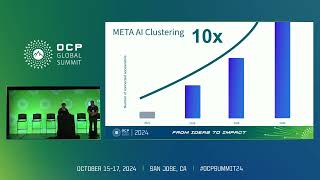
Data Center-Wide Rack Management and Beyond: Exploring Scalable Solutions for Gen AI Infrastructure
Explore how AI infrastructure transforms data center rack management, focusing on scalable solutions, system interdependency, and holistic approaches for next-generation computing needs.
SPDM Authorization Specification - A Standardized Framework for Protected Actions
Discover how SPDM Authorization Specification enables secure endpoint authorization through standardized frameworks, credential provisioning, and threat modeling for protected actions.