Audio Processing in Keras with Kapre
Learn to process audio in Keras using Kapre, exploring its advantages, features, and implementation. Discover how to embed audio transformations within deep learning models for optimized GPU-based calculations and easier deployment.
Generating Sound Digits with a Variational Autoencoder
Learn to generate audio spectrograms of sound digits using a trained Variational Autoencoder, then convert them into audio. Includes implementation, scripting, debugging, and result evaluation.
OpenAI Whisper - Translate and Transcribe Your Video and Audio at Command Line
Comprehensive walkthrough of OpenAI Whisper for multilingual speech recognition, translation, and transcription using command-line interface, with practical demonstrations across various audio formats.
tinyML Trailblazers: Success Stories with Mouna Elkhatib
Explore tinyML success with Mouna Elkhatib, AONDevices CEO. Learn about voice processing innovations, entrepreneurial challenges, and future trends in edge AI and IoT technologies.
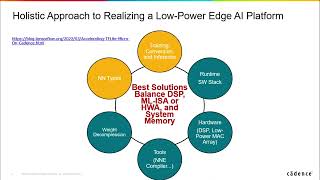
Dissecting a Low Power AI/ML Edge Application - Noise Suppression
Explore noise suppression in AI/ML edge applications, focusing on energy-efficient implementation for battery-powered devices and software frameworks for optimal user experience.
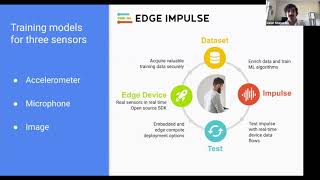
How to Train and Deploy TinyML Models for Three Common Sensor Types
Learn to train and deploy tinyML models for sensor, audio, and vision data using Edge Impulse. Explore workflows, best practices, and optimization techniques for embedded machine learning applications.
Ultra-Low-Power Command Recognition for Ubiquitous Devices
Explore ultra-low-power command recognition for ubiquitous devices, covering noise challenges, system goals, core functions, training, and implementation on tiny hardware.
24 Key AI Updates and News in 26 Minutes
Comprehensive overview of recent AI advancements, including updates from major tech companies, new AI models, and emerging technologies in voice, vision, and language processing.
Dynamic vCPU Priority Boosting in KVM for Latency-Sensitive Workloads
Exploring a framework for host-guest communication in KVM to minimize VM latencies by dynamically boosting vCPU thread priorities based on guest scheduling needs and host insights.
The Digital Hearth: An Automated Group Speech-to-Text System for Community Conversations
Explore an innovative group conversation recording device designed to capture and analyze community discussions, featuring offline operation and advanced speech recognition capabilities.
Reproducing Karpathy's GPT-2 for Audio - ML Scientist's Approach
Explore the reproduction of Karpathy's GPT-2 model for audio, showcasing innovative applications of machine learning in sound processing and generation.
Multimodal Q&A RAG Tool with Gemini for Data Science and Machine Learning
Develop a multimodal Q&A RAG tool using Gemini for unstructured data analysis, enhancing data science and machine learning capabilities.
D-Flow: Differentiating through Flows for Controlled Generation
Explore D-Flow framework for controlled generation in AI models, optimizing source points through flow differentiation. Learn applications in inverse problems and conditional generation.
Multilingual and Code-Switching Speech Recognition
Explore multilingual and code-switching speech recognition techniques, enhancing your understanding of advanced language processing methods.
Multilingual Speech-to-Speech Translation for Under-Resourced Languages
Explore multilingual speech-to-speech translation techniques for under-resourced languages, focusing on encoding, decoding, and analysis strategies.
New Directions in Robust Automatic Speech Recognition - 2005
Explore robust speech recognition techniques, from classical approaches to modern methods addressing complex acoustic environments and non-stationary noise challenges.
PREEMPT_RT Isn't Just for Lasers - The Perfect Match for Hearing Aid Research
Explore digital hearing aid development using Linux kernel, GNU tools, and Debian. Learn about openMHA, a toolbox for hearing aid algorithms, and Mahalia, a mobile research platform for low-latency audio processing.
Rapid Radio Reversing
Explore wireless security research techniques combining SDR and non-SDR tools. Learn efficient reverse engineering processes for analyzing and decoding radio signals in this hands-on demonstration.
Audio Classification with Machine Learning
Learn practical techniques for audio classification using machine learning, including spectrograms, CNNs, and transfer learning. Explore applications in speech, music, medical diagnostics, and more using Keras and TensorFlow.
Keep it Clean - Why Bad Data Ruins Projects and How to Fix It
Explore data quality issues in ML projects, their impact, and solutions. Learn to identify and fix bad data for improved project outcomes and performance.
Changing Live Audio with the Web-Audio-API
Explore the web-audio-api to recreate guitar effect pedals digitally, learning about audio nodes and live sound manipulation techniques.