
Building a WebApp to Summarize YouTube Reviews with LLMs
Learn to create a webapp that summarizes YouTube product reviews using AssemblyAI's LLM framework. Extract key points, generate pros and cons lists, and save time when researching purchases.
Using Vector Databases for Multimodal Embeddings and Search
Explore multimodal machine learning for cross-modal search at scale. Learn to implement natural search interfaces using open-source models and vector databases for billion-object retrieval.
Home Multimedia and Automation Systems with GStreamer
Explore GStreamer's network synchronization for distributed audio capture, enabling speaker isolation and echo-location in home automation systems.
Deep Learning Module for Video Sound Recognition Using Azure Video Indexer
Discover how to enhance video transcription by integrating Azure Video Indexer with Databricks, implementing machine learning models for audio recognition and spectrogram classification.
The iPhone Moment of AI - Natural Language Processing and Generative AI Revolution
Explore the transformative impact of Generative AI and NLP, from GPT-3's capabilities to practical applications in text generation and voice cloning, while addressing ethical considerations and corporate implementation.
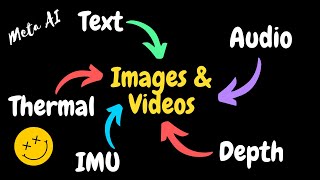
ImageBind: A Multi-Modal AI Model for Unified Embedding Space
Explore Meta AI's ImageBind technology and its groundbreaking approach to unified AI learning across six modalities, from technical architecture to practical applications and results.
Transformers Explained - Part 1: Generative Music AI
Comprehensive exploration of transformer architectures in AI, covering intuition, theory, and mathematical formalization, with focus on their application in music and audio processing.
Google Gemini AI: Comprehensive Overview and Capabilities
Explore Google's Gemini AI: a multimodal model excelling in programming, scientific analysis, math reasoning, and creative tasks. Witness its capabilities in understanding diverse data types and generating innovative solutions.
Few-Shot Learning for Health: How Sleep Cycle Separates Multiple People's Snoring
Discover how Sleep Cycle uses few-shot learning to differentiate snoring sounds, enhancing sleep analysis and health insights. Learn about the importance of snoring detection for overall well-being.
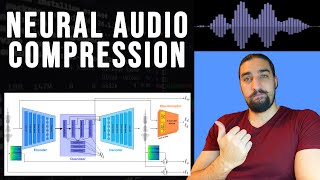
High Fidelity Neural Audio Compression - Paper & Code Explained
Explore neural audio compression techniques achieving 10x compression rates, with in-depth analysis of paper and code implementation, including VQ-VAE, VQ-GAN, and AudioGen applications.
Let's Build a Music Recommender!
Build a music recommender using AudioSet dataset, embedding generation, and ANNOY for efficient similarity search. Learn to process audio data and create a recommendation engine.
OpenAI Embeddings with Voice Cloning - Eleven Labs API, ChatGPT API, Whisper API
Learn to build a voice assistant using OpenAI Embeddings, ChatGPT, Whisper, and Eleven Labs APIs. Combine AI technologies for realistic voice responses and create a custom Q&A system with a Gradio UI.

Building a Machine Learning Drowsiness Detector App with Sound Alerts
Build a ML drowsiness detector app with PyTorch YOLOv5 and Tkinter. Detect awake/drowsy states, play alerts for sleeping, and learn object detection implementation in a practical application.

Building an AI Rap God - Cloning a Rapper Using Machine Learning
Learn to create an AI-powered rap generator using Python, combining text generation, voice cloning, and lip-syncing technologies to produce custom rap performances.
Attempting to Clone My Voice Using ML
Explore voice cloning with machine learning using CorentinJ's package. Setup, test, and develop on your PC using Python in this hands-on coding livestream.
Can We Clone My Voice Using ML?
Explore voice cloning with machine learning using CorentinJ's package. Setup, test, and develop on your PC using Python in this hands-on live stream.
Sound Programming on the X68000 with ChibiSound Pro - Lesson P43
Explore sound programming on the x68000 using ChibiSound Pro. Learn hardware abstraction, testing, music coding, and sound creation techniques for this classic computer system.
Listening at the Cocktail Party - Deep Neural Networks for Speech Separation
Explore deep neural networks for speech separation, focusing on data preparation, network architectures, and real-time implementation on embedded devices for smart audio applications.

Industry Shocking Text-To-Music AI Model by Facebook Audiocraft - Full Tutorial - Better Than MusicLM
Learn to use Facebook's Audiocraft AI model for text-to-music generation. Install, run, and experiment with this powerful tool on your computer or Google Colab to create amazing AI-generated music.
Multi-Way Analysis - The Algorithm
Explore the alternating least squares algorithm for multi-way analysis, focusing on PARAFAC modeling in chemometrics. Learn about notation, potential problems, and alternative approaches.

Understanding Audio Data for Deep Learning
Explore fundamental audio processing concepts for deep learning, including waveforms, pitch, Fourier transform, and MFCCs, essential for AI applications in sound analysis.