Web Scraping Puppy Data with Microsoft Fabric - 1st Leg
Explore CSS Selectors for web scraping in Power Query, m code, and PySpark Notebooks within Microsoft Fabric's Azure cloud environment.
Auditing PDFs for 508 Compliance at Scale - Workshop
Learn techniques for auditing large volumes of PDFs for 508 compliance, preparing for Drupal migration, and creating accessible content from the start. Explore tools, strategies, and participatory design principles.
Fine-Tune T5 for Document Classification - Part 1: Creating Dataset with Web Scraping
Personalize Flan-T5 for document classification by creating a custom dataset using web scraping techniques with DuckDuckGo.
RAG with Llama 3.1 for Google Trends Data Scraping and Summarization - Streamlit Web App
Discover how to build a RAG pipeline using LLaMA 3.1 to automate article discovery and summarization based on Google Trends, showcased in a Streamlit web app for efficient content curation.
Web Scraping, Screenshotting and Automated Testing with Playwright - Tutorial
Automate web tasks with Playwright: scraping, screenshotting, and testing. Learn efficient techniques for web automation and data extraction.
Build Web Scraper with Llama 3.1 - Get Structured Data by Scraping Web Content with AI
Learn to build a web scraper using Llama 3.1 AI to extract structured data from web pages. Create Pydantic models from markdown content, ideal for developers seeking efficient data extraction techniques.
Python Web Scraping for Beginners - Extracting Data from News Websites
Learn to extract valuable data from news websites using Python and BeautifulSoup. Master HTML parsing, efficient script writing, and data cleaning techniques for effective web scraping.
Having Fun with Python: Originating and Processing Data for Innovative Visualization and Analytics
Extract and process data with Python to answer quirky questions and create innovative visualizations for data-driven insights.
Scaling Structured Concurrency with Async Python
Discover how to leverage async Python for structured concurrency, exploring error handling, timeouts, and cancellation while learning to write elegant concurrent code using tools like flake8-trio and dynamic analysis.

Live-Coding: Master Anti-Ban and Web Scraping with Scrapoxy
Master web scraping techniques and anti-ban strategies using Scrapoxy, Scrapy, and Playwright. Learn proxy handling, code deobfuscation, and effective methods to bypass anti-bot systems.
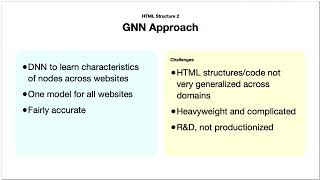
Web Extraction with Large Language Models - Lessons from Parsing Billions of Webpages
Discover cutting-edge techniques for web scraping and data extraction using Large Language Models, drawing from Pinterest's experience of parsing billions of webpages daily.
RAG: Nvidia NIM Integration with Langchain for HTML Web Page Parsing
Descubre cómo implementar aplicaciones RAG utilizando Langchain y Nvidia NIM para extraer información de páginas HTML, integrando el modelo Mistral 8 7b Instruct para procesamiento avanzado.
RAG - Parsing HTML Content with BeautifulSoup and Nvidia NIM Integration in LangChain
Dive into building RAG systems by integrating Nvidia NIM with LangChain, using BeautifulSoup for HTML parsing and Mistral 8 7b Instruct as the foundation model.
An Audacious Plan to Halt the Internet's Enshittification
Explore how internet platforms evolve from user-friendly to exploitative, and discover practical solutions including antitrust measures, privacy laws, and user empowerment tools to combat digital degradation.
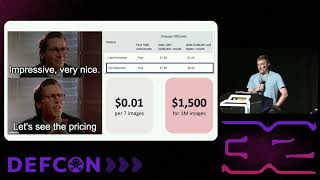
Secret Life of Rogue Devices: Lost IT Assets on the Public Marketplace
Uncover the alarming journey of lost corporate devices in public markets through data scraping, OCR clusters, reverse engineering, and conversations with underground collectors.
Using the Wolfram Stack and LLM Tech to Combat Misinformation on SDGs and ESG
Leverage Wolfram's LLM tech and core tools to combat misinformation on SDGs and ESG investing, building effective solutions for accurate information dissemination.
Building a Data Science Project in JavaScript
Build a data science project in JavaScript using Crawlee for web scraping and Apify for data processing. Learn to extract, analyze, and visualize insights from online sources.
Preparing Fineweb - A Finely Cleaned Common Crawl Dataset for Language Models
Explore Common Crawl data processing, comparing datasets like C4 and RefinedWeb. Learn about quality filters, deduplication strategies, and LLM-assisted filtering for creating high-quality datasets like Fineweb Edu.

Python AI Web Scraper Tutorial - Using AI to Scrape Any Website
Learn to build an AI-powered web scraper using Python, Selenium, BeautifulSoup, and LangChain. Extract specific information from websites with AI-driven parsing and overcome common scraping challenges.
Notion Database Assistant and EmailSpy Development - Day 10 Update
Explore AI-powered Notion Database Assistant development, including collaboration on EmailSpy, cloning for different schemas, and enhancing search capabilities within Notion pages.
Website Scraping with ChatGPT API - Python and Beautiful Soup 4
Learn to scrape websites using Python, Beautiful Soup 4, and ChatGPT API. Covers legal aspects, text extraction, summarization, and tagging techniques for efficient web data processing.