Rousillon - Scraping Distributed Hierarchical Web Data
Novel web scraping tool enabling efficient collection of hierarchical data across multiple pages. Demonstrates 8x faster scraper creation through programming by demonstration, benefiting data scientists and researchers.
Using Online Activity as Digital Fingerprints to Create a Better Spear Phisher
Explore data mining and NLP techniques to profile online activity, creating digital fingerprints for enhanced social engineering. Learn to analyze user interactions, vocabulary, and communication patterns.
It's Officially Legal so Let's Scrape the Web
Learn Python web scraping techniques to automatically collect data from websites, covering HTML basics to advanced pipeline methods for dataset compilation.
From Spreadsheets to DataFrames
Learn to transition from spreadsheets to Python DataFrames, exploring web scraping, data processing, analysis, and visualization using popular libraries like Pandas and Matplotlib. Gain skills for efficient data management and problem-solving.
Scraping Techniques to Extract Advertisements from Web Pages
Learn effective web scraping methods to extract advertisements from websites, focusing on techniques for handling dynamic content and overcoming common challenges.
Scraping Techniques to Extract Advertisements from Web Pages
Learn effective web scraping methods for extracting advertisements, focusing on techniques to navigate complex page structures and overcome common challenges in data extraction.
Web Scraping in Python 101
Learn web scraping in Python: techniques, libraries, and best practices. Explore BeautifulSoup, lxml, and Scrapy for efficient data extraction from websites.
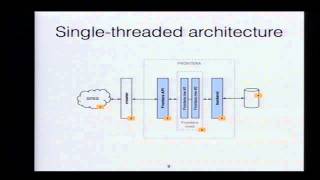
Frontera - Open Source Large-Scale Web Crawling Framework
Introduction to Frontera, an open-source framework for building large-scale web crawlers. Learn about its features, architecture, and how to create distributed crawlers using Scrapy, Kafka, and HBase.
Web Scraping Best Practices
Explore advanced web scraping techniques in Python, covering automated extraction, rendering pages, proxy management, and scalable crawl architecture for challenging real-world projects.
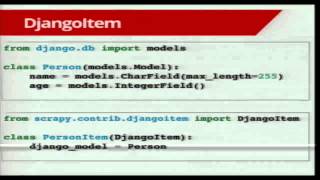
Dive into Scrapy
Explore advanced Scrapy techniques for web scraping, including project structure, interactive shell, item handling, and deployment strategies. Learn to avoid bans and optimize data extraction.
Beyond Scraping
Discover advanced techniques for extracting data from dynamic, JavaScript-driven websites using a client-server architecture with zeromq, selenium, and beautifulsoup. Streamline your web scraping process for efficiency and robustness.
Data Ingestion and Big Data
Learn web scraping, crawling, and API usage for data retrieval. Explore technical and ethical considerations in simulating user navigation and leveraging data APIs for analysis and business opportunities.
Leveraging Linked Data Using Python and SPARQL
Explore Python and SPARQL to extract structured knowledge from Wikipedia, creating datasets and corpora for data science projects without traditional web scraping techniques.
Piratin' the YQL Way
Explore YQL's powerful data manipulation capabilities and learn how to leverage it for efficient web scraping and data extraction.
Automate Your City Data With Python Using Datasette and GitHub Actions
Discover how to build automated data pipelines using Python, Datasette, and GitHub Actions to extract and analyze city planning decisions and public data for better civic engagement.
Finding Hidden Gems in Temporary Mail Services - Monitoring and Security Analysis
Discover how to monitor temporary email services using a Python tool to uncover valuable information, from account credentials to bitcoin wallets, while learning about security implications and red team activities.
Using ChatGPT to Write Python Web Scrapers - Demonstration and Cautions
Explore using ChatGPT to build web scrapers in Python, including benefits and potential pitfalls. Learn to refine prompts and understand limitations of AI-generated code.

Email Unsubscription Automation with Python Tutorial
Learn to automate email management by creating a Python script that finds and processes unsubscribe links in Gmail, helping declutter your inbox efficiently and save time.
Web Scraping Puppy Data with Microsoft Fabric - 1st Leg
Explore CSS Selectors for web scraping in Power Query, m code, and PySpark Notebooks within Microsoft Fabric's Azure cloud environment.
Web Scraping Puppy Data with Microsoft Fabric - 2nd Leg
Learn web scraping techniques using CSS Selectors in Power Query, m code, and PySpark within Microsoft Fabric to extract puppy data from websites.
Web Scraping Puppy Data with Microsoft Fabric - 2nd Leg
Learn web scraping techniques using CSS Selectors in Power Query, m code, and PySpark within Microsoft Fabric to extract puppy data from websites.